using Pumas
using DataFramesMeta
using PumasUtilities
using Random

# Set a seed for reproducibility
Random.seed!(2142)
NONMEM style BQL models (M1-M4) models in Pumas
TipWebinar
This tutorial is about handling the missing data problem related to observations being outside the limits of quantification. In 2022, we held a webinar about the theory of such statistical modeling. It was recorded and is available on YouTube. The video is embedded below.
Before we begin we need to load the necessary packages and set a seed for reproducibility.
1 Handling Lower Limit of Quantification
In the real world, assays often come with limitations such as lower or upper limits of quantification. When pharmacometricians receive data it has often been processed by the lab or by statisticians in other departments. The data can have various levels of information about the measured concentration if it was at or below the Lower Limit of Quantification (LLOQ). Unfortunately, such measurements are often simply labeled "BQL" in the dependent variable column to indicate that the measurement was taken but it was Below Quantification Limit (BQL). If the value was provided it could be modelled in a more explicit manner, but with just BQL indications, we need to treat it as a missing data problem.
In pharmacometrics, the main references on how to handle this kind of data are Beal (2001) for a conceptual description and Bergstrand and Karlsson (2009) for a simulation exercise. These papers use the M1-M7 nomenclature of the former. In Pumas, we try to always refer to observations according to their actual distributional assumptions or data transformation steps. In this tutorial, we will try to use both to ease the transition for a NONMEM workflow to a Pumas workflow. The discussions around M* methods assumes familiarity with the nomenclature described in the above papers. See our other tutorials for BQL introductions that do not directly refer to NONMEM methods if you are not transitioning from NONMEM to Pumas, as the discussion in terms of M* methods is mostly done for legacy reasons.
2 Definitions
Before we start, we need to define some terms:
Truncation is a statistical term that refers to the removal of data points that fall outside a certain range. In the context of pharmacometrics, truncation is used to remove data points that fall below the lower limit of quantification (LLOQ). Mathematically, say that \(X\) is our dependent variable, i.e. the quantity we want to measure:
\[X \sim N(\mu, \sigma^2)\]
\(X\) is generally measured with some instrument. To account for the fact that the instrument might have some limitations, we generally observe in our dataset either the truncated or censored values of \(X\). We denote \(Y^t\) as the truncated value of \(X\) and \(Y^c\) as the censored value of \(X\).
In truncation, we observe the value of \(X\) if it is between lower and higher thresholds, \(a\) and \(b\), respectively. For some reason, the data processing step has removed the data points that fall outside this range. We can represent a truncated variable \(Y^t\) as:
\[Y^t = X \mid a \leq X \leq b\]
The censoring case is different. In censoring, we observe the value of \(X\) if it is above a certain threshold, \(a\); or below a certain threshold, \(b\). The censored variable \(Y^c\) is then:
\[Y^c = \min(\max(X, a), b)\]
Here are examples of truncation and censoring:
- Truncation (missing information): A device measures a plasma concentration. We only see data points if they are within the truncation limits.
- Censoring (missing information): A device measures a plasma concentration as before. However, below some measurement value (LLOQ) the number cannot be trusted so we only know that our measurement is below that value.
NoteData Truncation versus Truncated Distribution
There’s a difference between data truncation and a truncated distribution. Data truncation refers to the removal of data points that fall outside a certain range, whereas a truncated distribution is a probability distribution that is restricted to a certain range. It assumes that the Data Generating Process (DGP) is truncated. In the sense that the data is generated from a distribution that is truncated.
For example an assay that cannot return negative values, or a measurement device that cannot measure values above a certain threshold. In these cases the Normal distribution, which originally has support on the entire real line, is truncated to a certain range.
3 Generating data
To study a specific statistical phenomenon and properties of any estimator it is often important to be able to separately specify:
- the Data Generating Process (DGP); and
- the estimation procedure or estimator.
The data in this tutorial will come from a simple, simulated data set with 90 subjects that receive an injection of 200 units at time 0. The assay used to measure the concentration of the drug in plasma has a Lower Limit of Quantification (LLOQ) of 0.9 units of the concentration. By the simple properties of a two compartment model with linear elimination rate, all subjects will eventually have concentrations that are sufficiently low that samples will have a chance to be Below the Quantification Limit (BQL). The error model is a combined error model. With such a distribution we can have observations that are not BQL even at high t (model time), but the proportion of BQL values should be increasing over time.
Notice, that the above type of BQL observations is only one type of many. The proportion of BQL is simply a function of time. In some cases, the probability of a being BQL may be a function of covariates as well. Some patients may have a higher volume of distribution for example. This does not change how we handle the issue statistically, but it may affect how we decide whether or not to ignore or explicitly handle the BQL issue. You could argue that you should always explicitly handle the BQL values, but the choice may not be so simple. The methods that explicitly model the BQL values in a statistical manner require the use of the LaplaceI method if we are using first order approximation methods. This method is known to be slower and sometimes less numerically robust than FOCE. For this reason, an analyst may choose to only use BQL methods if the bias from simply ignoring the problematic observations is expected to be high. An alternative is to use Expectation-Maximization (EM) methods such as SAEM. The treatment of such an approach is done in a separate tutorial.
4 Data Generating Process
The Data Generating Process (DGP) consists of the specification of:
- the population
- the doses
- the sampling times
- the model
- the parameters
4.1 The population, doses, and sampling times
As mentioned previously, each subject is dosed 200 units of the drug at time zero. There are 90 subjects in total and we sample their plasma at the time of dosing and each hours thereafter for twelve hours.
pop = [
    Subject(
        id = string(i),
        events = DosageRegimen(200),
        time = [1.0, 3.0, 5.0, 7.0, 9.0, 11.0],
    ) for i = 1:90
]
This population is empty in the sense that it has no simulated observations yet. To do that, we need to define a model and the parameters.
4.2 The Model
The following model can be seen as a model for the distribution and elimination of the drug (the dynamical model) as well as the values from the assay (the derived block) without any masking of BQL values.
iv2cmt_dgp = @model begin
    @param begin
        θcl ∈ RealDomain(lower = 0.1)
        θvc ∈ RealDomain(lower = 1.0)
        θq ∈ RealDomain(lower = 0.1)
        θvp ∈ RealDomain(lower = 1.1)
        Ω ∈ PDiagDomain(2)
        σ_add ∈ RealDomain(lower = 0.0)
        σ_prop ∈ RealDomain(lower = 0.0)
    end

    @random begin
        η ~ MvNormal(Ω)
    end

    @pre begin
        CL = θcl * exp(η[1])
        Vc = θvc * exp(η[2])
        Q = θq
        Vp = θvp
    end

    @dynamics Central1Periph1

    @derived begin
        conc_model := @. Central / Vc
        CONC ~ @. CombinedNormal(conc_model, σ_add, σ_prop)
    end
end
PumasModel
Parameters: θcl, θvc, θq, θvp, Ω, σ_add, σ_prop
Random effects: η
Covariates:
Dynamical system variables: Central, Peripheral
Dynamical system type: Closed form
Derived: CONC
Observed: CONCWe can also choose some parameters to simulate from:
param0 = (;
    θcl = 2.9,
    θvc = 7.0,
    θq = 1.8,
    θvp = 9.0,
    Ω = Diagonal([0.09, 0.09]),
    σ_add = sqrt(0.03),
    σ_prop = sqrt(0.03),
)
(θcl = 2.9, θvc = 7.0, θq = 1.8, θvp = 9.0, Ω = Diagonal([0.09, 0.09]), σ_add = 0.17320508075688773, σ_prop = 0.17320508075688773)4.3 A simulated population
To simulate the population, we simple use simobs and the objects defined above.
simpop = simobs(iv2cmt_dgp, pop, param0)
DataFrame(simpop)
simpop carries the simulated information about the assay, but does not yet apply the BQL masking. This is done in the next step.
4.4 Lower Limit Of Quantification (LLOQ)
In this example, we will assume that our assay has a lower limit of quantification at 0.9. We can convert our simulated population to a tabular format (DataFrame) and calculate what rows are BQL. This information can be used to produce plots showing the censoring, and to create our masked dependent variable.
lower_limit = 0.9
pkdata = DataFrame(simpop)
pkdata.LLOQ .= lower_limit
@rtransform! pkdata :BQL = :CONC <= :LLOQ
pkdata_obs = filter(x -> x.evid == 0, pkdata)
4.4.1 Calculating proportions BQL by time
To investigate whether censoring of the dependent variable is an issue or not, we can calculate the proportion of BQL at each observation time.
pkdata_obs_gdf = groupby(pkdata_obs, :time)
pkdata_obs_gdf_comb = combine(pkdata_obs_gdf, :BQL => mean => "BQL_proportion")
6×2 DataFrame
| Row | time | BQL_proportion |
|---|---|---|
| Float64 | Float64 | |
| 1 | 1.0 | 0.0 |
| 2 | 3.0 | 0.0 |
| 3 | 5.0 | 0.0111111 |
| 4 | 7.0 | 0.0888889 |
| 5 | 9.0 | 0.2 |
| 6 | 11.0 | 0.311111 |
We see that the value of the BQL_proportion column is increasing, and towards the end we do have a fair amount of BQL values. Another way to investigate this number is in a plot.
4.4.2 Visualizing BQL proportions
Let us visualize the effect of the censoring in the following plot.
Show/Hide Code
using AlgebraOfGraphics

f = AlgebraOfGraphics.Figure()
f1 = draw!(
    f[1:2, 1],
    data(pkdata_obs) *
    mapping(:time, :CONC => "CONC", color = :BQL) *
    visual(AlgebraOfGraphics.Scatter) +
    mapping([lower_limit], [0.0]) * visual(AlgebraOfGraphics.ABLines; color = :orange),
    scales(Color = (; palette = [:black, :orange]));
    axis = (; xlabel = "",),
)
f2 = draw!(
    f[3, 1],
    data(pkdata_obs_gdf_comb) *
    mapping(:time, :BQL_proportion => "BQL proportion") *
    visual(AlgebraOfGraphics.Scatter; color = :orange);
    axis = (limits = (nothing, nothing, 0, 1),),
)
legend!(f[1:2, 2], f1)
f
In the bottom panel, we see that the proportion of BQL values increases over time. The censoring is a little bit hard to see. In the next plot, it is easier to see the effect when we plot the y-axis as the log-transformed variable.
Show/Hide Code
using AlgebraOfGraphics

f = AlgebraOfGraphics.Figure()
f1 = draw!(
    f[1:2, 1],
    data(pkdata_obs) *
    mapping(:time, :CONC => log => "log(CONC)", color = :BQL) *
    visual(AlgebraOfGraphics.Scatter) +
    mapping([log(lower_limit)], [0.0]) * visual(AlgebraOfGraphics.ABLines; color = :orange),
    scales(Color = (; palette = [:black, :orange]));
    axis = (; xlabel = ""),
)
f2 = draw!(
    f[3, 1],
    data(pkdata_obs_gdf_comb) *
    mapping(:time, :BQL_proportion => "BQL proportion") *
    visual(AlgebraOfGraphics.Scatter; color = :orange);
    axis = (; limits = (nothing, nothing, 0, 1)),
)
legend!(f[1:2, 2], f1)
f
4.5 Masking the data
As mentioned in the introduction, real world data often comes without the assay values if they are BQL.
pkdata_censored = copy(pkdata)
@rtransform! pkdata_censored :CONC = max(:LLOQ, :CONC)
first(pkdata_censored, 20)
20×22 DataFrame
| Row | id | time | CONC | evid | amt | cmt | rate | duration | ss | ii | tad | dosenum | Central | Peripheral | η₁ | η₂ | CL | Vc | Q | Vp | LLOQ | BQL |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| String | Float64 | Float64? | Int64? | Float64? | Symbol? | Float64? | Float64? | Int8? | Float64? | Float64? | Int64? | Float64? | Float64? | Float64? | Float64? | Float64? | Float64? | Float64? | Float64? | Float64 | Bool? | |
| 1 | 1 | 0.0 | missing | 1 | 200.0 | Central | 0.0 | 0.0 | 0 | 0.0 | 0.0 | 1 | missing | missing | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | missing |
| 2 | 1 | 1.0 | 17.9539 | 0 | missing | missing | missing | missing | missing | missing | 1.0 | 1 | 50.6759 | 57.7767 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 3 | 1 | 3.0 | 3.59012 | 0 | missing | missing | missing | missing | missing | missing | 3.0 | 1 | 10.6936 | 59.8385 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 4 | 1 | 5.0 | 1.89758 | 0 | missing | missing | missing | missing | missing | missing | 5.0 | 1 | 7.24901 | 48.6145 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 5 | 1 | 7.0 | 1.99616 | 0 | missing | missing | missing | missing | missing | missing | 7.0 | 1 | 5.75758 | 39.0359 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 6 | 1 | 9.0 | 1.62626 | 0 | missing | missing | missing | missing | missing | missing | 9.0 | 1 | 4.61737 | 31.3244 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 7 | 1 | 11.0 | 0.9 | 0 | missing | missing | missing | missing | missing | missing | 11.0 | 1 | 3.70496 | 25.1354 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | true |
| 8 | 2 | 0.0 | missing | 1 | 200.0 | Central | 0.0 | 0.0 | 0 | 0.0 | 0.0 | 1 | missing | missing | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | missing |
| 9 | 2 | 1.0 | 12.8523 | 0 | missing | missing | missing | missing | missing | missing | 1.0 | 1 | 102.014 | 47.5713 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 10 | 2 | 3.0 | 8.46052 | 0 | missing | missing | missing | missing | missing | missing | 3.0 | 1 | 38.0232 | 68.2487 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 11 | 2 | 5.0 | 4.2123 | 0 | missing | missing | missing | missing | missing | missing | 5.0 | 1 | 23.0299 | 63.0127 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 12 | 2 | 7.0 | 3.32903 | 0 | missing | missing | missing | missing | missing | missing | 7.0 | 1 | 17.7494 | 54.2878 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 13 | 2 | 9.0 | 3.54978 | 0 | missing | missing | missing | missing | missing | missing | 9.0 | 1 | 14.6831 | 46.0971 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 14 | 2 | 11.0 | 2.82836 | 0 | missing | missing | missing | missing | missing | missing | 11.0 | 1 | 12.3548 | 39.0171 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 15 | 3 | 0.0 | missing | 1 | 200.0 | Central | 0.0 | 0.0 | 0 | 0.0 | 0.0 | 1 | missing | missing | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | missing |
| 16 | 3 | 1.0 | 21.4362 | 0 | missing | missing | missing | missing | missing | missing | 1.0 | 1 | 81.4514 | 51.2734 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
| 17 | 3 | 3.0 | 6.00094 | 0 | missing | missing | missing | missing | missing | missing | 3.0 | 1 | 23.4483 | 64.5451 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
| 18 | 3 | 5.0 | 3.0174 | 0 | missing | missing | missing | missing | missing | missing | 5.0 | 1 | 14.0357 | 55.8149 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
| 19 | 3 | 7.0 | 2.37679 | 0 | missing | missing | missing | missing | missing | missing | 7.0 | 1 | 10.9155 | 46.2582 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
| 20 | 3 | 9.0 | 2.04447 | 0 | missing | missing | missing | missing | missing | missing | 9.0 | 1 | 8.9062 | 38.1072 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
Here LLOQ is the variable defined above, and has the value of 0.9. This type of dataset has the dependent variable column set to the actual LLOQ. The data sometimes has the string "BQL" or a missing value and the BQL in a separate column.
pkdata_string_bql = copy(pkdata)
@rtransform! pkdata_string_bql :CONC = !ismissing(:CONC) && :LLOQ >= :CONC ? "BQL" : :CONC
first(pkdata_string_bql, 20)
20×22 DataFrame
| Row | id | time | CONC | evid | amt | cmt | rate | duration | ss | ii | tad | dosenum | Central | Peripheral | η₁ | η₂ | CL | Vc | Q | Vp | LLOQ | BQL |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| String | Float64 | Any | Int64? | Float64? | Symbol? | Float64? | Float64? | Int8? | Float64? | Float64? | Int64? | Float64? | Float64? | Float64? | Float64? | Float64? | Float64? | Float64? | Float64? | Float64 | Bool? | |
| 1 | 1 | 0.0 | missing | 1 | 200.0 | Central | 0.0 | 0.0 | 0 | 0.0 | 0.0 | 1 | missing | missing | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | missing |
| 2 | 1 | 1.0 | 17.9539 | 0 | missing | missing | missing | missing | missing | missing | 1.0 | 1 | 50.6759 | 57.7767 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 3 | 1 | 3.0 | 3.59012 | 0 | missing | missing | missing | missing | missing | missing | 3.0 | 1 | 10.6936 | 59.8385 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 4 | 1 | 5.0 | 1.89758 | 0 | missing | missing | missing | missing | missing | missing | 5.0 | 1 | 7.24901 | 48.6145 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 5 | 1 | 7.0 | 1.99616 | 0 | missing | missing | missing | missing | missing | missing | 7.0 | 1 | 5.75758 | 39.0359 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 6 | 1 | 9.0 | 1.62626 | 0 | missing | missing | missing | missing | missing | missing | 9.0 | 1 | 4.61737 | 31.3244 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | false |
| 7 | 1 | 11.0 | BQL | 0 | missing | missing | missing | missing | missing | missing | 11.0 | 1 | 3.70496 | 25.1354 | -0.13752 | -0.864106 | 2.5274 | 2.95 | 1.8 | 9.0 | 0.9 | true |
| 8 | 2 | 0.0 | missing | 1 | 200.0 | Central | 0.0 | 0.0 | 0 | 0.0 | 0.0 | 1 | missing | missing | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | missing |
| 9 | 2 | 1.0 | 12.8523 | 0 | missing | missing | missing | missing | missing | missing | 1.0 | 1 | 102.014 | 47.5713 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 10 | 2 | 3.0 | 8.46052 | 0 | missing | missing | missing | missing | missing | missing | 3.0 | 1 | 38.0232 | 68.2487 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 11 | 2 | 5.0 | 4.2123 | 0 | missing | missing | missing | missing | missing | missing | 5.0 | 1 | 23.0299 | 63.0127 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 12 | 2 | 7.0 | 3.32903 | 0 | missing | missing | missing | missing | missing | missing | 7.0 | 1 | 17.7494 | 54.2878 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 13 | 2 | 9.0 | 3.54978 | 0 | missing | missing | missing | missing | missing | missing | 9.0 | 1 | 14.6831 | 46.0971 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 14 | 2 | 11.0 | 2.82836 | 0 | missing | missing | missing | missing | missing | missing | 11.0 | 1 | 12.3548 | 39.0171 | -0.528407 | -0.357039 | 1.70968 | 4.89822 | 1.8 | 9.0 | 0.9 | false |
| 15 | 3 | 0.0 | missing | 1 | 200.0 | Central | 0.0 | 0.0 | 0 | 0.0 | 0.0 | 1 | missing | missing | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | missing |
| 16 | 3 | 1.0 | 21.4362 | 0 | missing | missing | missing | missing | missing | missing | 1.0 | 1 | 81.4514 | 51.2734 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
| 17 | 3 | 3.0 | 6.00094 | 0 | missing | missing | missing | missing | missing | missing | 3.0 | 1 | 23.4483 | 64.5451 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
| 18 | 3 | 5.0 | 3.0174 | 0 | missing | missing | missing | missing | missing | missing | 5.0 | 1 | 14.0357 | 55.8149 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
| 19 | 3 | 7.0 | 2.37679 | 0 | missing | missing | missing | missing | missing | missing | 7.0 | 1 | 10.9155 | 46.2582 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
| 20 | 3 | 9.0 | 2.04447 | 0 | missing | missing | missing | missing | missing | missing | 9.0 | 1 | 8.9062 | 38.1072 | -0.318543 | -0.536189 | 2.1089 | 4.09481 | 1.8 | 9.0 | 0.9 | false |
The string version can be handled with the inverse @rtransform! that changes the "BQL" value to LLOQ. If the dependent variable is missing and a BQL flag is present, something like the following can be used instead.
@rtransform! pkdata_bql_missing :CONC = ismissing(:CONC) && :BQL == true ? LLOQ : :CONCIn any case, it is important to note the format Pumas expects: the dependent variable of a BQL row must be set to the LLOQ itself, as the max(:LLOQ, :CONC) transformation above does. With censored_latent(dist, LLOQ, nothing) or Censored(dist, LLOQ, nothing), a value strictly below the bound has zero probability, so a BQL row set to 0 or to any value below LLOQ (0.9 in this case) makes the log-likelihood -Inf and the fit fails at the first likelihood evaluation.
5 Estimating a model with BQL values
We will now estimate some models:
- Remove the data (M1)
This strategy simply involves removing the data that is censored and fit only the uncensored data.
- Truncated observations (M2)
This strategy is appropriate when we know that data below the Lower Limit Of Quantification (LLOQ) or above the Upper Limit Of Quantification (ULOQ) is discarded and the sampling times are also discarded. If the times were retained in the data we could use M1.
- Censored observations (M3)
If we know the LLOQ or ULOQ and we know the time points of the censored samples we can use this fact in our estimation. The fact that we know observation with made at some time point and it was censored and previously samples values were not does actually inform us about how fast drug is cleared for example for fixed limits.
- Censored and positive (M4)
If we know at what levels observations are censored and we know that samples are positive by definition we can use M3 together with an assumption of a truncated distribution (typically Normal).
5.1 Truncation and Censoring in @derived
Before we move on to the a examples of M1-M4 let us look at the different choices we have available to us in Pumas.
We can censor the outcome variables with either censored_latent(dist, lloq, uloq) or Censored(dist, lloq, uloq). They both modify the loglikelihood the same way as described in the beginning of this document, but they differ in they way simulations are performed and predictions are calculated. censored_latent should be used when we want to estimate under the assumption of censoring but we want to simulate and predict the underlying distribution. Censored on the other hand is to be used when we want to both estimate and simulate under the assumption of censoring.
For truncation, we can use the similarly defined truncated_latent(dist, lloq, uloq) or truncated(dist, lloq, uloq). Again, the _latent indicates that we want to only estimate under the assumption of truncation, but not simulate under the same assumption.
5.2 Remove the data (M1)
Now, we are finally ready to estimate a model based on our censored data. The most simple approach is to simply discard the data. Beal (2001) calls this approach “M1”. To perform such an analysis, we can filter away the BQL values and fit the model using iv2cmt_dgp.
pkdata_m1 = copy(pkdata_censored)
@rtransform! pkdata_m1 :CONC = :evid == 0 && :BQL == 0 ? :CONC : missing
first(pkdata_m1, 20)
We can now fit the model.
pop_m1 = read_pumas(pkdata_m1; observations = [:CONC], covariates = [:LLOQ])
res_m1 = fit(iv2cmt_dgp, pop_m1, param0, LaplaceI(); optim_options = (; show_trace = false))
[ Info: Checking the initial parameter values. [ Info: The initial negative log-likelihood and its gradient are finite. Check passed.
FittedPumasModel

Dynamical system type:                 Closed form

Number of subjects:                             90

Observation records:         Active        Missing
    CONC:                       485             55
    Total:                      485             55

Number of parameters:      Constant      Optimized
                                  0              8

Likelihood approximation:                 LaplaceI
Likelihood optimizer:                         BFGS

Termination Reason:                   GradientNorm
Log-likelihood value:                   -669.29258

-------------------
         Estimate
-------------------
θcl       2.636
θvc       6.7184
θq        1.8271
θvp      10.38
Ω₁,₁      0.077214
Ω₂,₂      0.11287
σ_add     0.079008
σ_prop    0.18028
-------------------
5.3 Truncated observations (M2)
Another method to use is the so-called M2 method. M1 and M2 both discard BQL observations, or alternatively they are the only option because the BQL observations were already dropped from the dataset by someone else! For an application of M2, we approach the data as if we know the LLOQ value, but if any observations was indeed BQL it was dropped from the data. Then, the appropriate distributional assumption on the observed values remaining in the dataset is to use a truncated combined normal if we believe the original data was indeed a combined normal.
iv2cmt_m2 = @model begin
    @param begin
        θcl ∈ RealDomain(lower = 0.1)
        θvc ∈ RealDomain(lower = 1.0)
        θq ∈ RealDomain(lower = 0.1)
        θvp ∈ RealDomain(lower = 1.1)
        Ω ∈ PDiagDomain(2)
        σ_add ∈ RealDomain(lower = 0.0)
        σ_prop ∈ RealDomain(lower = 0.0)
    end

    @covariates LLOQ

    @random begin
        η ~ MvNormal(Ω)
    end

    @pre begin
        CL = θcl * exp(η[1])
        Vc = θvc * exp(η[2])
        Q = θq
        Vp = θvp
    end

    @dynamics Central1Periph1

    @derived begin
        conc_model := @. Central / Vc
        CONC ~ @. truncated_latent(CombinedNormal(conc_model, σ_add, σ_prop), LLOQ, nothing)
    end
end
PumasModel
Parameters: θcl, θvc, θq, θvp, Ω, σ_add, σ_prop
Random effects: η
Covariates: LLOQ
Dynamical system variables: Central, Peripheral
Dynamical system type: Closed form
Derived: CONC
Observed: CONCpop_m2 = read_pumas(pkdata_m1; observations = [:CONC], covariates = [:LLOQ])
res_m2 = fit(iv2cmt_dgp, pop_m2, param0, LaplaceI(); optim_options = (; show_trace = false))[ Info: Checking the initial parameter values. [ Info: The initial negative log-likelihood and its gradient are finite. Check passed.
FittedPumasModel

Dynamical system type:                 Closed form

Number of subjects:                             90

Observation records:         Active        Missing
    CONC:                       485             55
    Total:                      485             55

Number of parameters:      Constant      Optimized
                                  0              8

Likelihood approximation:                 LaplaceI
Likelihood optimizer:                         BFGS

Termination Reason:                   GradientNorm
Log-likelihood value:                   -669.29258

-------------------
         Estimate
-------------------
θcl       2.636
θvc       6.7184
θq        1.8271
θvp      10.38
Ω₁,₁      0.077214
Ω₂,₂      0.11287
σ_add     0.079008
σ_prop    0.18028
-------------------
5.4 Censored observations (M3)
If we do have the observations flagged BQL, but not the actual values, we can also use a censored distribution. That is, we either observe the data directly or we observe that it was at LLOQ or below. This is exactly what a censored distribution allows us to model, because it places all the observations below LLOQ in a point mass at the LLOQ. This is still useful information, and allows us to estimate parameters in the underlying distribution (the latent variable or non-censored distribution) from our assumed data generating process (DGP).
iv2cmt_m3 = @model begin
    @param begin
        θcl ∈ RealDomain(lower = 0.1)
        θvc ∈ RealDomain(lower = 1.0)
        θq ∈ RealDomain(lower = 0.1)
        θvp ∈ RealDomain(lower = 1.1)
        Ω ∈ PDiagDomain(2)
        σ_add ∈ RealDomain(lower = 0.0)
        σ_prop ∈ RealDomain(lower = 0.0)
    end

    @covariates LLOQ

    @random begin
        η ~ MvNormal(Ω)
    end

    @pre begin
        CL = θcl * exp(η[1])
        Vc = θvc * exp(η[2])
        Q = θq
        Vp = θvp
    end

    @dynamics Central1Periph1

    @derived begin
        conc_model := @. Central / Vc
        CONC ~
            @. censored_latent(CombinedNormal(conc_model, σ_add, σ_prop), LLOQ, nothing)
    end
end
PumasModel
Parameters: θcl, θvc, θq, θvp, Ω, σ_add, σ_prop
Random effects: η
Covariates: LLOQ
Dynamical system variables: Central, Peripheral
Dynamical system type: Closed form
Derived: CONC
Observed: CONCpop_m3 = read_pumas(pkdata_censored; observations = [:CONC], covariates = [:LLOQ])
res_m3 = fit(iv2cmt_m3, pop_m3, param0, LaplaceI(); optim_options = (show_trace = false,))[ Info: Checking the initial parameter values. [ Info: The initial negative log-likelihood and its gradient are finite. Check passed.
FittedPumasModel

Dynamical system type:                 Closed form

Number of subjects:                             90

Observation records:         Active        Missing
    CONC:                       540              0
    Total:                      540              0

Number of parameters:      Constant      Optimized
                                  0              8

Likelihood approximation:                 LaplaceI
Likelihood optimizer:                         BFGS

Termination Reason:                   GradientNorm
Log-likelihood value:                   -713.28729

------------------
         Estimate
------------------
θcl      2.8251
θvc      6.8525
θq       1.7065
θvp      8.0187
Ω₁,₁     0.088401
Ω₂,₂     0.12025
σ_add    0.20152
σ_prop   0.1683
------------------
5.5 Censored and positive (M4)
The last possibility we will consider is the M4 method. This method takes the approach that BQL values are represented with the probability of being in the left tail of the combined normal distribution given all parameters, but adds the fact that the observations must have been positive as well for concentration data. In our humble opinion, this approach is slightly strange given the assumed data generating process. Instead, we find it more useful to just think in terms of the DGP + Censoring. Then, M4 is simply M3 with the assumption that the original data was also naturally truncated. In other words, if M3 is “add censoring”, M4 is not really a separate statistical handling of BQL. It is simply a different assumption on the DGP.
iv2cmt_m4 = @model begin
    @param begin
        θcl ∈ RealDomain(lower = 0.1)
        θvc ∈ RealDomain(lower = 1.0)
        θq ∈ RealDomain(lower = 0.1)
        θvp ∈ RealDomain(lower = 1.1)
        Ω ∈ PDiagDomain(2)
        σ_add ∈ RealDomain(lower = 0.0)
        σ_prop ∈ RealDomain(lower = 0.0)
    end

    @covariates LLOQ

    @random begin
        η ~ MvNormal(Ω)
    end

    @pre begin
        CL = θcl * exp(η[1])
        Vc = θvc * exp(η[2])
        Q = θq
        Vp = θvp
    end

    @dynamics Central1Periph1

    @derived begin
        conc_model := @. Central / Vc
        CONC ~ @. censored_latent(
            truncated(CombinedNormal(conc_model, σ_add, σ_prop); lower = 0),
            LLOQ,
            nothing,
        )
    end
end
PumasModel
Parameters: θcl, θvc, θq, θvp, Ω, σ_add, σ_prop
Random effects: η
Covariates: LLOQ
Dynamical system variables: Central, Peripheral
Dynamical system type: Closed form
Derived: CONC
Observed: CONCres_m4 = fit(iv2cmt_m4, pop_m3, param0, LaplaceI(); optim_options = (show_trace = false,))[ Info: Checking the initial parameter values. [ Info: The initial negative log-likelihood and its gradient are finite. Check passed.
FittedPumasModel

Dynamical system type:                 Closed form

Number of subjects:                             90

Observation records:         Active        Missing
    CONC:                       540              0
    Total:                      540              0

Number of parameters:      Constant      Optimized
                                  0              8

Likelihood approximation:                 LaplaceI
Likelihood optimizer:                         BFGS

Termination Reason:                   GradientNorm
Log-likelihood value:                    -713.2916

------------------
         Estimate
------------------
θcl      2.8251
θvc      6.8525
θq       1.7066
θvp      8.019
Ω₁,₁     0.088403
Ω₂,₂     0.12024
σ_add    0.20126
σ_prop   0.16833
------------------
The DGP for such data could have been represented with the following model.
iv2cmt_dgp_trunc = @model begin
    @param begin
        θcl ∈ RealDomain(lower = 0.1)
        θvc ∈ RealDomain(lower = 1.0)
        θq ∈ RealDomain(lower = 0.1)
        θvp ∈ RealDomain(lower = 1.1)
        Ω ∈ PDiagDomain(2)
        σ_add ∈ RealDomain(lower = 0.0)
        σ_prop ∈ RealDomain(lower = 0.0)
    end

    @random begin
        η ~ MvNormal(Ω)
    end

    @pre begin
        CL = θcl * exp(η[1])
        Vc = θvc * exp(η[2])
        Q = θq
        Vp = θvp
    end

    @dynamics Central1Periph1

    @derived begin
        conc_model := @. Central / Vc
        CONC ~ @. truncated(CombinedNormal(conc_model, σ_add, σ_prop); lower = 0)
    end
end
PumasModel
Parameters: θcl, θvc, θq, θvp, Ω, σ_add, σ_prop
Random effects: η
Covariates:
Dynamical system variables: Central, Peripheral
Dynamical system type: Closed form
Derived: CONC
Observed: CONC6 Subject-dependent LLOQ
It is possible that some subjects have different LLOQ values because they come from different studies, and, for example, their plasma samples were sent to different labs. In this case, the LLOQ value should still be set as the value of the CONC at the time of censoring, and the specific censoring can then be retrieved as a covariate. For example, the following population has two different LLOQs depending on the study.
pop1 = [
    Subject(
        id = string(i),
        events = DosageRegimen(200),
        time = [1.0, 3.0, 5.0, 7.0, 9.0, 11.0],
        covariates = (STUDY = 001, LLOQ_cov = 0.9),
    ) for i = 1:90
]
pop2 = [
    Subject(
        id = string(i),
        events = DosageRegimen(200),
        time = [1.0, 3.0, 5.0, 7.0, 9.0, 11.0],
        covariates = (STUDY = 002, LLOQ_cov = 0.09),
    ) for i = 1:10
]
pop = vcat(pop1, pop2)
Population
Subjects: 100
Covariates: STUDY, LLOQ_cov
Observations: iv2cmt_m4 = @model begin
@param begin
θcl ∈ RealDomain(lower = 0.1)
θvc ∈ RealDomain(lower = 1.0)
θq ∈ RealDomain(lower = 0.1)
θvp ∈ RealDomain(lower = 1.1)
Ω ∈ PDiagDomain(2)
σ_add ∈ RealDomain(lower = 0.0)
σ_prop ∈ RealDomain(lower = 0.0)
end
@covariates LLOQ_cov
@random begin
η ~ MvNormal(Ω)
end
@pre begin
CL = θcl * exp(η[1])
Vc = θvc * exp(η[2])
Q = θq
Vp = θvp
end
@dynamics Central1Periph1
@derived begin
conc_model := @. Central / Vc
CONC ~ @. censored_latent(
truncated(CombinedNormal(conc_model, σ_add, σ_prop); lower = 0),
LLOQ_cov,
nothing,
)
end
endPumasModel
Parameters: θcl, θvc, θq, θvp, Ω, σ_add, σ_prop
Random effects: η
Covariates: LLOQ_cov
Dynamical system variables: Central, Peripheral
Dynamical system type: Closed form
Derived: CONC
Observed: CONC7 BQL values recorded as zero (M7)
A seemingly harmless way to deal with BQL values is to record them as zero, which Beal (2001) calls “M7”. Unfortunately, together with a combined error model, M7 can make the likelihood unbounded, so that maximum likelihood estimates do not even exist. We illustrate this with the warfarin dataset (O’Reilly et al. 1963; O’Reilly and Aggeler 1968) from PharmaDatasets, in which four concentrations are recorded as exactly zero.
using PharmaDatasets

warfarin = @chain dataset("pumas/warfarin_pumas") begin
    @rtransform begin
        :FSZV = :wtbl / 70
        :FSZCL = (:wtbl / 70)^0.75
    end
end
@rsubset warfarin !ismissing(:conc) && iszero(:conc)
4×12 DataFrame
| Row | id | time | evid | amt | cmt | conc | pca | wtbl | age | sex | FSZV | FSZCL |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Float64 | Int64 | Float64? | Int64? | Float64? | Float64? | Float64 | Int64 | String1 | Float64 | Float64 | |
| 1 | 1 | 0.5 | 0 | missing | missing | 0.0 | missing | 66.7 | 50 | M | 0.952857 | 0.96443 |
| 2 | 2 | 0.5 | 0 | missing | missing | 0.0 | missing | 66.7 | 31 | M | 0.952857 | 0.96443 |
| 3 | 9 | 0.5 | 0 | missing | missing | 0.0 | missing | 70.0 | 28 | M | 1.0 | 1.0 |
| 4 | 14 | 0.5 | 0 | missing | missing | 0.0 | missing | 50.0 | 36 | F | 0.714286 | 0.77697 |
All four zeros were measured 0.5 hours after the dose, early in the absorption phase. We fit a one-compartment model with first-order absorption, an absorption lag, and a combined error model to the data, keeping the zeros.
warfarin_model = @model begin
    @param begin
        pop_CL ∈ RealDomain(lower = 0.0)
        pop_Vc ∈ RealDomain(lower = 0.0)
        pop_tabs ∈ RealDomain(lower = 0.0)
        pop_lag ∈ RealDomain(lower = 0.0)
        pk_Ω ∈ PDiagDomain(3)
        σ_prop ∈ RealDomain(lower = 0.0)
        σ_add ∈ RealDomain(lower = 0.0)
    end

    @random begin
        pk_η ~ MvNormal(pk_Ω)
    end

    @covariates FSZCL FSZV

    @pre begin
        CL = FSZCL * pop_CL * exp(pk_η[1])
        Vc = FSZV * pop_Vc * exp(pk_η[2])
        tabs = pop_tabs * exp(pk_η[3])
        Ka = log(2) / tabs
    end

    @dosecontrol begin
        lags = (Depot = pop_lag,)
    end

    @vars begin
        cp := Central / Vc
    end

    @dynamics Depots1Central1

    @derived begin
        conc ~ @. CombinedNormal(cp, σ_add, σ_prop)
    end
end

param0_warfarin = (
    pop_CL = 0.134,
    pop_Vc = 8.11,
    pop_tabs = 0.523,
    pop_lag = 0.1,
    pk_Ω = Diagonal([0.01, 0.01, 0.01]),
    σ_prop = 0.09,
    σ_add = 0.26,
)

pop_m7 = read_pumas(warfarin; observations = [:conc], covariates = [:FSZCL, :FSZV])
fit_m7 = fit(
    warfarin_model,
    pop_m7,
    param0_warfarin,
    FOCE();
    optim_options = (; show_trace = false),
)
[ Info: Checking the initial parameter values. [ Info: The initial negative log-likelihood and its gradient are finite. Check passed.
FittedPumasModel

Dynamical system type:                 Closed form

Number of subjects:                             32

Observation records:         Active        Missing
    conc:                       251             47
    Total:                      251             47

Number of parameters:      Constant      Optimized
                                  0              9

Likelihood approximation:                     FOCE
Likelihood optimizer:                         BFGS

Termination Reason:                   GradientNorm
Log-likelihood value:                   -350.49625

--------------------
           Estimate
--------------------
pop_CL     0.13465
pop_Vc     8.0535
pop_tabs   0.55062
pop_lag    0.87158
pk_Ω₁,₁    0.070641
pk_Ω₂,₂    0.018302
pk_Ω₃,₃    0.91327
σ_prop     0.090096
σ_add      0.39115
--------------------
The fit looks unremarkable, but the estimated lag of 0.87 hours means that the model predicts a concentration of exactly zero 0.5 hours after the dose, matching the four zeros perfectly. With a predicted concentration of zero, the variance of the combined error model, \(\sigma_{add}^2 + \sigma_{prop}^2 \mu^2\), reduces to \(\sigma_{add}^2\), and each zero contributes \(-\log(\sigma_{add}) - \log(2\pi)/2\) to the log-likelihood. This term grows without bound as σ_add approaches zero. At the same time, the proportional component keeps the variance of all other observations positive, so their contributions remain bounded and nothing counteracts the growth. With an additive error model alone, the variance of all observations would shrink with σ_add, and the resulting penalty from the non-zero residuals would outweigh the gain from the zeros.
We can see this by evaluating the log-likelihood for decreasing values of σ_add while keeping all other parameters at their estimates.
σ_add_grid = exp10.(range(0, -16; length = 81))
loglikelihood_slice(model, pop, fitted_model, approx) = [
    loglikelihood(model, pop, merge(coef(fitted_model), (; σ_add)), approx) for
    σ_add in σ_add_grid
]
ll_m7 = loglikelihood_slice(warfarin_model, pop_m7, fit_m7, FOCE())
81-element Vector{Float64}:
-394.75169418496307
-361.8104864248774
-350.5114090418814
-359.90448929102195
-385.4109648054838
-401.983719287841
-411.64765278874364
-415.7513040419318
-416.57875188671625
-415.85566166047016
⋮
-300.56449608630163
-298.7224280119064
-296.8803599375112
-295.03829186311594
-293.19622378872066
-291.35415571432543
-289.5120876399302
-287.670019565535
-285.8279514911397Show/Hide Code
draw(
    mapping(σ_add_grid => "σ_add", ll_m7 => "Log-likelihood") *
    visual(AlgebraOfGraphics.Lines) +
    mapping([loglikelihood(fit_m7)]) *
    visual(AlgebraOfGraphics.HLines; linestyle = :dash, color = :gray);
    axis = (; xscale = log10),
)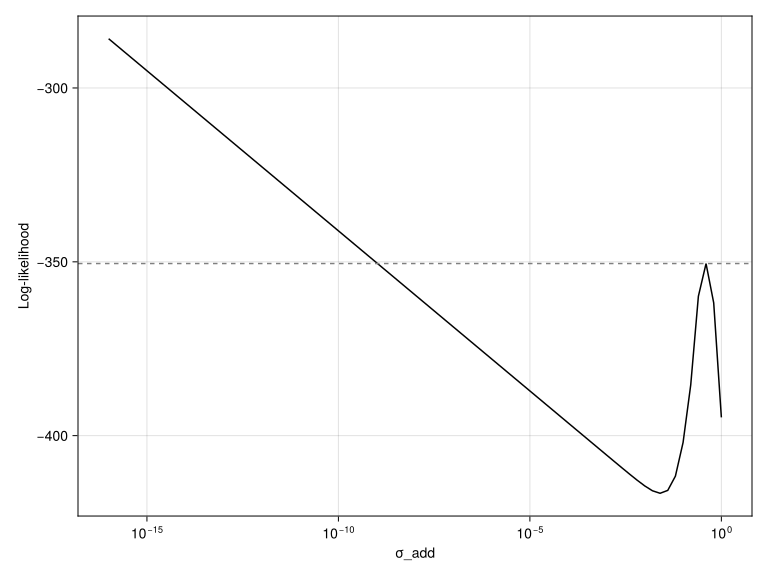
The dashed line marks the log-likelihood at the estimates found by fit, which correspond to a local maximum. Every time σ_add shrinks by a factor of 10, the log-likelihood increases by \(4 \log(10) \approx 9.2\), one \(\log(10)\) for each of the four zeros, until it exceeds the value at the local maximum. The optimizer happens to end up at the local maximum here, but other starting values, resampled data in a bootstrap, or a different estimation method can easily end up in the singularity instead.
The problem is caused by the combination of data and model: observations of exactly zero, a model that predicts a concentration of exactly zero at the same time points, and an error model whose variance then depends on σ_add alone. Before the absorption has started, a true concentration of zero is plausible, so the zeros are not necessarily wrong. However, no assay measures a concentration of exactly zero, and it seems more likely that the zeros indicate that warfarin could not be quantified than that it was measured to be zero with arbitrary precision, as M7 implicitly claims. In that case the zeros are BQL values, and we can use the same methods as for the simulated data above. Only the zeros are affected: the other low concentrations in the dataset were reported as numbers and carry information about the elimination phase.
7.1 Removing the zeros (M1)
The simplest approach is to treat the zeros as missing.
warfarin_m1 = @rtransform warfarin @passmissing :conc = iszero(:conc) ? missing : :conc
pop_m1 = read_pumas(warfarin_m1; observations = [:conc], covariates = [:FSZCL, :FSZV])
fit_m1 = fit(
    warfarin_model,
    pop_m1,
    param0_warfarin,
    FOCE();
    optim_options = (; show_trace = false),
)
[ Info: Checking the initial parameter values. [ Info: The initial negative log-likelihood and its gradient are finite. Check passed.
FittedPumasModel

Dynamical system type:                 Closed form

Number of subjects:                             32

Observation records:         Active        Missing
    conc:                       247             51
    Total:                      247             51

Number of parameters:      Constant      Optimized
                                  0              9

Likelihood approximation:                     FOCE
Likelihood optimizer:                         BFGS

Termination Reason:                   GradientNorm
Log-likelihood value:                   -350.46191

--------------------
           Estimate
--------------------
pop_CL     0.1347
pop_Vc     8.048
pop_tabs   0.54491
pop_lag    0.87702
pk_Ω₁,₁    0.070713
pk_Ω₂,₂    0.018347
pk_Ω₃,₃    0.92436
σ_prop     0.087934
σ_add      0.41375
--------------------
7.2 Censoring the zeros (M3)
Censoring generally performs better than discarding BQL values (Ahn et al. 2008; Bergstrand and Karlsson 2009), but it requires an LLOQ, which the dataset does not state. The smallest positive concentration is 0.6 mg/L, so for this example we assume an LLOQ of 0.5 mg/L. As discussed above, Pumas expects the dependent variable of a BQL row to be set to the LLOQ.
warfarin_m3 = @rtransform warfarin begin
    :LLOQ = 0.5
    @passmissing :conc = iszero(:conc) ? 0.5 : :conc
end

warfarin_model_m3 = @model begin
    @param begin
        pop_CL ∈ RealDomain(lower = 0.0)
        pop_Vc ∈ RealDomain(lower = 0.0)
        pop_tabs ∈ RealDomain(lower = 0.0)
        pop_lag ∈ RealDomain(lower = 0.0)
        pk_Ω ∈ PDiagDomain(3)
        σ_prop ∈ RealDomain(lower = 0.0)
        σ_add ∈ RealDomain(lower = 0.0)
    end

    @random begin
        pk_η ~ MvNormal(pk_Ω)
    end

    @covariates FSZCL FSZV LLOQ

    @pre begin
        CL = FSZCL * pop_CL * exp(pk_η[1])
        Vc = FSZV * pop_Vc * exp(pk_η[2])
        tabs = pop_tabs * exp(pk_η[3])
        Ka = log(2) / tabs
    end

    @dosecontrol begin
        lags = (Depot = pop_lag,)
    end

    @vars begin
        cp := Central / Vc
    end

    @dynamics Depots1Central1

    @derived begin
        conc ~ @. censored_latent(CombinedNormal(cp, σ_add, σ_prop), LLOQ, nothing)
    end
end

pop_m3 =
    read_pumas(warfarin_m3; observations = [:conc], covariates = [:FSZCL, :FSZV, :LLOQ])
fit_m3 = fit(
    warfarin_model_m3,
    pop_m3,
    param0_warfarin,
    LaplaceI();
    optim_options = (; show_trace = false),
)
[ Info: Checking the initial parameter values. [ Info: The initial negative log-likelihood and its gradient are finite. Check passed.
FittedPumasModel

Dynamical system type:                 Closed form

Number of subjects:                             32

Observation records:         Active        Missing
    conc:                       251             47
    Total:                      251             47

Number of parameters:      Constant      Optimized
                                  0              9

Likelihood approximation:                 LaplaceI
Likelihood optimizer:                         BFGS

Termination Reason:                      NoXChange
Log-likelihood value:                   -348.32594

--------------------
           Estimate
--------------------
pop_CL     0.13421
pop_Vc     8.0784
pop_tabs   0.69785
pop_lag    0.86203
pk_Ω₁,₁    0.078359
pk_Ω₂,₂    0.019694
pk_Ω₃,₃    0.79854
σ_prop     0.090769
σ_add      0.39357
--------------------
A censored observation contributes the logarithm of the probability that the concentration is below the LLOQ. This probability is at most one, so the singularity disappears.
7.3 Comparison
The estimates of the three approaches are shown below.
compare_estimates(; M7 = fit_m7, M1 = fit_m1, M3 = fit_m3)9×4 DataFrame
| Row | parameter | M7 | M1 | M3 |
|---|---|---|---|---|
| String | Float64? | Float64? | Float64? | |
| 1 | pop_CL | 0.134653 | 0.134695 | 0.13421 |
| 2 | pop_Vc | 8.05346 | 8.04801 | 8.07836 |
| 3 | pop_tabs | 0.550617 | 0.544909 | 0.697851 |
| 4 | pop_lag | 0.871584 | 0.877021 | 0.862032 |
| 5 | pk_Ω₁,₁ | 0.0706411 | 0.0707126 | 0.0783586 |
| 6 | pk_Ω₂,₂ | 0.018302 | 0.0183468 | 0.019694 |
| 7 | pk_Ω₃,₃ | 0.913273 | 0.924357 | 0.798539 |
| 8 | σ_prop | 0.0900963 | 0.0879338 | 0.0907691 |
| 9 | σ_add | 0.391148 | 0.413747 | 0.393566 |
Apart from the absorption half-life pop_tabs and its variability, the estimates are close to each other. The zeros are the only observations during the early absorption phase, so it matters most for the absorption parameters whether they are removed or censored.
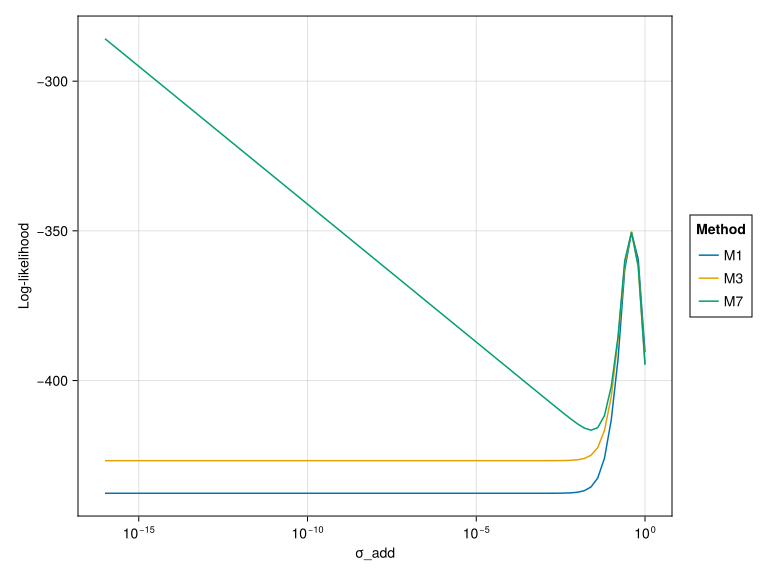
The log-likelihood is bounded for both M1 and M3. Since the three approaches use different data and likelihoods, only the shapes of the curves are comparable, not their levels.
Show/Hide Code
ll_m1 = loglikelihood_slice(warfarin_model, pop_m1, fit_m1, FOCE())
ll_m3 = loglikelihood_slice(warfarin_model_m3, pop_m3, fit_m3, LaplaceI())
slices = (
    σ_add = repeat(σ_add_grid, 3),
    loglikelihood = vcat(ll_m7, ll_m1, ll_m3),
    method = repeat(["M7", "M1", "M3"]; inner = length(σ_add_grid)),
)
draw(
    data(slices) *
    mapping(:σ_add, :loglikelihood => "Log-likelihood", color = :method => "Method") *
    visual(AlgebraOfGraphics.Lines);
    axis = (; xscale = log10),
)
On the model side, the singularity is more difficult to avoid than it might seem. Bounding σ_add away from zero makes the likelihood bounded, but its maximum may then lie at the bound, which is difficult to assess a priori. Replacing the lag with transit compartments (Savic et al. 2007) yields small but positive predicted concentrations immediately after the dose, but if the number of transit compartments is estimated, the model can approach the lag arbitrarily closely and the problem reappears. An additive error model avoids the singularity but changes the assumptions about the residual error of all observations, and a proportional error model is not an option, since its variance is exactly zero whenever the predicted concentration is zero. Moreover, all of these changes still treat the zeros as measured concentrations, which is why we prefer to address the data side with M1 or M3.
8 Conclusion
In this tutorial, we showed how to use filtering, truncation, and censoring to handle missing data problems for models fitted with linearized approximations to the likelihood function of a non-linear mixed effects model. Whether or not to include the BQL data rows in the data set depends on the expectations about any bias that may be introduced from ignoring the missing data problem. If the bias is expected to be significant, this tutorial showed how to write up a model that takes the missing data into consideration and estimate parameters more accurately.
We also showed that BQL values recorded as zero (M7) can make the likelihood of a model with a combined error model unbounded, and that removing (M1) or censoring (M3) such values resolves the problem.
9 References
Ahn, Jae Eun, Mats O Karlsson, Adrian Dunne, and Thomas M Ludden. 2008. “Likelihood Based Approaches to Handling Data Below the Quantification Limit Using NONMEM VI.” Journal of Pharmacokinetics and Pharmacodynamics 35 (4): 401–21. https://doi.org/10.1007/s10928-008-9094-4.
Beal, Stuart L. 2001. “Ways to Fit a PK Model with Some Data Below the Quantification Limit.” Journal of Pharmacokinetics and Pharmacodynamics 28: 481–504.
Bergstrand, Martin, and Mats O Karlsson. 2009. “Handling Data Below the Limit of Quantification in Mixed Effect Models.” The AAPS Journal 11: 371–80.
O’Reilly, Robert A, and Paul M Aggeler. 1968. “Studies on Coumarin Anticoagulant Drugs: Initiation of Warfarin Therapy Without a Loading Dose.” Circulation 38 (1): 169–77. https://doi.org/10.1161/01.cir.38.1.169.
O’Reilly, Robert A, Paul M Aggeler, and Lewis S Leong. 1963. “Studies on the Coumarin Anticoagulant Drugs: The Pharmacodynamics of Warfarin in Man.” The Journal of Clinical Investigation 42 (10): 1542–51. https://doi.org/10.1172/JCI104839.
Savic, Radojka M, Daniël M Jonker, Thomas Kerbusch, and Mats O Karlsson. 2007. “Implementation of a Transit Compartment Model for Describing Drug Absorption in Pharmacokinetic Studies.” Journal of Pharmacokinetics and Pharmacodynamics 34 (5): 711–26. https://doi.org/10.1007/s10928-007-9066-0.