using Pumas
Logistic Regression
Caution
This lesson is really comprehensive and has a wide audience in mind. We recommend the reader to briefly navigate the Table of Contents and choose which topics to dive in. If you are in doubt feel free to read it from top to bottom.
In this lesson we’ll dive into logistic regression. We’ll start by defining what it is and, more importantly, when to use it.
1 What is Logistic Regression?
Logistic regression is the most used generalized linear model (GLM). GLMs uses a linear regression under the hood for inference but combines that with a non-linear transformation of the dependent variable (also called response).
This allows us to extend the interface of linear regression to more use cases that it would not be possible to apply it directly. This happens because of the nature of some dependent variables, being not linear and, subsequently, not continuous. Such instances occur in binary data, discrete data, count data, or ordinal data.
Logistic Regression is a GLM that can handle binary data. That is, when our response variable takes two distinct values only, generally coded as 0 and 1. It handles that by applying a non-linear transformation to the response variable. And guess what? This transformation is called the logistic function! This is why it is called logistic regression.
Tip
The logistic function is also called the sigmoid function because of the sigmoidal shape (S-shaped) of its graph.
This is the logistic function:
\[\mathrm{logistic}(x) = \frac{1}{1 + e^{-x}}\]
Note
Logistic regression can be extended to more discrete outcomes than binary, i.e., it can also handle multiclass problems. If you want to learn more, search for softmax regression or multinomial logistic regression.
Let’s take a look at the graph of our logistic function:
using CairoMakie
using AlgebraOfGraphicslogistic_fun(x) = 1 / (1 + exp(-x));
data((; x = -10:0.1:10, y = logistic_fun.(-10:0.1:10))) *
mapping(:x, :y => "logistic(x)") *
visual(Lines; color = :steelblue, linewidth = 3) |> draw
As you can see the logistic function is a mapping from \((-\infty, +\infty)\) to \([0, 1]\). In other words, it just compresses anything to something between 0 and 1.
1.1 Dependent Variable \(y\)
This makes it the ideal candidate to model things that are defined between 0 and 1, such as probabilities. Thus, with binary data we can focus on the modeling of the probability that our dependent variable will take values 0 or 1. That is, if we say our dependent variable is \(y\) and the probability of it taking value 1 conditioned on covariate \(x\) is \(P(y=1 \mid x)\), then the logistic regression will give us:
\[P(y=1 \mid x) = \mathrm{logistic}(x) = \frac{1}{1 + e^{-x}}\]
Tip
The \(\mid\) in \(P(y \mid x)\) denotes the probability of \(y\) conditioned on \(x\). That is, once we know what value \(x\) takes, what is the probability of \(y\). This is the classical conditional probability notation.
1.2 Covariate \(x\)
Now with the dependent variable explained, let’s focus on covariate(s) \(x\). Let’s begin with the simple case when \(x\) is a scalar (not a vector).
Generally in regression problems, we attribute coefficients to act as weights to our covariate \(x\). These coefficients measure the strength of association between \(x\) and \(y\), where high positive coefficients mean high positive association while high negative coefficients indicate high negative association.
Coefficients are usually denominated as the greek letter \(\beta\). Thus, our logistic regression formula becomes:
\[P(y=1 \mid x, \beta) = \mathrm{logistic}(x, \beta) = \frac{1}{1 + e^{-\left(\beta x\right)}}\]
Tip
Almost everything that we want to infer or guess in statistics has greek letters such as \(\beta\) and \(\alpha\), while what is observed has roman letters such as \(x\) and \(y\).
Since \(y\) and \(x\) are known, all we have to do is find the best value of our coefficient \(\beta\). That process is called model fit and we will deal with it in detail further in this lesson.
1.2.1 How to Interpret Coefficient \(\beta\)?
Now, suppose we have found our ideal value for \(\beta\). How we would interpret our \(\beta\) estimated value?
First, to recap, \(\beta\) measures the strength of association between the covariate \(x\) and dependent variable \(y\). But, \(\beta\) is nested inside a non-linear transformation called logistic function:
\[\mathrm{logistic}(\beta) = \frac{1}{1 + e^{-\beta}}\]
So, our first step is to undo the logistic function. There is a function that is called logit function that is the inverse of the logistic function:
\[\mathrm{logistic}^{-1}(x) = \mathrm{logit}(x) = \ln\left(\frac{x}{1 -x}\right)\]
where \(\ln\) is the natural logarithm function.
If we analyze closely the logit function we can find that inside the \(\ln\) there is a disguised odds in the \(\frac{x}{1 -x}\). Hence, our \(\beta\) can be interpreted as the logarithm of the odds, or in short form: the log-odds.
Tip
Odds provide a measure of the likelihood of a particular outcome. They are calculated as the ratio of the number of events that produce that outcome to the number that do not. To convert probability \(p\) to \(\mathrm{odds}\) you can use the formula:
\[\mathrm{odds}(p) = \frac{p}{1-p}\]
The higher the odds, the higher the probability.
Since odds take values between \((0, \infty)\), and 1 is interpreted as neutral odds (like probability 0.5); the log-odds have a nice intuition that any negative value, that is the \(\ln\) of something between \((0, 1)\), lowers the \(P(y=1)\), while any positive value, that is the \(\ln\) of something between \((1, \infty)\), increases the \(P(y=1)\). Log-odds equal to 0 is exactly \(\ln(1)\), i.e. odds as 1:1; which means neutral effect on \(P(y=1)\).
The log-odds are the key to interpret coefficient \(\beta\). Any positive value of \(\beta\) means that there exists a positive association between \(x\) and \(P(y=1)\), while any negative values indicate a negative association between \(x\) and \(P(y=1)\). Values close to 0 demonstrates the lack of association between \(x\) and \(P(y=1)\).
1.2.2 Covariate \(\mathbf{x}\) as a Vector
Now that we covered the case when \(x\) is a scalar, let’s tackle the case when \(\mathbf{x}\) is a vector.
Tip
Note that bold case letters are restricted to denoting vectors and matrices. So, \(x\) is a scalar and \(\mathbf{x}\) is a vector.
Also, matrices are distinguished from vectors by using uppercase letters. For example, \(\mathbf{A}\) is a matrix while \(\mathbf{a}\) is a vector.
Furthermore, we can denote elements of a vector or matrix by their respective index. If we want the \(i\)th element of a vector \(\mathbf{x}\), we denote the element \(x_i\). Since matrices have two dimensions: rows and columns; we need an extra index. Thus, if we want the element of the \(i\)th row and \(j\)th column of a matrix \(\mathbf{A}\), we denote the element \(A_{ij}\) (also some use the lowercase \(a_{ij}\) notation).
If we replace our covariate scalar for a vector of covariates in the logistic function, we get:
\[\mathrm{logistic}(\mathbf{x}) = \frac{1}{1 + e^{-\mathbf{x}}} = \frac{1}{1 + e^{-\left( x_1 + x_2 + ... + x_k \right)}}\]
where \(k\) is the length of \(\mathbf{x}\), that is the total number of covariates that we have.
The same way covariates can be represented as a vector, the coefficients \(\beta\) can be also represented as a vector \(\boldsymbol{\beta}\). The covariate-coefficient products can be efficiently represented as a matrix-vector product:
\[\beta_1 x_1 + \beta_2 x_2 + ... + \beta_k x_k = \mathbf{X} \cdot \boldsymbol{\beta}\]
here \(\mathbf{X}\) is our data matrix, where each row is an observation and each column a covariate.
To conclude, our logistic function in the case of multiple covariates can be expressed in matrix notation as:
\[\mathrm{logistic}(\mathbf{X}) = \frac{1}{1 + e^{- \left( \mathbf{X} \cdot \boldsymbol{\beta} \right)}}\]
1.3 Intercept \(\alpha\)
Like in any other regression, we also need an intercept to act as our basal rate. That is the expected value of \(y\), in our model, when all covariates are fixed to 0.
In logistic regression the intercept represents the basal probability of our observations taking value \(y=1\), conditioned that all the covariates are zero:
\[P(y=1 \mid \mathbf{x} = \mathbf{0})\]
Traditionally, intercepts are represented as the greek letter \(\alpha\).
This is the final addition that we need to our logistic function. So, our final version of the logistic function in a logistic regression is:
\[\mathrm{logistic}(\mathbf{X}) = \frac{1}{1 + e^{- \left( \alpha + \mathbf{X} \cdot \boldsymbol{\beta} \right)}}\]
where \(\alpha\) is a scalar and \(\alpha + \mathbf{X} \cdot \boldsymbol{\beta}\) boils down to a scalar-vector addition:
\[\mathbf{\hat{y}} = \alpha + \mathbf{X} \cdot \mathbf{\beta} = \alpha + \mathbf{\hat{X}}\]
where \(\mathbf{\hat{y}}\) and \(\mathbf{\hat{X}}\) are the predicted vector of dependent variables and covariate matrix, respectively.
Tip
One more mathematical notation tip. Almost everything that has a “hat” on, like \(\hat{x}\), is an addition used to flag that it is the “predicted” or “estimated” version of the symbol. Thus \(\hat{x}\) could be either predicted or estimated \(x\). In other words, we do not observe \(\hat{x}\) but we recover it from a model based on model assumptions and conditional on data (though in simulations the data conditioning does not hold).
1.4 Likelihoods
We have almost everything we need for our logistic regression. We are only missing a final touch. Currently, our logistic function outputs a probability, i.e. a number between 0 and 1. That is not what we need in a binary data context.
Hence, we need to convert the probability to a discrete binary outcome. That is the role of the likelihood functions. More generally, likelihood functions convert the result of the non-linear mapping into the nature of our dependent variable. And, since we are in a discrete binary outcome (logistic regression, with a binary dependent variable), we need a likelihood function that outputs a discrete binary outcome. This could be anything like yes or no, 0 or 1, cat or dog, sad or happy, rain or shine. Actually, the label of the discrete outcome does not matter, so let’s use a fail/success discrete outcome for now on.
In logistic regression, we can use primarily two likelihood functions to model binary discrete outcomes:
- Bernoulli distribution
- Binomial distribution
Tip
To be precise, likelihood functions are not the same as probability functions, since they do not sum up to integrate to 1. They can be seen as an unnormalized probability function.
The Bernoulli distribution has two equivalent parameterizations, and Pumas provides both: Bernoulli(p) in terms of the probability of success \(p\), and BernoulliLogit(ζ) in terms of the log-odds \(\zeta = \mathrm{logit}(p)\). We cover both below.
1.4.1 Bernoulli Likelihood
Tip
The Bernoulli distribution is named after mathematician Jacob Bernoulli, who is considered one of the fathers of statistical inference (alongside Laplace, Bayes, Quetelet and others), and also the first to discover the Law of the Large Numbers.
The Bernoulli distribution is used to model an independent single trial that has a binary fail/success outcome. It accepts only a single parameter named \(p\) which represents the probability of trial success.
Tip
Distributional parameters are values that control how a distribution behaves. They can be integers or reals, take restrained or unrestrained values and be either scalars, vectors or matrices. In a typical statistical inference setting, distributions are used to model data and the parameters are unknown. Thus, parameter inference plays a main role in statistical inference.
In most logistic regression applications, it is used the 0.5 threshold to denote the outcome of a Bernoulli likelihood. So, anything that has \(p < 0.5\) has outcome as fail or 0. And anything that has \(p \geq 0.5\) has outcome as success or 1.
Note
Some fields and applications tend to fine tune the threshold of the logistic regression’s Bernoulli likelihood. Notoriously, the field of machine learning is one of such cases since the focus is on prediction accuracy rather than parameter inference.
If your data is composed of observations that have a dependent variable that only takes binary discrete outcomes, you’ll probably use the Bernoulli likelihood inside the logistic regression model.
Take a look at some Bernoulli distribution plots for different \(p\):
using Pumas

x = [0, 1]
probs = [0.5, 0.25, 0.75]
dists = [Bernoulli(p) for p in probs]
pdfs = mapreduce(d -> pdf.(d, x), vcat, dists)
plt =
    data((; probs = repeat(probs; inner = 2), x = repeat(x; outer = 3), pdfs)) *
    mapping(
        :x => "outcome",
        :pdfs => "PMF";
        color = :probs => nonnumeric => "parameter p",
        col = :probs => nonnumeric,
    ) *
    visual(BarPlot)
draw(plt; axis = (; xticks = [0, 1]))
1.4.2 BernoulliLogit Likelihood
Pumas also provides BernoulliLogit, the same distribution parameterized by the log-odds rather than the probability: BernoulliLogit(ζ) is Bernoulli(logistic(ζ)).
This is the natural parameterization for a logistic regression, which assembles \(\alpha + \mathbf{X} \cdot \boldsymbol{\beta}\) on the log-odds scale already. Being the same distribution, it assigns the same probabilities:
zetas = logit.(probs)
pdfs_logit = vec(stack(ζ -> pdf.(BernoulliLogit(ζ), x), zetas))
pdfs_logit ≈ pdfs
true
Note
The log-odds scale is also the numerically better behaved one. Bernoulli(logistic(ζ)) forms the probability explicitly, and once logistic(ζ) rounds to exactly 0 or 1 the log-likelihood becomes -Inf, leaving the optimizer nothing to follow. In double precision that already happens at a log-odds of 40:
logistic(40.0), logpdf(Bernoulli(logistic(40.0)), 0), logpdf(BernoulliLogit(40.0), 0)(1.0, -Inf, -40.0)BernoulliLogit never forms the probability, so its log-likelihood stays finite. Both parameterizations describe the same model and give the same estimates up to round-off.
Tip
FO() does not support BernoulliLogit, just as it does not support Bernoulli. With random effects, use FOCE() or LaplaceI() instead.
1.4.3 Binomial Likelihood
The binomial distribution is used to model discrete successes out of a number of independent trials, each asking having a success/fail outcome. It has two parameters: \(n\) the number of trials; and \(p\) the probability of trial success.
Tip
The Bernoulli distribution is a special case of the binomial distribution where \(n\) is fixed to 1, i.e. a single independent trial.
If your data is composed of columns that can be represented as attempts and successes, and you want to use successes as a dependent variable; then binomial likelihood is a great candidate for the likelihood function inside the logistic regression model.
Note
Sometimes grouping your data from the trial observation level, i.e. every row is a single trial, to a success observation level, i.e. every row is a number of attempts and successes, can make your model much more efficient and faster to run.
For example, if you have data as:
| ID | result |
|---|---|
| a | 1 |
| b | 0 |
| a | 0 |
| a | 1 |
| b | 1 |
And all trials (rows) are independent (this is important), you can convert it to the following:
| ID | attempts | successes |
|---|---|---|
| a | 3 | 2 |
| b | 2 | 1 |
Then, you can model the same data using a binomial likelihood instead of a Bernoulli likelihood. This will be more efficient because we are grouping rows and, thus, our inference algorithm has less data to process during model fitting.
Here are some plots of Binomial distributions for different \(n\) and \(p\):
x = 0:20
probs = [0.5, 0.25, 0.75]
ns = [5, 10, 20]
dists = [Binomial(n, p) for p in probs for n in ns]
pdfs = mapreduce(d -> pdf.(d, x), vcat, dists)
data((;
    probs = repeat([p for p in probs for n in ns]; inner = 21),
    ns = repeat([n for p in probs for n in ns]; inner = 21),
    x = repeat(x, 9),
    pdfs,
)) *
mapping(
    :x => "outcome",
    :pdfs => "PMF";
    color = :probs => nonnumeric => "parameter p",
    row = :probs => nonnumeric,
    col = :ns => nonnumeric,
) *
visual(BarPlot) |> draw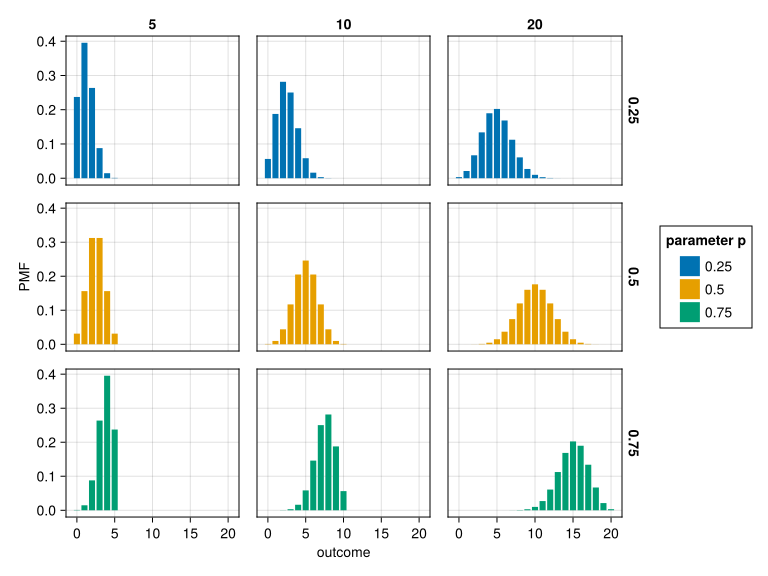
2 When to use Logistic Regression?
Now that we know what logistic regression is, let’s cover when to use it. The simple answer is whenever your dependent variable is dichotomous, i.e. is a discrete binary outcome, that is takes only two discrete values. Then you can use a Bernoulli likelihood inside your logistic regression, preferably the BernoulliLogit parameterization, which takes the log-odds that your linear predictor already produces.
But if your observations (rows) are independent, you can group them into attempts and successes. and use a binomial likelihood.
Tip
Independence in this context means that knowing information about one observation does not give us any information about the other observations and vice versa. This is a classical assumption in statistical models. The independence assumption generally holds, but if you have time-dependent measurements, then your data probably violates this assumption.
Let’s see some examples that are often modeled as logistic regression:
- Clinical Trial where the outcome is binary, such as the absence or presence of a certain symptom.
- Observation study where the outcome is binary, such as cardiovascular disease.
- Survival analysis that tracks a binary outcome, such as cancer survival studies.
- Patient adherence to a certain treatment.
3 nausea Dataset
Let’s use the nausea dataset from PharmaDatasets.jl to run our logistic regression example in this lesson:
using PharmaDatasets
using DataFrames
using DataFramesMeta
using SummaryTables
nausea = dataset("nausea")
first(nausea, 5)5×9 DataFrame
| Row | ID | Group | AUC | isF | SEX | WT | RACE | TRT | NAUSEA |
|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Int64 | Int64 | String7 | Int64 | String15 | String7 | Int64 | |
| 1 | 1 | 1 | 0 | 1 | Female | 74 | Caucasian | Placebo | 0 |
| 2 | 2 | 1 | 0 | 0 | Male | 62 | Asian | Placebo | 0 |
| 3 | 3 | 1 | 0 | 1 | Female | 72 | Caucasian | Placebo | 0 |
| 4 | 4 | 1 | 0 | 0 | Male | 77 | Asian | Placebo | 0 |
| 5 | 5 | 1 | 0 | 0 | Male | 44 | Caucasian | Placebo | 0 |
We can see that we have 200 observations and also some key variables:
:NAUSEA(dependent variable): which has a binary outcome – 0, 1.:SEX: discrete binary – Female, Male.:WT: weight in kg.:RACE: discrete/categorical with 5 levels – Caucasian, Asian, Other, Hispanic, Black.:TRT: treatment variable with 4 levels – Placebo, Dose20, Dose40, Dose80.:Group: the same as:TRTbut with integers – 1, 2, 3, 4.:AUC: Area Under the Curve.
3.1 Exploratory Data Analysis
Let’s see some summary statistics with describe():
describe(nausea)9×7 DataFrame
| Row | variable | mean | min | median | max | nmissing | eltype |
|---|---|---|---|---|---|---|---|
| Symbol | Union… | Any | Union… | Any | Int64 | DataType | |
| 1 | ID | 100.5 | 1 | 100.5 | 200 | 0 | Int64 |
| 2 | Group | 2.5 | 1 | 2.5 | 4 | 0 | Int64 |
| 3 | AUC | 561.85 | 0 | 190.5 | 4016 | 0 | Int64 |
| 4 | isF | 0.475 | 0 | 0.0 | 1 | 0 | Int64 |
| 5 | SEX | Female | Male | 0 | String7 | ||
| 6 | WT | 72.135 | 33 | 72.0 | 120 | 0 | Int64 |
| 7 | RACE | Asian | Other | 0 | String15 | ||
| 8 | TRT | Dose20 | Placebo | 0 | String7 | ||
| 9 | NAUSEA | 0.335 | 0 | 0.0 | 1 | 0 | Int64 |
As we can see :AUC has mean 561.85 and median 190.5 which tells us is a long-tail distribution (or asymmetric shifted to the right).
Also, our :WT variable has a mean and median not so different which signals a bell-shaped (normally-distributed) distribution. We have weight values ranging from 33 kg and 120 kg.
To conclude our summary statistics, :NAUSEA, our dependent variable, has mean 0.335, which means that around 33.5% of our patients have the positive outcome for nausea symptoms.
It is also important to check the categorical columns to see what are the number of unique values (:nunique) along with the first and last values:
describe(nausea, :first, :last, :nunique; cols = Not([:NAUSEA, :AUC, :WT]))6×4 DataFrame
| Row | variable | first | last | nunique |
|---|---|---|---|---|
| Symbol | Any | Any | Union… | |
| 1 | ID | 1 | 200 | |
| 2 | Group | 1 | 4 | |
| 3 | isF | 1 | 0 | |
| 4 | SEX | Female | Male | 2 |
| 5 | RACE | Caucasian | Caucasian | 5 |
| 6 | TRT | Placebo | Dose80 | 4 |
Ok, no surprises in our categorical covariates.
@by nausea [:TRT, :SEX, :NAUSEA] :count = length(:SEX)15×4 DataFrame
| Row | TRT | SEX | NAUSEA | count |
|---|---|---|---|---|
| String7 | String7 | Int64 | Int64 | |
| 1 | Placebo | Female | 0 | 19 |
| 2 | Placebo | Female | 1 | 9 |
| 3 | Placebo | Male | 0 | 22 |
| 4 | Dose20 | Female | 0 | 12 |
| 5 | Dose20 | Female | 1 | 6 |
| 6 | Dose20 | Male | 0 | 30 |
| 7 | Dose20 | Male | 1 | 2 |
| 8 | Dose40 | Female | 0 | 14 |
| 9 | Dose40 | Female | 1 | 14 |
| 10 | Dose40 | Male | 0 | 21 |
| 11 | Dose40 | Male | 1 | 1 |
| 12 | Dose80 | Female | 0 | 3 |
| 13 | Dose80 | Female | 1 | 18 |
| 14 | Dose80 | Male | 0 | 12 |
| 15 | Dose80 | Male | 1 | 17 |
3.2 Visualizations
Now we turn to some visualizations to see what is going on beyond the summary statistics in our nausea dataset.
First, we’ll explore our dependent variable: :NAUSEA.
data(nausea) *
mapping(:RACE, :NAUSEA; color = :SEX, dodge = :SEX) *
AlgebraOfGraphics.expectation() |> draw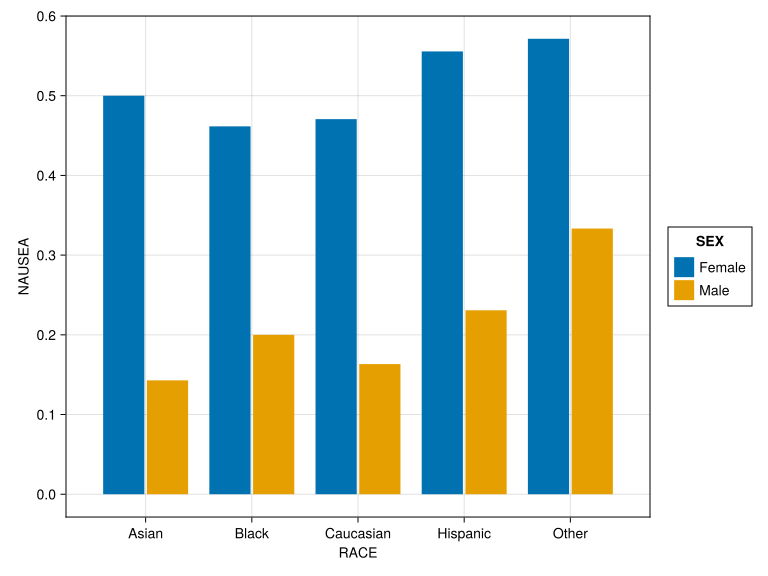
Female patients have more nausea than male patients. Let’s see if this holds for different treatment arms in our nausea data:
plt =
    data(nausea) *
    mapping(
        :RACE,
        :NAUSEA;
        color = :SEX,
        dodge = :SEX,
        layout = :TRT => sorter(["Placebo", "Dose20", "Dose40", "Dose80"]),
    ) *
    AlgebraOfGraphics.expectation()
draw(plt; axis = (; xticklabelrotation = π / 6))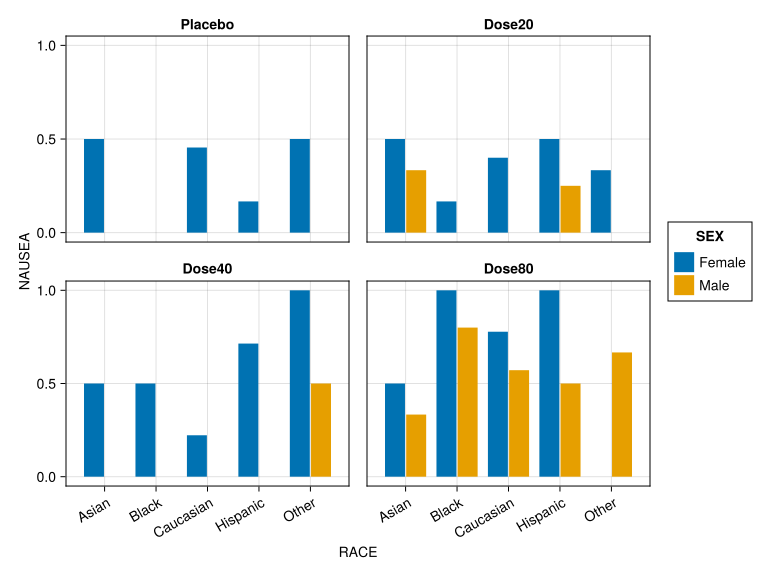
Definitely male patients experience less nausea symptoms than female patients in all dosages. There were no male patients experiencing nausea symptoms in the placebo arm.
Now let’s turn our attention to our covariates :WT and :AUC. First, we will remove the placebo observations as their AUC will always be zero:
nausea_no_plb = @rsubset nausea :TRT != "Placebo";Also, we would like to analyze the dose-normalized AUC, so we will compute this value:
@rtransform! nausea_no_plb @astable begin
    dose_str = chop(:TRT, head = 4, tail = 0)
    :DOSE = parse(Int, dose_str)
    :AUC_norm = :AUC / :DOSE
end;
Tip
We used the chop function to extract dose information from the :TRT column. Make sure to check our Strings tutorial to learn more about Julia’s numerous facilities for working with Strings
We can see clearly a negative relationship between :WT and :AUC:
data(nausea_no_plb) *
mapping(:WT, :AUC_norm => "Dose-normalized AUC") *
(visual(Scatter; alpha = 0.5) + AlgebraOfGraphics.linear()) |> draw
Also, this negative relationship has a positive interaction effect with dosage. Specifically, the higher the dosage the higher the negative relationship between :WT and :AUC. In other words, dosage enhances the relationship between :WT and :AUC, which is an inverse relationship.
dose_renamer = renamer(map(i -> i => "$i mg", unique(nausea_no_plb.DOSE)));plt =
data(nausea_no_plb) *
mapping(:WT, :AUC; color = :DOSE => dose_renamer => "Dose") *
(visual(Scatter; alpha = 0.5) + AlgebraOfGraphics.linear())
draw(plt)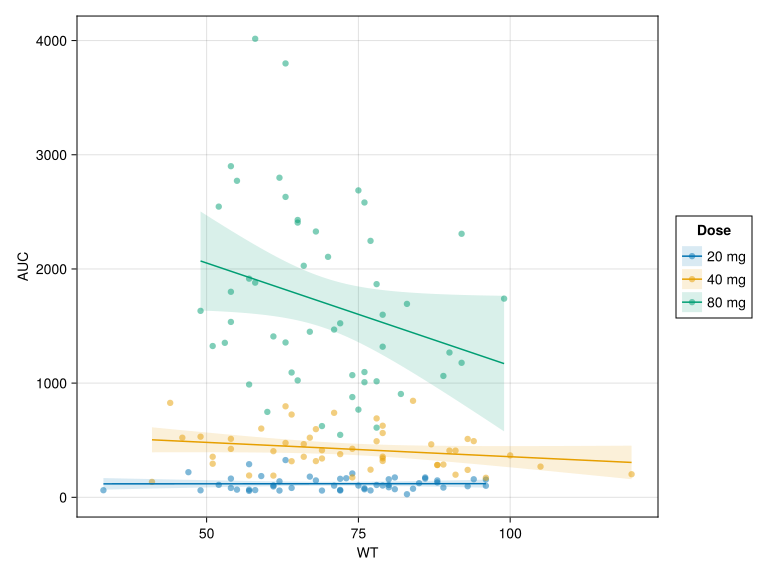
By plotting the relationship between :AUC and dosage while also considering nausea symptoms (our dependent variable :NAUSEA), we see that nausea events are tied to higher :AUC values:
plt =
    data(nausea) *
    mapping(:Group => "Dose (mg)", :AUC; color = :NAUSEA => nonnumeric) *
    (visual(Scatter; alpha = 0.5) + smooth())
draw(plt; axis = (; xticks = (1:4, ["Placebo", "20", "40", "80"])))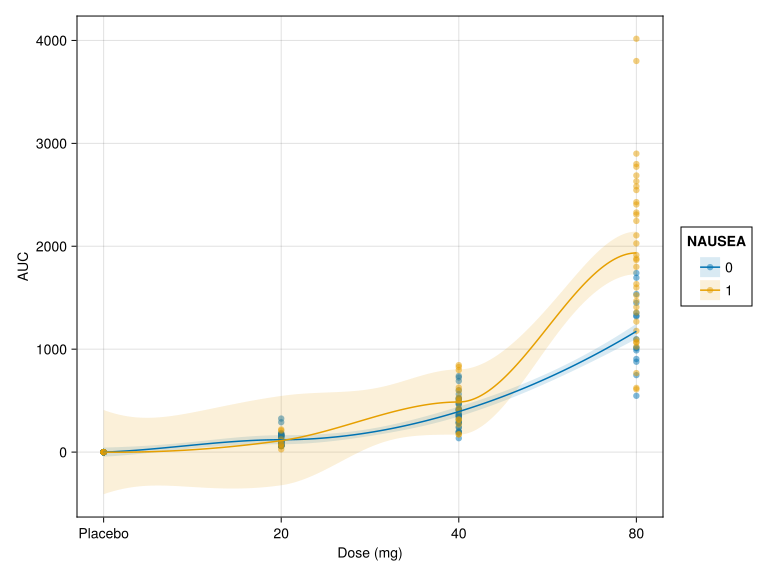
4 Pumas modeling
Finally, we’ll create a Pumas model for logistic regression.
4.1 Pumas’ Workflow
Pumas’ workflow
- Define a model. It can be a
PumasModelor aPumasEMModel. - Define a
SubjectandPopulation. - Fit your model.
- Perform inference on the model’s population-level parameters (also known as fixed effects).
- Predict from a fitted model using the empirical Bayes estimate or Simulate random observations from a fitted model using the sampling distribution (also known as likelihood).
- Model diagnostics and visual predictive checks.
Note
Pumas modeling is a highly iterative process. Eventually, you’ll probably go back and forth in the stages of the workflow. This is natural and expected in Pumas’ modeling. Just remember to have good code organization and version control for all of the workflow iterations.
Before we define the model, we need to convert the :RACE column to dummy variables. Currently :RACE is a string:
unique(nausea.RACE)5-element Vector{InlineStrings.String15}:
"Caucasian"
"Asian"
"Other"
"Hispanic"
"Black"@rtransform! nausea begin
:RACE_Caucasian = ifelse(:RACE == "Caucasian", 1, 0)
:RACE_Asian = ifelse(:RACE == "Asian", 1, 0)
:RACE_Other = ifelse(:RACE == "Other", 1, 0)
:RACE_Hispanic = ifelse(:RACE == "Hispanic", 1, 0)
:RACE_Black = ifelse(:RACE == "Black", 1, 0)
end4.1.1 Defining a model in Pumas
To define a model in Pumas, you can use either the macros or the function interfaces. We will cover the macros interface in this lesson.
To define a model using the macro interface, you start with a begin .. end block of code with @model:
my_model = @model begin endThis creates an empty model. Now we need to populate it with model components. These are additional macros that we can include inside the @model definition. We won’t be covering all the possible macros that we can use in this lesson, but here is the full list:
@param, fixed effects specifications.@random, random effects specifications.@covariates, covariate names.@pre, pre-processing variables for the dynamic system and statistical specification.@dosecontrol, specification of any dose control parameters present in the model.@vars, shorthand notation.@init, initial conditions for the dynamic system.@dynamics, dynamics of the model.@derived, statistical modeling of dependent variables.@observed, model information to be stored in the model solution.
4.1.1.1 Model parameter with @param
Ok, let’s start with our logistic_model using the macro @model interface.
First, we’ll define our parameters with the @parameters macro:
@param begin
    ParameterName ∈ Domain(...)
    ...
end
Tip
To use the “in” (∈) operator in Julia, you can either replace ∈ for in or type \in <TAB> for the Unicode character.
By using the begin ... end block we can specify one parameter per line. We will just name the parameters the same name as their respective covariate, while also adding the β prefix to make clear that this is a coefficient.
Regarding the Domain(...), Pumas has several types of domains for you to specify in your @param block. Here is a list:
RealDomainfor scalar parametersVectorDomainfor vectorsPDiagDomainfor positive definite matrices with diagonal structurePSDDomainfor general positive semi-definite matrices
We will only use scalar parameters in our logistic regression model, so we just need the RealDomain.
Tip
If you don’t specify any arguments inside the domain constructor it will either error (for some domains that have required arguments) or will use the defaults. In the case of the RealDomain() without arguments it just uses the following arguments:
RealDomain(; lower = -∞, upper = ∞, init = 0)@param begin
α ∈ RealDomain()
βAUC ∈ RealDomain()
βisF ∈ RealDomain()
βRACE_Caucasian ∈ RealDomain()
end4.1.1.2 Model covariates with @covariates
We also have to specify our model covariates using the macro @covariates. This can be done using a one-liner syntax, without begin ... end block:
@covariates Group AUC isF WT... # and so onOr using the begin ... end block and specifying one covariate per line. This is what we will do since our model has several covariates, which makes it easy to visualize them and also to comment out a covariate to perform iterative model exploration:
@covariates begin
AUC
isF
RACE_Caucasian
end4.1.1.3 Pre-processing variables with @pre
We can specify all the necessary variables and statistical pre-processing with the @pre macro.
Note
The @pre block is traditionally used to specify the inputs of the Ordinary D ifferential Equations (ODE) system used for non-linear mixed-effects PK/PD models (NLME).
But we will use @pre to specify our variable transformations instead.
Here, we are defining all the coefficients-covariates multiplication operation here. Note that we are adding the prefix _ to the resulting operation. Finally, we are also defining the linear_pred and linear_pred_race as the linear predictors that should be added to the intercept to form the log-odds:
@pre begin
_AUC = AUC * βAUC
_isF = isF * βisF
_RACE_Caucasian = RACE_Caucasian * βRACE_Caucasian
linear_pred = _Group + _AUC + _isF + _Race_Caucasian
end4.1.1.4 Statistical modeling of dependent variables with @derived
Our final block, @derived, is used to specify all the assumed distributions of observed variables that are derived from the blocks above. This is where we include our dependent variable: NAUSEA.
Note that NAUSEA is being declared as following a BernoulliLogit distribution. This is why we use the tilde notation ~. It means (much like the mathematical model notation) that NAUSEA follows a BernoulliLogit distribution. Since NAUSEA is a vector of values, we need to broadcast, i.e. vectorize, the operation with the dot . operator:
NAUSEA ~ BernoulliLogit.(ζ)where ζ is the single log-odds parameter that parametrizes the BernoulliLogit distribution. In some cases, we would need to do a lot of broadcasting on the righthand side of the ~. For example, since the log-odds of NAUSEA is the intercept plus all the linear predictors, i.e. α + linear_pred + linear_pred_race, we would need to vectorize every operation:
NAUSEA ~ BernoulliLogit.(α .+ linear_pred .+ linear_pred_race)This is cumbersome, so we can use the @. macro which tells Julia to apply the . in every operator and function call after it:
NAUSEA ~ @. BernoulliLogit(α + linear_pred + linear_pred_race)Much better!
Note
We are using the @. macro which tells Julia to vectorize (add the “dot syntax”) to all operations and function calls to the right of it.
Tip
In this block we can use all variables defined in the previous blocks, in our example the @param, @covariates and @pre blocks.
We could equally write the same model on the probability scale with Bernoulli, applying the logistic function ourselves:
NAUSEA ~ @. Bernoulli(logistic(α + linear_pred + linear_pred_race))Then we need our logistic function. It could be tricky to use our logistic_fun from the beginning of the tutorial. This is because it is not numerical stable. For this, we can use the logistic function from Pumas.
Tip
To use the logistic function Pumas, you just need to:
using Pumas
# now we should have logistic available
logistic(x)This is our @derived block:
@derived begin
NAUSEA ~ @. BernoulliLogit(α + linear_pred + linear_pred_race)
endHere is our full model, once we combined all the macro blocks we just covered:
logistic_model = @model begin
@param begin
    α ∈ RealDomain()
    βAUC ∈ RealDomain()
    βisF ∈ RealDomain()
    βRACE_Caucasian ∈ RealDomain()
end
@covariates begin
    AUC
    isF
    RACE_Caucasian
end
@pre begin
_AUC = AUC * βAUC
_isF = isF * βisF
_RACE_Caucasian = RACE_Caucasian * βRACE_Caucasian
linear_pred = _AUC + _isF + _RACE_Caucasian
end
@derived begin
NAUSEA ~ @. BernoulliLogit(α + linear_pred)
end
endPumasModel
Parameters: α, βAUC, βisF, βRACE_Caucasian
Random effects:
Covariates: AUC, isF, RACE_Caucasian
Dynamical system variables:
Dynamical system type: No dynamical model
Derived: NAUSEA
Observed: NAUSEA4.1.2 Define a Subject and Population
Once we have our model defined we have to specify a Subject and a Population.
In Pumas, subjects (i.e. observations) are represented by the Subject type and collections of subjects are represented as vectors of Subjects are defined as Population.
Subjects can be constructed with the Subject() constructor, for example:
Subject()Subject
ID: 1We just constructed a Subject that has ID equal to 1 and no extra information. In order to provide extra information, you would need to pass keyword arguments to the Subject() constructor.
You can use the following keyword arguments inside Subject():
id: identifier.observations: a named tuple of the dependent variables.covariates: a named tuple containing the covariates, ornothing.events: aDosageRegimenof dose records, ornothing.time: a vector of time stamps for the observations.
For this lesson, we will just use the covariates keyword argument.
This is an example of a Subject with ID equal to 42 and with some covariates specified as a named tuple:
Subject(id = 42, covariates = (; AUC = 100.0, isF = 1, RACE_Caucasian = 1))Subject
ID: 42
Covariates: AUC, isF, RACE_CaucasianSince a Population is just a vector of Subjects, we can use a simple map() function over the IDs present in our nausea dataset:
pop = map(
    i -> Subject(
        id = i,
        covariates = (;
            AUC = nausea.AUC,
            isF = nausea.isF,
            RACE_Caucasian = nausea.RACE_Caucasian,
        ),
    ),
    1:maximum(nausea.ID),
)
Population
Subjects: 200
Covariates: AUC, isF, RACE_Caucasian
Observations: 4.1.2.1 Reading Subjects directly from a DataFrame
Another option is to use the read_pumas() function to read Subjects (and Population) directly from a DataFrame. This is more convenient than the map() with the Subject() constructor inside.
The read_pumas() function accepts as the first argument a DataFrame followed by the following keyword options (which are very similar to the Subject() constructor):
observations: dependent variables specified by a vector of column names, i.e.[:NAUSEA].covariates: covariates specified by a vector of column names, i.e.[:Group, :AUC, :isF, ...].id: specifies theIDcolumn of theDataFrame.time: specifies thetimecolumn of theDataFrame.event_data: toggles assertions applicable to event data, eithertrueor `false.
Our nausea dataset do not have any event data, so we should set event_data=false. Also, we don’t have a :time column, but Pumas needs us to specify a column for this keyword argument. So let’s create a dummy column :time where all values are 0.0:
@rtransform! nausea :time = 0.0;Now, we can create our population with read_pumas():
nausea_pop = read_pumas(
    nausea;
    observations = [:NAUSEA],
    covariates = [:AUC, :isF, :RACE_Caucasian],
    id = :ID,
    time = :time,
    event_data = false,
)
Population
Subjects: 200
Covariates: AUC, isF, RACE_Caucasian
Observations: NAUSEA4.1.3 Fit your model
Now we are ready to fit our model! We already have a model specified, logistic_model, along with a Population: nausea_pop. We can proceed with model fitting.
Model fitting in Pumas has the purpose of estimate parameters and is done by calling the fit() function with the following positional arguments:
- Pumas model.
- A
Population. - A named tuple of the initial parameter’s values.
- An inference algorithm.
4.1.3.1 Initial Parameter’s Values
We already covered the model and Population, now let’s talk about initial parameter’s values. It is the 3rd positional argument inside fit().
You can specify your initial parameters as a named tuple. For instance, if you want to have a certain parameter, β1, as having an initial value as 3.14, you can do so by passing it inside a named tuple in the 3rd positional argument of fit():
fit(model, population, (; β1 = 3.14))You can also use the helper function init_params() which will recover all the initial parameters we specified inside the model’s @param block.
Tip
Since we used the RealDomain() defaults, all of our example’s initial parameters are set to 0.0.
4.1.3.2 Inference Algorithms
Finally, our last (4th) positional argument is the choice of inference algorithm.
Pumas has the following available inference algorithms:
Marginal Likelihood Estimation:
NaivePooled(): first order approximation without random-effects.FO(): first-order approximation.FOCE(): first-order conditional estimation with automatic interaction detection.LaplaceI(): second-order Laplace approximation.
Bayesian with Markov Chain Monte Carlo (MCMC):
BayesMCMC(): MCMC using No-U-Turn Sampler (NUTS).
Note
We can also use a Maximum A Posteriori (MAP) estimation procedure for any marginal likelihood estimation algorithm. You just need to call the MAP() constructor with the desired marginal likelihood algorithm inside, for instance:
fit(model, population, init_params(model), MAP(FOCE()))Ok, we are ready to fit our model. Let’s use the NaivePooled() since we are not using random-effects in this lesson:
nausea_fit =
    fit(logistic_model, nausea_pop, init_params(logistic_model), Pumas.NaivePooled())
[ Info: Checking the initial parameter values. [ Info: The initial negative log-likelihood and its gradient are finite. Check passed. Iter Function value Gradient norm 0 1.386294e+02 1.974700e+04 * time: 0.04329109191894531 1 1.372336e+02 1.219050e+04 * time: 1.9053690433502197 2 1.343034e+02 3.281601e+03 * time: 1.9058279991149902 3 1.339848e+02 1.584152e+03 * time: 1.9061400890350342 4 1.326986e+02 6.259142e+02 * time: 1.9068729877471924 5 1.189983e+02 9.179957e+03 * time: 1.9071831703186035 6 1.073286e+02 9.953809e+03 * time: 1.9074959754943848 7 1.033436e+02 7.628041e+03 * time: 1.907804012298584 8 1.019525e+02 4.551559e+03 * time: 1.9081001281738281 9 1.014122e+02 1.247847e+03 * time: 1.9083900451660156 10 1.013039e+02 1.248475e+02 * time: 1.9087071418762207 11 1.012701e+02 3.535443e+02 * time: 1.9090070724487305 12 1.012436e+02 3.155452e+02 * time: 1.909301996231079 13 1.011717e+02 2.095362e+02 * time: 1.9096040725708008 14 1.009880e+02 3.297785e+01 * time: 2.1691009998321533 15 1.005095e+02 2.584298e+02 * time: 2.170056104660034 16 9.932576e+01 7.052731e+02 * time: 2.1704039573669434 17 9.669083e+01 1.252074e+03 * time: 2.1707639694213867 18 9.214747e+01 1.497206e+03 * time: 2.1710939407348633 19 8.708724e+01 1.130910e+03 * time: 2.1713991165161133 20 8.415234e+01 5.622900e+02 * time: 2.1717050075531006 21 8.351870e+01 1.277260e+02 * time: 2.1720261573791504 22 8.347707e+01 4.347460e+00 * time: 2.1723251342773438 23 8.347505e+01 1.005005e+01 * time: 2.172633171081543 24 8.347206e+01 1.109664e+01 * time: 2.1729400157928467 25 8.346393e+01 4.520539e+00 * time: 2.173251152038574 26 8.344431e+01 1.644764e+01 * time: 2.1735610961914062 27 8.339392e+01 5.632854e+01 * time: 2.173861026763916 28 8.327073e+01 1.227005e+02 * time: 2.174168109893799 29 8.298813e+01 2.178064e+02 * time: 2.1744699478149414 30 8.244384e+01 3.160806e+02 * time: 2.174777030944824 31 8.171980e+01 3.309252e+02 * time: 2.175079107284546 32 8.119665e+01 1.886602e+02 * time: 2.1753859519958496 33 8.099196e+01 2.736771e+01 * time: 2.1756880283355713 34 8.095571e+01 9.213949e+00 * time: 2.1759979724884033 35 8.095404e+01 1.393843e+00 * time: 2.176285982131958 36 8.095402e+01 9.198021e-01 * time: 2.176574945449829 37 8.095402e+01 4.588621e-01 * time: 2.176867961883545 38 8.095402e+01 1.114793e-01 * time: 2.177157163619995 39 8.095402e+01 2.074038e-02 * time: 2.1774511337280273 40 8.095402e+01 1.176492e-03 * time: 2.177741050720215 41 8.095402e+01 1.016735e-05 * time: 2.1780240535736084
FittedPumasModel

Dynamical system type:          No dynamical model

Number of subjects:                            200

Observation records:         Active        Missing
    NAUSEA:                     200              0
    Total:                      200              0

Number of parameters:      Constant      Optimized
                                  0              4

Likelihood approximation:              NaivePooled
Likelihood optimizer:                         BFGS

Termination Reason:                   GradientNorm
Log-likelihood value:                    -80.95402

-----------------------------
                  Estimate
-----------------------------
α                 -3.3495
βAUC               0.0023738
βisF               2.4945
βRACE_Caucasian   -0.30689
-----------------------------
4.1.4 Perform inference on the model’s population-level parameters
Once the model is fitted, we can analyze our inference and estimates. But first, let’s discuss what the is the meaning of the estimated coefficients in a logistic regression model.
4.1.4.1 Interpreting the Coefficients
We can see that after the model is fitted, it prints a result with a summary and a table of the parameter estimates.
We can also recover the estimates as a named tuple with coef():
coef(nausea_fit)(α = -3.349480673124123, βAUC = 0.002373839339476439, βisF = 2.4945226273225263, βRACE_Caucasian = -0.3068885108866115)Or as a DataFrame with coeftable():
coeftable(nausea_fit)4×4 DataFrame
| Row | parameter | description | constant | estimate |
|---|---|---|---|---|
| String | String | Bool | Float64 | |
| 1 | α | α | false | -3.34948 |
| 2 | βAUC | βAUC | false | 0.00237384 |
| 3 | βisF | βisF | false | 2.49452 |
| 4 | βRACE_Caucasian | βRACE_Caucasian | false | -0.306889 |
Remember that the logistic regression’s coefficients are the log-odds, i.e. the natural logarithm of the odds of \(y\) taking value 1. With BernoulliLogit that is literally what the model computes: α + linear_pred is the log-odds of nausea, with no transformation in between.
Log-odds provide the facility that anything that is negative pulls down the odds (and, consequently, the probability) of \(y\) taking value 1. Anything positive pulls it up; and zero is a neutral effect. But since it is in a log-scale it is not easily interpretable. This is why, in order to interpret it, we often undo the log transformation by exponentiating the log-odds, i.e. exponentiating the coefficients.
We can do that easily with the DataFrame returned by coeftable():
@rtransform coeftable(nausea_fit) :estimate_exp = exp(:estimate)4×5 DataFrame
| Row | parameter | description | constant | estimate | estimate_exp |
|---|---|---|---|---|---|
| String | String | Bool | Float64 | Float64 | |
| 1 | α | α | false | -3.34948 | 0.0351026 |
| 2 | βAUC | βAUC | false | 0.00237384 | 1.00238 |
| 3 | βisF | βisF | false | 2.49452 | 12.1159 |
| 4 | βRACE_Caucasian | βRACE_Caucasian | false | -0.306889 | 0.735733 |
Now let us interpret the :estimate_exp column.
Our basal rate α is the odds of \(y\) taking value 1, i.e. an observation having nausea symptoms, when all the other covariates are zero.
Note
Logistic regression, like linear regression, has the assumption that the effects are a linear combination. That means that a prediction can be made by having the basal rate α and keep adding covariates values multiplied by their β coefficients. This assumption also holds for parameter/model inference. Hence, all of our coefficients represent compounding effects into our dependent variable \(y\).
Let us now interpret the βAUC, the covariate AUC’s coefficient. Its value is approximately 1.0024, which means that for every increase in a single unit of AUC we can expect an increase of 0.24% in the odds of having nausea symptoms. For instance, a 200 increase in AUC would produce a 4.8% increase in the odds of having nausea symptoms.
The βisF, represents the effect of the dummy variable isF. The odds value is over 12, which means that for every unit of increase in the covariate isF we can expect on average an increase of 1,200% in the odds of having nausea symptoms. Since isF is a dummy variable taking either 0 or 1 as values, this means that female observations have 1,200% more risk of having nausea symptoms than male observations.
Tip
If you ever heard of odds ratio or relative risk, this is exactly what we are measuring here with our exponentiated log-odds. It measures the odds ratio between having a dependent variable value of 1 over having a value of 0.
We can also inspect our estimated coefficients’ standard errors (SE) along with the 95% confidence intervals with the infer() function:
infer(nausea_fit)[ Info: Calculating: variance-covariance matrix. [ Info: Done.
Asymptotic inference results using sandwich estimator

Dynamical system type:          No dynamical model

Number of subjects:                            200

Observation records:         Active        Missing
    NAUSEA:                     200              0
    Total:                      200              0

Number of parameters:      Constant      Optimized
                                  0              4

Likelihood approximation:              NaivePooled
Likelihood optimizer:                         BFGS

Termination Reason:                   GradientNorm
Log-likelihood value:                    -80.95402

----------------------------------------------------------------------
                  Estimate     SE           95.0% C.I.
----------------------------------------------------------------------
α                 -3.3495      0.59431      [ -4.5143   ; -2.1846   ]
βAUC               0.0023738   0.00035443   [  0.0016792;  0.0030685]
βisF               2.4945      0.52323      [  1.469    ;  3.52     ]
βRACE_Caucasian   -0.30689     0.41582      [ -1.1219   ;  0.50811  ]
----------------------------------------------------------------------
Also if you prefer another confidence interval band, you can choose with the keyword argument level inside infer().
For instance, one common band for the confidence intervals is 89%:
infer(nausea_fit; level = 0.89)[ Info: Calculating: variance-covariance matrix. [ Info: Done.
Asymptotic inference results using sandwich estimator

Dynamical system type:          No dynamical model

Number of subjects:                            200

Observation records:         Active        Missing
    NAUSEA:                     200              0
    Total:                      200              0

Number of parameters:      Constant      Optimized
                                  0              4

Likelihood approximation:              NaivePooled
Likelihood optimizer:                         BFGS

Termination Reason:                   GradientNorm
Log-likelihood value:                    -80.95402

----------------------------------------------------------------------
                  Estimate     SE           89.0% C.I.
----------------------------------------------------------------------
α                 -3.3495      0.59431      [ -4.2993   ; -2.3997   ]
βAUC               0.0023738   0.00035443   [  0.0018074;  0.0029403]
βisF               2.4945      0.52323      [  1.6583   ;  3.3307   ]
βRACE_Caucasian   -0.30689     0.41582      [ -0.97145  ;  0.35768  ]
----------------------------------------------------------------------
4.1.5 Predict from a fitted model or Simulate random observations from a fitted model
Now that we understand our model estimates, we can use them to make predictions or simulate random observations.
4.1.5.1 Predictions with predict()
In order to calculate prediction from a fitted model, we need to use the predict() function and pass two positional arguments:
- A fitted Pumas model.
- Either a single
Subjector a collection of them with aPopulation.
For example, to make predictions for a single Subject, we can:
my_subject = Subject(id = 42, covariates = (; AUC = 100.0, isF = 1, RACE_Caucasian = 1))Subject
ID: 42
Covariates: AUC, isF, RACE_Caucasian
Caution
predict() also needs a keyword argument obstimes which represents the observation times that we want to predict the dependent variable. The value must be a vector. Since we used a dummy 0.0 value as :time variable in our read_pumas function, we can pass the same 0.0 but as a vector to the predict() function.
predict(nausea_fit, my_subject; obstimes = [0.0])SubjectPrediction
ID: 42
Predictions: NAUSEA: (n=1)
Covariates: AUC, isF, RACE_Caucasian
Time: [0.0]We can also generate prediction for a Population:
nausea_preds = predict(nausea_fit, nausea_pop; obstimes = [0.0])Prediction
Subjects: 200
Predictions: NAUSEA
Covariates: AUC, isF, RACE_CaucasianConverting the predictions to a DataFrame gives us the outcome probabilities in a handy tabular format. The include_covariates keyword argument lets us drop the covariate columns that are of no interest here:
nausea_pred_df = DataFrame(nausea_preds; include_covariates = false)
simple_table(first(nausea_pred_df, 5), [:id, :NAUSEA, :NAUSEA_pred, :NAUSEA_ipred])| id | NAUSEA | NAUSEA_pred | NAUSEA_ipred |
| 1 | 0 | 0.238 | 0.238 |
| 2 | 0 | 0.0339 | 0.0339 |
| 3 | 0 | 0.238 | 0.238 |
| 4 | 0 | 0.0339 | 0.0339 |
| 5 | 0 | 0.0252 | 0.0252 |
Tip
For a binary dependent variable the prediction is the probability. The mean of Bernoulli(p) is p, so :NAUSEA_pred and :NAUSEA_ipred above already give \(P(\text{NAUSEA} = 1)\), and one minus those gives \(P(\text{NAUSEA} = 0)\). For dependent variables with more than two categories, predict() additionally returns one probability column per category. See the ordinal regression tutorial for an example.
4.1.5.2 Simulations with simobs()
We can generate random observations from our fitted Pumas model with the simobs() function. You need to supply at least three positional arguments:
- A non-fitted Pumas model, in our case
logistic_model. - Either a single
Subjector a collection of them with aPopulation. - A named tuple of parameter values.
The 1st and 2nd positional arguments we already covered in our previous examples. Let’s focus on the 3rd positional argument: param. It can be a named tuple with the parameter values. For instance, we can use our estimated parameters from the fitted model with coef(nausea_fit):
coef(nausea_fit)(α = -3.349480673124123, βAUC = 0.002373839339476439, βisF = 2.4945226273225263, βRACE_Caucasian = -0.3068885108866115)simobs(logistic_model, nausea_pop, coef(nausea_fit));4.1.6 Model diagnostics
Finally, our last step is to assess model diagnostics.
4.1.6.1 Assessing model diagnostics
To assess model diagnostics we can use the inspect() function in our fitted Pumas model:
inspect(nausea_fit)[ Info: Calculating predictions. [ Info: Calculating empirical bayes. [ Info: Evaluating dose control parameters. [ Info: Evaluating individual parameters. [ Info: Done.
FittedPumasModelInspection4.1.6.1.1 AIC
We can also check the Akaike Information Criterion (AIC):
aic(nausea_fit)169.908039848844684.1.6.1.2 BIC
Besides AIC, there is also the Bayesian Information Criterion (BIC):
bic(nausea_fit)183.101309315036814.1.6.2 Visual predictive checks
To conclude, we can inspect visual predictive checks with the vpc_plot() function. But first, we need to generate a VPC object with the vpc() function.
By default, vpc will use :time as the independent variable for VPC. We need to change that, because or :time variable is just a vector of 0s in the logistic regression. Let’s use :AUC:
vpc_nausea = vpc(nausea_fit, covariates = [:AUC]);Now, we need to use the vpc_plot function with our newly created VPC object. For this, we need to import the package PumasUtilities:
using PumasUtilitiesvpc_plot(vpc_nausea)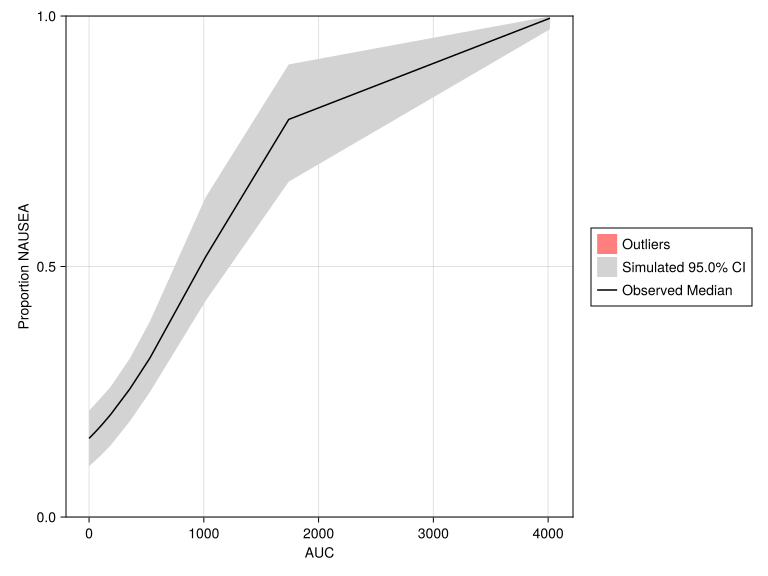
5 Conclusion
I hope you enjoyed this tutorial on logistic regression. Logistic regression is one of the bread and butter of model techniques and is the go-to technique for discrete binary data. Always have it close by in your arsenal of statistical modeling techniques. When you write the likelihood in Pumas, prefer BernoulliLogit: it is parameterized in terms of the log-odds that your linear predictor already produces.