using DataFramesMeta
using PharmaDatasets
using NCA
using Unitful
using Random

Random.seed!(123)
Introduction to NCA
Load the necessary libraries
1 Introduction
This tutorial will introduce the workflow of performing Non-Compartmental Analysis (NCA) in a command-line based workflow. A graphical user interface for NCA is also available for a more interactive experience. Please contact sales@pumas.ai for more information.
For the purpose of this tutorial, we will be using the following dataset:
Blood samples for pharmacokinetics were collected in 107 subjects who received 50 mg of DrugX q24 hours for 5 days, on Day 1 (first dose) and Day 5 (last dose at steady-state). We will analyze the profile of the first dose and the profile of the last dose, which was given at steady state.
In the given dataset
- Time = hrs
- Conc = mg/L
- Amt = mg
1.0.1 Load Data
Load the tutorial dataset using the dataset function from PharmaDatasets.
data = dataset(joinpath("nca", "NCA_tutorial"))
first(data, 5)
5×6 DataFrame
| Row | ID | TIME | CONC | AMT | ROUTE | II |
|---|---|---|---|---|---|---|
| Int64 | Float64 | Float64 | Int64 | String3 | Int64 | |
| 1 | 2 | 0.0 | 0.0 | 50 | ev | 0 |
| 2 | 2 | 0.25 | 0.35 | 0 | ev | 0 |
| 3 | 2 | 0.5 | 0.33 | 0 | ev | 0 |
| 4 | 2 | 0.75 | 0.36 | 0 | ev | 0 |
| 5 | 2 | 1.0 | 0.37 | 0 | ev | 0 |
The dose amount and the dosing interval are given on the dosing row of each profile and are 0 on the observation rows. The reader expects missing on rows without a dose, so we convert the zeros first.
zero_to_missing(x) = x == 0 ? missing : x
data = @rtransform data :AMT = zero_to_missing(:AMT) :II = zero_to_missing(:II)
1.0.2 The first-dose profile
Samples on Day 1 belong to the first dose, so we filter data for time <= 24 hrs
single_dose_data = @rsubset data :TIME <= 24We will specify the units of time, concentration and amount which will be used in the analysis.
timeu = u"hr"
concu = u"mg/L"
amtu = u"mg"
Next, we map the columns in the dataset to the required arguments of the reading function. Our dataset has one dose row per profile and missing in the dose columns on all other rows, which is the layout that read_nca_pumas expects. Data in which every row of a profile repeats the same dose is read with read_nca instead.
- id
- concentration
- time
- tau - if the profile was measured at steady state
- dose
- route - Infusion “ivinfusion”, IV “ivbolus”, Oral “ev”
- duration - only for Infusion
- group - any other grouping variables that you require in the output
Note
If your dataset has a specific style of header for a column then you will not need to map that column separately. Otherwise, columns are automatically determined by Pumas. eg: id, time, concentration, dose, route, duration(if needed), group(if needed).
Do not specify the dosing interval for these profiles, they were not measured at steady state.
pop = read_nca_pumas(
    single_dose_data;
    id = :ID,
    time = :TIME,
    concentration = :CONC,
    dose = :AMT,
    route = :ROUTE,
    time_unit = timeu,
    concentration_unit = concu,
    dose_unit = amtu,
)
1712×12 DataFrame
1687 rows omitted
| Row | id | profile | time | nominal_time | dose_time | nominal_dose_time | concentration | dose | route | duration | exclusion | exclusion_mask |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | String | Missing | Missing | Bool | |
| 1 | 2 | 1 | 0.0 hr | 0.0 hr | 0.0 hr | 0.0 hr | 0.0 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 2 | 2 | 1 | 0.25 hr | 0.25 hr | 0.0 hr | 0.0 hr | 0.35 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 3 | 2 | 1 | 0.5 hr | 0.5 hr | 0.0 hr | 0.0 hr | 0.33 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 4 | 2 | 1 | 0.75 hr | 0.75 hr | 0.0 hr | 0.0 hr | 0.36 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 5 | 2 | 1 | 1.0 hr | 1.0 hr | 0.0 hr | 0.0 hr | 0.37 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 6 | 2 | 1 | 1.5 hr | 1.5 hr | 0.0 hr | 0.0 hr | 0.33 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 7 | 2 | 1 | 2.0 hr | 2.0 hr | 0.0 hr | 0.0 hr | 0.31 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 8 | 2 | 1 | 2.5 hr | 2.5 hr | 0.0 hr | 0.0 hr | 0.3 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 9 | 2 | 1 | 3.0 hr | 3.0 hr | 0.0 hr | 0.0 hr | 0.29 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 10 | 2 | 1 | 4.0 hr | 4.0 hr | 0.0 hr | 0.0 hr | 0.24 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 11 | 2 | 1 | 6.0 hr | 6.0 hr | 0.0 hr | 0.0 hr | 0.18 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 12 | 2 | 1 | 8.0 hr | 8.0 hr | 0.0 hr | 0.0 hr | 0.12 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 13 | 2 | 1 | 12.0 hr | 12.0 hr | 0.0 hr | 0.0 hr | 0.06 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ |
| 1701 | 200 | 107 | 1.0 hr | 1.0 hr | 0.0 hr | 0.0 hr | 0.36 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1702 | 200 | 107 | 1.5 hr | 1.5 hr | 0.0 hr | 0.0 hr | 0.3 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1703 | 200 | 107 | 2.0 hr | 2.0 hr | 0.0 hr | 0.0 hr | 0.31 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1704 | 200 | 107 | 2.5 hr | 2.5 hr | 0.0 hr | 0.0 hr | 0.29 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1705 | 200 | 107 | 3.0 hr | 3.0 hr | 0.0 hr | 0.0 hr | 0.27 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1706 | 200 | 107 | 4.0 hr | 4.0 hr | 0.0 hr | 0.0 hr | 0.23 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1707 | 200 | 107 | 6.0 hr | 6.0 hr | 0.0 hr | 0.0 hr | 0.16 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1708 | 200 | 107 | 8.0 hr | 8.0 hr | 0.0 hr | 0.0 hr | 0.08 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1709 | 200 | 107 | 12.0 hr | 12.0 hr | 0.0 hr | 0.0 hr | 0.04 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1710 | 200 | 107 | 16.0 hr | 16.0 hr | 0.0 hr | 0.0 hr | 0.02 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1711 | 200 | 107 | 20.0 hr | 20.0 hr | 0.0 hr | 0.0 hr | 0.01 mg L^-1 | 50.0 mg | ev | missing | missing | false |
| 1712 | 200 | 107 | 24.0 hr | 24.0 hr | 0.0 hr | 0.0 hr | 0.0 mg L^-1 | 50.0 mg | ev | missing | missing | false |
Observations below the limit of quantification are handled after reading, with transform_nca:
pop = transform_nca(
    pop;
    llq = 0.001concu,
    blq_rules = Dict(:first => :keep, :middle => :drop, :last => :keep),
)
1712×14 DataFrame
1687 rows omitted
| Row | id | profile | time | nominal_time | dose_time | nominal_dose_time | concentration_before_blq | concentration | dose | route | duration | exclusion | exclusion_mask | blq |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | String | Missing | Missing | Bool | Bool | |
| 1 | 2 | 1 | 0.0 hr | 0.0 hr | 0.0 hr | 0.0 hr | 0.0 mg L^-1 | 0.0 mg L^-1 | 50.0 mg | ev | missing | missing | false | true |
| 2 | 2 | 1 | 0.25 hr | 0.25 hr | 0.0 hr | 0.0 hr | 0.35 mg L^-1 | 0.35 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 3 | 2 | 1 | 0.5 hr | 0.5 hr | 0.0 hr | 0.0 hr | 0.33 mg L^-1 | 0.33 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 4 | 2 | 1 | 0.75 hr | 0.75 hr | 0.0 hr | 0.0 hr | 0.36 mg L^-1 | 0.36 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 5 | 2 | 1 | 1.0 hr | 1.0 hr | 0.0 hr | 0.0 hr | 0.37 mg L^-1 | 0.37 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 6 | 2 | 1 | 1.5 hr | 1.5 hr | 0.0 hr | 0.0 hr | 0.33 mg L^-1 | 0.33 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 7 | 2 | 1 | 2.0 hr | 2.0 hr | 0.0 hr | 0.0 hr | 0.31 mg L^-1 | 0.31 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 8 | 2 | 1 | 2.5 hr | 2.5 hr | 0.0 hr | 0.0 hr | 0.3 mg L^-1 | 0.3 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 9 | 2 | 1 | 3.0 hr | 3.0 hr | 0.0 hr | 0.0 hr | 0.29 mg L^-1 | 0.29 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 10 | 2 | 1 | 4.0 hr | 4.0 hr | 0.0 hr | 0.0 hr | 0.24 mg L^-1 | 0.24 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 11 | 2 | 1 | 6.0 hr | 6.0 hr | 0.0 hr | 0.0 hr | 0.18 mg L^-1 | 0.18 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 12 | 2 | 1 | 8.0 hr | 8.0 hr | 0.0 hr | 0.0 hr | 0.12 mg L^-1 | 0.12 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 13 | 2 | 1 | 12.0 hr | 12.0 hr | 0.0 hr | 0.0 hr | 0.06 mg L^-1 | 0.06 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ |
| 1701 | 200 | 107 | 1.0 hr | 1.0 hr | 0.0 hr | 0.0 hr | 0.36 mg L^-1 | 0.36 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1702 | 200 | 107 | 1.5 hr | 1.5 hr | 0.0 hr | 0.0 hr | 0.3 mg L^-1 | 0.3 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1703 | 200 | 107 | 2.0 hr | 2.0 hr | 0.0 hr | 0.0 hr | 0.31 mg L^-1 | 0.31 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1704 | 200 | 107 | 2.5 hr | 2.5 hr | 0.0 hr | 0.0 hr | 0.29 mg L^-1 | 0.29 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1705 | 200 | 107 | 3.0 hr | 3.0 hr | 0.0 hr | 0.0 hr | 0.27 mg L^-1 | 0.27 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1706 | 200 | 107 | 4.0 hr | 4.0 hr | 0.0 hr | 0.0 hr | 0.23 mg L^-1 | 0.23 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1707 | 200 | 107 | 6.0 hr | 6.0 hr | 0.0 hr | 0.0 hr | 0.16 mg L^-1 | 0.16 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1708 | 200 | 107 | 8.0 hr | 8.0 hr | 0.0 hr | 0.0 hr | 0.08 mg L^-1 | 0.08 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1709 | 200 | 107 | 12.0 hr | 12.0 hr | 0.0 hr | 0.0 hr | 0.04 mg L^-1 | 0.04 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1710 | 200 | 107 | 16.0 hr | 16.0 hr | 0.0 hr | 0.0 hr | 0.02 mg L^-1 | 0.02 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1711 | 200 | 107 | 20.0 hr | 20.0 hr | 0.0 hr | 0.0 hr | 0.01 mg L^-1 | 0.01 mg L^-1 | 50.0 mg | ev | missing | missing | false | false |
| 1712 | 200 | 107 | 24.0 hr | 24.0 hr | 0.0 hr | 0.0 hr | 0.0 mg L^-1 | 0.0 mg L^-1 | 50.0 mg | ev | missing | missing | false | true |
1.0.3 Exploratory Analysis
We start by different ways of visualizing the concentration time profiles. Depending on how you are performing your analysis, plots can be either interactive or static. A detailed documentation on NCA related plotting is available here. There are two main plots that can be used:
observations_vs_timesummary_observations_vs_time
If you are working in VSCode, you could enjoy the interactive experience by calling interactive. Let’s look at the observations vs time plots for one subject, which is selected with the ids keyword argument.
ids = unique(pop.id)
observations_vs_time(pop; ids = [ids[1]])
you can switch the axis to log scale by passing axis = (; yscale = log10) as a keyword argument (or use log instead of log10 for natural log). The pre-dose sample of this study was reported as a concentration of zero, which a logarithmic axis cannot show, and a single such value drops the whole profile from the plot. We therefore replace the zeros with missing, which leaves a gap in the curve instead of joining the samples on either side of it.
observations_vs_time(
    @rtransform(pop, :concentration = iszero(:concentration) ? missing : :concentration);
    ids = [ids[1]],
    axis = (; yscale = log10),
)
However, that can become cumbersome for many subjects. Here we show how to view many subjects at once in the non-interactive mode. Let’s plot the concentration vs time for a few subject picked randomly.
rand_subjs = rand(ids, 9)
ctplots = observations_vs_time(
    pop;
    ids = rand_subjs,
    axis = (; xlabel = "Time hr", ylabel = "DrugX Concentration mg/L"),
    paginate = true,
)
ctplots[1]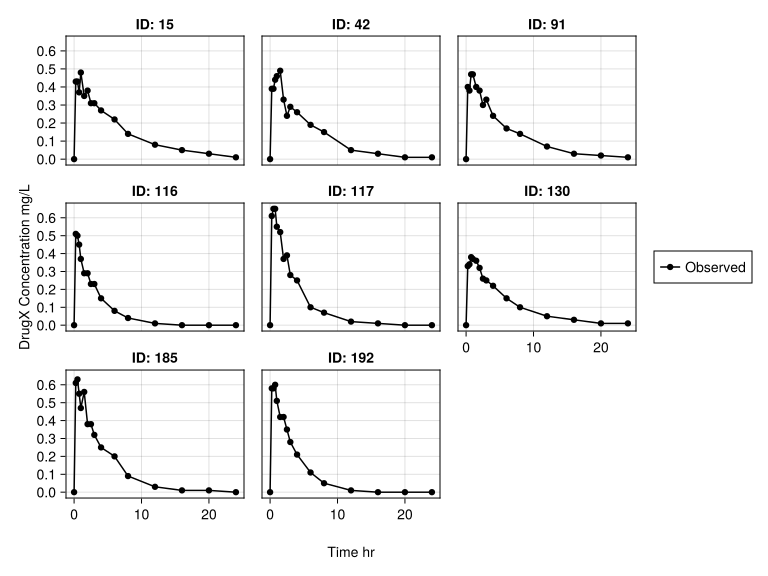
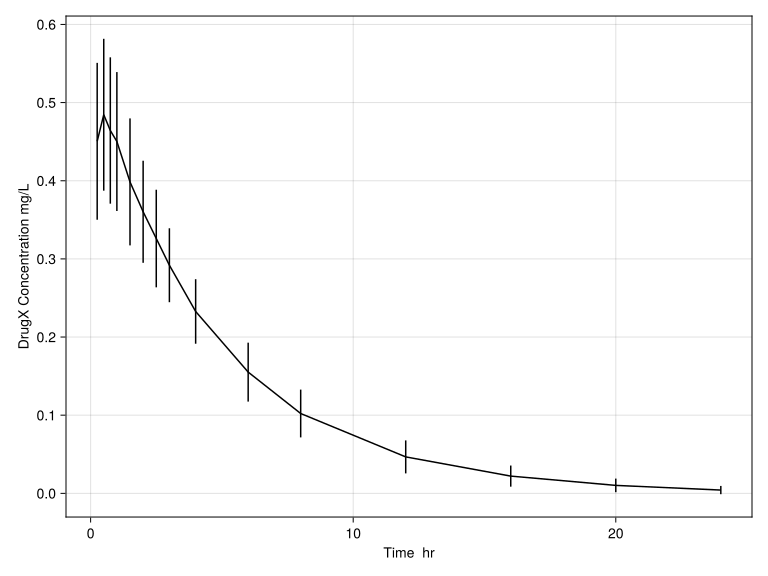
You can also visualize the mean concentration vs time plot by using
summary_observations_vs_time(
    pop;
    axis = (; xlabel = "Time  hr", ylabel = "DrugX Concentration mg/L"),
)
1.0.4 NCA analysis
The workhorse function that performs the analysis is run_nca. It takes the data returned by the reader and gives back a DataFrame with one row per profile. Without a list of endpoints, all endpoints that apply to the data are computed; pass a vector of endpoint names as the second argument to restrict the output.
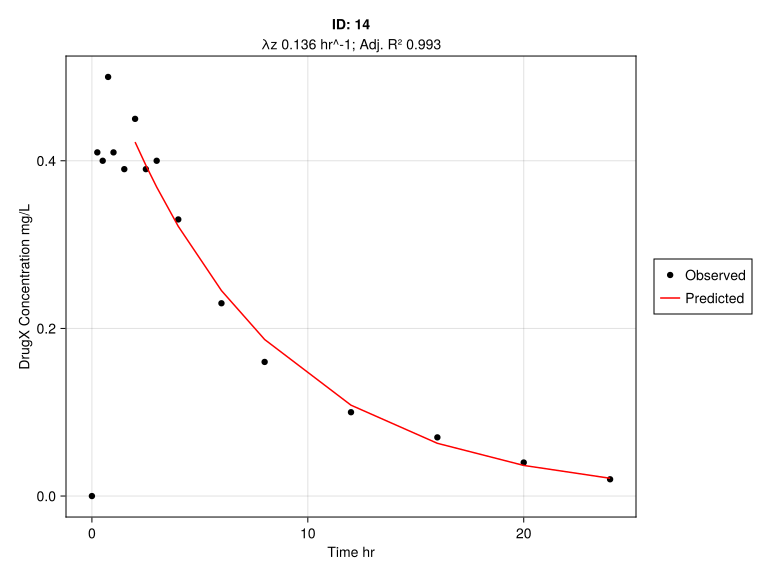
report_sd = run_nca(pop)You can view the individual subject fits in an interactive way, but for the tutorial we will showcase the non-interactive way:
individual_fits = subject_fits(
    pop;
    axis = (;
        xlabel = "Time hr",
        ylabel = "DrugX Concentration mg/L",
        yscale = log10,
        width = 180,
        height = 180,
    ),
    paginate = true,
    limit = 16,
)
Giving the axes a fixed width and height sizes the figure to its content, which keeps the per-subject subtitles from overlapping.
The above code generates a vector of plots with 16 subjects each (4 x 4). To view each set of plots, you can access via the vector index e.g.
individual_fits[1]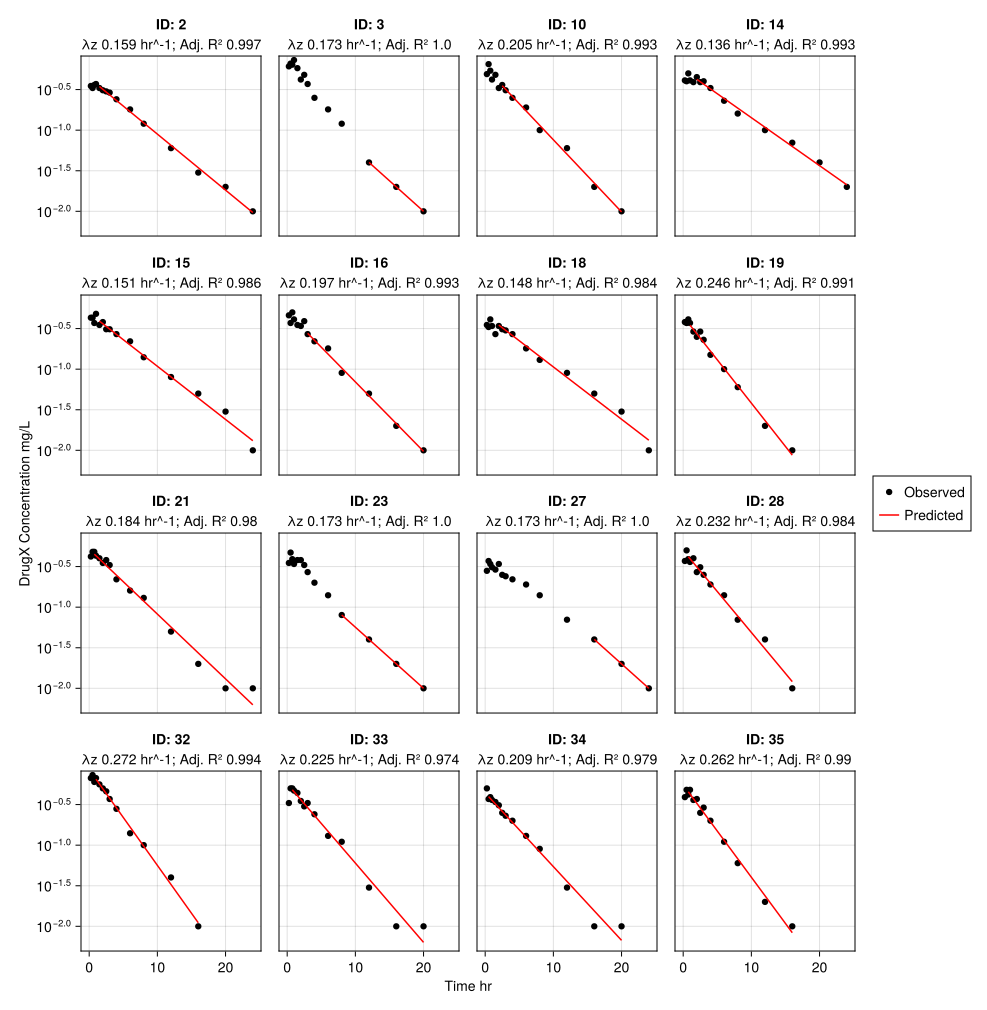
1.0.4.1 Create Parameters Summaries
params = [:cmax, :aucinf_obs]2-element Vector{Symbol}:
:cmax
:aucinf_obsparam_summary_sd = summarize(report_sd; parameters = params)2×10 DataFrame
| Row | parameters | numsamples | nonmissing | minimum | maximum | mean | std | geomean | geostd | geomeanCV |
|---|---|---|---|---|---|---|---|---|---|---|
| String | Int64 | Int64 | Float64 | Float64 | Float64 | Float64 | Float64 | Float64 | Float64 | |
| 1 | cmax | 107 | 107 | 0.34 | 0.77 | 0.515888 | 0.0956897 | 0.507222 | 1.20349 | 18.6827 |
| 2 | aucinf_obs | 107 | 107 | 1.6089 | 4.17295 | 2.61075 | 0.461858 | 2.56963 | 1.19822 | 18.2322 |
One can use some of the plotting functions to visualize the distribution of the parameters.
parameters_dist(report_sd; parameter = :aucinf_obs)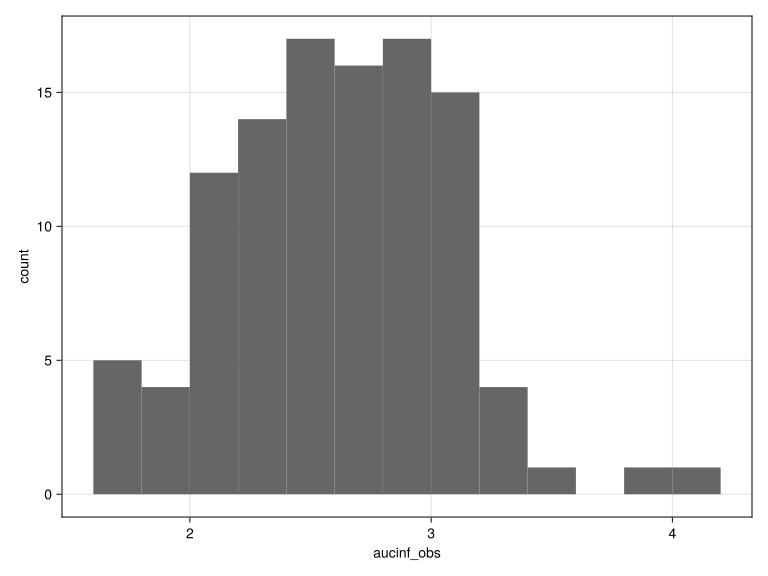
1.0.4.2 Compute Specific Parameters
We will now compute the specific parameters that we require and merge all of them to a dataframe. Each parameter is requested from run_nca by name.
Volume of Distribution/F, in this case since the drug is given orally
vz = run_nca(pop, [:vz_f_obs])
first(vz, 5)
5×8 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | vz_f_obs |
|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Quantity… | |
| 1 | 2 | 1 | 50.0 mg | ev | missing | missing | missing | 116.994 L |
| 2 | 3 | 2 | 50.0 mg | ev | missing | missing | missing | 90.694 L |
| 3 | 10 | 3 | 50.0 mg | ev | missing | missing | missing | 86.099 L |
| 4 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 95.2837 L |
| 5 | 15 | 5 | 50.0 mg | ev | missing | missing | missing | 102.629 L |
Clearance/F, in this case since the drug is given orally
cl = run_nca(pop, [:cl_f_obs])
first(cl, 5)
5×8 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | cl_f_obs |
|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Quantity… | |
| 1 | 2 | 1 | 50.0 mg | ev | missing | missing | missing | 18.5931 L hr^-1 |
| 2 | 3 | 2 | 50.0 mg | ev | missing | missing | missing | 15.7161 L hr^-1 |
| 3 | 10 | 3 | 50.0 mg | ev | missing | missing | missing | 17.6125 L hr^-1 |
| 4 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 12.9591 L hr^-1 |
| 5 | 15 | 5 | 50.0 mg | ev | missing | missing | missing | 15.4735 L hr^-1 |
Terminal Elimination Rate Constant, threshold=3 specifies the max no. of time point used for calculation
lambdaz = run_nca(pop, [:lambdaz]; threshold = 3)
first(lambdaz, 5)
5×8 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | lambdaz |
|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Quantity… | |
| 1 | 2 | 1 | 50.0 mg | ev | missing | missing | missing | 0.137327 hr^-1 |
| 2 | 3 | 2 | 50.0 mg | ev | missing | missing | missing | 0.173287 hr^-1 |
| 3 | 10 | 3 | 50.0 mg | ev | missing | missing | missing | 0.22397 hr^-1 |
| 4 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 0.156595 hr^-1 |
| 5 | 15 | 5 | 50.0 mg | ev | missing | missing | missing | 0.20118 hr^-1 |
The exact time points that the slope is calculated from are selected with a boolean lambdaz_mask column added to the data before it is read.
single_dose_data_slopetimes =
    @rtransform single_dose_data :lambdaz_mask = :TIME in (8, 12, 16)
pop_slopetimes = read_nca_pumas(
    single_dose_data_slopetimes;
    id = :ID,
    time = :TIME,
    concentration = :CONC,
    dose = :AMT,
    route = :ROUTE,
    time_unit = timeu,
    concentration_unit = concu,
    dose_unit = amtu,
)
lambdaz_1 = run_nca(pop_slopetimes, [:lambdaz => :lambdaz_specf])
first(lambdaz_1, 5)
5×9 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | lambdaz_specf | lambdaz_specf_err |
|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Quantity…? | String? | |
| 1 | 2 | 1 | 50.0 mg | ev | missing | missing | missing | 0.173287 hr^-1 | missing |
| 2 | 3 | 2 | 50.0 mg | ev | missing | missing | missing | 0.22397 hr^-1 | missing |
| 3 | 10 | 3 | 50.0 mg | ev | missing | missing | missing | 0.20118 hr^-1 | missing |
| 4 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 0.103335 hr^-1 | missing |
| 5 | 15 | 5 | 50.0 mg | ev | missing | missing | missing | 0.128702 hr^-1 | missing |
Half-life calculation for the 4th individual
thalf = run_nca(pop, [:half_life])
@rsubset thalf :id == ids[4]
1×8 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | half_life |
|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Quantity… | |
| 1 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 5.09648 hr |
Dose Normalized Cmax
cmax_d = run_nca(pop, [:cmax_dn])
first(cmax_d, 5)
5×8 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | cmax_dn |
|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Quantity… | |
| 1 | 2 | 1 | 50.0 mg | ev | missing | missing | missing | 0.0074 L^-1 |
| 2 | 3 | 2 | 50.0 mg | ev | missing | missing | missing | 0.0146 L^-1 |
| 3 | 10 | 3 | 50.0 mg | ev | missing | missing | missing | 0.013 L^-1 |
| 4 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 0.01 L^-1 |
| 5 | 15 | 5 | 50.0 mg | ev | missing | missing | missing | 0.0096 L^-1 |
Mean residence time
mrt = run_nca(pop, [:mrtinf_obs])
first(mrt, 5)
5×8 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | mrtinf_obs |
|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Quantity… | |
| 1 | 2 | 1 | 50.0 mg | ev | missing | missing | missing | 6.36645 hr |
| 2 | 3 | 2 | 50.0 mg | ev | missing | missing | missing | 4.53536 hr |
| 3 | 10 | 3 | 50.0 mg | ev | missing | missing | missing | 4.98956 hr |
| 4 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 7.53794 hr |
| 5 | 15 | 5 | 50.0 mg | ev | missing | missing | missing | 6.69361 hr |
AUMC calculation, using :linlog method
aumc = run_nca(pop, [:aumcinf_obs]; method = :linlog)
first(aumc, 5)
5×8 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | aumcinf_obs |
|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Quantity… | |
| 1 | 2 | 1 | 50.0 mg | ev | missing | missing | missing | 17.1523 mg hr^2 L^-1 |
| 2 | 3 | 2 | 50.0 mg | ev | missing | missing | missing | 14.3832 mg hr^2 L^-1 |
| 3 | 10 | 3 | 50.0 mg | ev | missing | missing | missing | 14.1224 mg hr^2 L^-1 |
| 4 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 29.1743 mg hr^2 L^-1 |
| 5 | 15 | 5 | 50.0 mg | ev | missing | missing | missing | 21.6259 mg hr^2 L^-1 |
Every result carries the same dose metadata columns, so we select each one down to its endpoints before joining them on the profile identifiers.
endpoints_only(df) =
    select(df, :id, :profile, Not([:dose, :route, :duration, :tau, :assumed_tau]))
individual_params = innerjoin(
    endpoints_only.([vz, cl, lambdaz, lambdaz_1, cmax_d, mrt, aumc])...;
    on = [:id, :profile],
)
first(individual_params, 5)
5×10 DataFrame
| Row | id | profile | vz_f_obs | cl_f_obs | lambdaz | lambdaz_specf | lambdaz_specf_err | cmax_dn | mrtinf_obs | aumcinf_obs |
|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | Quantity… | Quantity… | Quantity…? | String? | Quantity… | Quantity… | Quantity… | |
| 1 | 2 | 1 | 116.994 L | 18.5931 L hr^-1 | 0.137327 hr^-1 | 0.173287 hr^-1 | missing | 0.0074 L^-1 | 6.36645 hr | 17.1523 mg hr^2 L^-1 |
| 2 | 3 | 2 | 90.694 L | 15.7161 L hr^-1 | 0.173287 hr^-1 | 0.22397 hr^-1 | missing | 0.0146 L^-1 | 4.53536 hr | 14.3832 mg hr^2 L^-1 |
| 3 | 10 | 3 | 86.099 L | 17.6125 L hr^-1 | 0.22397 hr^-1 | 0.20118 hr^-1 | missing | 0.013 L^-1 | 4.98956 hr | 14.1224 mg hr^2 L^-1 |
| 4 | 14 | 4 | 95.2837 L | 12.9591 L hr^-1 | 0.156595 hr^-1 | 0.103335 hr^-1 | missing | 0.01 L^-1 | 7.53794 hr | 29.1743 mg hr^2 L^-1 |
| 5 | 15 | 5 | 102.629 L | 15.4735 L hr^-1 | 0.20118 hr^-1 | 0.128702 hr^-1 | missing | 0.0096 L^-1 | 6.69361 hr | 21.6259 mg hr^2 L^-1 |
1.0.4.3 Calculate AUC at specific intervals
Calculation of AUC at specific time intervals is done with the auc_partial endpoint, where each interval gets its own output name:
# various other methods are :linear, :linlog
partial_aucs = run_nca(
    pop,
    [
        :auc_partial =>
            (; interval = (0timeu, 12timeu), method = :linuplogdown) => :auc0_12,
        :auc_partial =>
            (; interval = (12timeu, 24timeu), method = :linuplogdown) => :auc12_24,
    ],
)
first(partial_aucs, 5)
5×9 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | auc0_12 | auc12_24 |
|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Quantity… | Quantity… | |
| 1 | 2 | 1 | 50.0 mg | ev | missing | missing | missing | 2.2645 mg hr L^-1 | 0.329483 mg hr L^-1 |
| 2 | 3 | 2 | 50.0 mg | ev | missing | missing | missing | 2.89846 mg hr L^-1 | 0.193123 mg hr L^-1 |
| 3 | 10 | 3 | 50.0 mg | ev | missing | missing | missing | 2.54614 mg hr L^-1 | 0.223346 mg hr L^-1 |
| 4 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 3.00976 mg hr L^-1 | 0.666289 mg hr L^-1 |
| 5 | 15 | 5 | 50.0 mg | ev | missing | missing | missing | 2.6432 mg hr L^-1 | 0.484746 mg hr L^-1 |
final = innerjoin(report_sd, endpoints_only(partial_aucs); on = [:id, :profile])
first(final, 5)
5×50 DataFrame
| Row | id | profile | dose | route | duration | tau | assumed_tau | auc_extrap_percent_obs | auc_extrap_percent_pred | aucinf_dn_obs | aucinf_dn_pred | aucinf_obs | aucinf_pred | auclast | auclast_dn | aumc_extrap_percent_obs | aumc_extrap_percent_pred | aumcinf_obs | aumcinf_pred | aumclast | cl_f_obs | cl_f_pred | clast | clast_pred | cmax | cmax_dn | cmin | cmin_dn | half_life | lambdaz | lambdazadjr2 | lambdazintercept | lambdaznpoints | lambdazr2 | lambdaztimefirst | lambdaztimelast | mrtinf_obs | mrtinf_pred | mrtlast | n_samples | span | tfinal | tlag | tlast | tmax | tmin | vz_f_obs | vz_f_pred | auc0_12 | auc12_24 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | String | Missing | Missing | Missing | Float64 | Float64 | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Float64 | Float64 | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Float64 | Float64 | Int64 | Float64 | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Int64 | Float64 | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | |
| 1 | 2 | 1 | 50.0 mg | ev | missing | missing | missing | 2.33989 | 2.26095 | 0.0537835 hr L^-1 | 0.05374 hr L^-1 | 2.68917 mg hr L^-1 | 2.687 mg hr L^-1 | 2.62625 mg hr L^-1 | 0.052525 hr L^-1 | 11.1335 | 10.7907 | 17.1205 mg hr^2 L^-1 | 17.0547 mg hr^2 L^-1 | 15.2144 mg hr^2 L^-1 | 18.5931 L hr^-1 | 18.6081 L hr^-1 | 0.01 mg L^-1 | 0.00965482 mg L^-1 | 0.37 mg L^-1 | 0.0074 L^-1 | 0.0 mg L^-1 | 0.0 L^-1 | 4.36154 hr | 0.158923 hr^-1 | 0.996589 | -0.826153 | 11 | 0.99693 | 1.5 hr | 24.0 hr | 6.36645 hr | 6.34711 hr | 5.79319 hr | 16 | 5.15873 | 24.0 hr | 0.0 hr | 24.0 hr | 1.0 hr | 0.0 hr | 116.994 L | 117.089 L | 2.2645 mg hr L^-1 | 0.329483 mg hr L^-1 |
| 2 | 3 | 2 | 50.0 mg | ev | missing | missing | missing | 1.81388 | 1.81388 | 0.0636292 hr L^-1 | 0.0636292 hr L^-1 | 3.18146 mg hr L^-1 | 3.18146 mg hr L^-1 | 3.12375 mg hr L^-1 | 0.062475 hr L^-1 | 10.3068 | 10.3068 | 14.4291 mg hr^2 L^-1 | 14.4291 mg hr^2 L^-1 | 12.9419 mg hr^2 L^-1 | 15.7161 L hr^-1 | 15.7161 L hr^-1 | 0.01 mg L^-1 | 0.01 mg L^-1 | 0.73 mg L^-1 | 0.0146 L^-1 | 0.0 mg L^-1 | 0.0 L^-1 | 4.0 hr | 0.173287 hr^-1 | 1.0 | -1.13943 | 3 | 1.0 | 12.0 hr | 20.0 hr | 4.53536 hr | 4.53536 hr | 4.14306 hr | 16 | 2.0 | 24.0 hr | 0.0 hr | 20.0 hr | 1.0 hr | 0.0 hr | 90.694 L | 90.694 L | 2.89846 mg hr L^-1 | 0.193123 mg hr L^-1 |
| 3 | 10 | 3 | 50.0 mg | ev | missing | missing | missing | 1.72198 | 1.69357 | 0.0567777 hr L^-1 | 0.0567613 hr L^-1 | 2.83889 mg hr L^-1 | 2.83806 mg hr L^-1 | 2.79 mg hr L^-1 | 0.0558 hr L^-1 | 8.58943 | 8.45747 | 14.1648 mg hr^2 L^-1 | 14.1444 mg hr^2 L^-1 | 12.9481 mg hr^2 L^-1 | 17.6125 L hr^-1 | 17.6176 L hr^-1 | 0.01 mg L^-1 | 0.00983218 mg L^-1 | 0.65 mg L^-1 | 0.013 L^-1 | 0.0 mg L^-1 | 0.0 L^-1 | 3.38845 hr | 0.204562 hr^-1 | 0.993176 | -0.530861 | 8 | 0.994151 | 2.5 hr | 20.0 hr | 4.98956 hr | 4.98381 hr | 4.64091 hr | 16 | 5.1646 | 24.0 hr | 0.0 hr | 20.0 hr | 0.5 hr | 0.0 hr | 86.099 L | 86.1239 L | 2.54614 mg hr L^-1 | 0.223346 mg hr L^-1 |
| 4 | 14 | 4 | 50.0 mg | ev | missing | missing | missing | 3.81135 | 4.02956 | 0.0771661 hr L^-1 | 0.0773415 hr L^-1 | 3.8583 mg hr L^-1 | 3.86708 mg hr L^-1 | 3.71125 mg hr L^-1 | 0.074225 hr L^-1 | 15.8526 | 16.6409 | 29.0836 mg hr^2 L^-1 | 29.3587 mg hr^2 L^-1 | 24.4731 mg hr^2 L^-1 | 12.9591 L hr^-1 | 12.9297 L hr^-1 | 0.02 mg L^-1 | 0.0211931 mg L^-1 | 0.5 mg L^-1 | 0.01 L^-1 | 0.0 mg L^-1 | 0.0 L^-1 | 5.09648 hr | 0.136005 hr^-1 | 0.992565 | -0.589958 | 10 | 0.993391 | 2.0 hr | 24.0 hr | 7.53794 hr | 7.59196 hr | 6.59431 hr | 16 | 4.3167 | 24.0 hr | 0.0 hr | 24.0 hr | 0.75 hr | 0.0 hr | 95.2837 L | 95.0675 L | 3.00976 mg hr L^-1 | 0.666289 mg hr L^-1 |
| 5 | 15 | 5 | 50.0 mg | ev | missing | missing | missing | 2.05258 | 2.6782 | 0.0646265 hr L^-1 | 0.065042 hr L^-1 | 3.23133 mg hr L^-1 | 3.2521 mg hr L^-1 | 3.165 mg hr L^-1 | 0.0633 hr L^-1 | 9.3934 | 11.9828 | 21.6292 mg hr^2 L^-1 | 22.2655 mg hr^2 L^-1 | 19.5975 mg hr^2 L^-1 | 15.4735 L hr^-1 | 15.3747 L hr^-1 | 0.01 mg L^-1 | 0.0131319 mg L^-1 | 0.48 mg L^-1 | 0.0096 L^-1 | 0.0 mg L^-1 | 0.0 L^-1 | 4.59733 hr | 0.150772 hr^-1 | 0.98643 | -0.714195 | 11 | 0.987787 | 1.5 hr | 24.0 hr | 6.69361 hr | 6.84651 hr | 6.19194 hr | 16 | 4.89414 | 24.0 hr | 0.0 hr | 24.0 hr | 1.0 hr | 0.0 hr | 102.629 L | 101.973 L | 2.6432 mg hr L^-1 | 0.484746 mg hr L^-1 |
1.0.5 The steady-state profile
An NCA profile always belongs to a single dose, so the day 5 samples are read as their own profiles. Filter the data for time > 24 hrs to get them:
multiple_dose_data = @rsubset data :TIME > 24
first(multiple_dose_data, 5)
5×6 DataFrame
| Row | ID | TIME | CONC | AMT | ROUTE | II |
|---|---|---|---|---|---|---|
| Int64 | Float64 | Float64 | Int64? | String3 | Int64? | |
| 1 | 2 | 96.0 | 0.01 | 50 | ev | 24 |
| 2 | 2 | 96.25 | 0.43 | missing | ev | missing |
| 3 | 2 | 96.5 | 0.46 | missing | ev | missing |
| 4 | 2 | 96.75 | 0.4 | missing | ev | missing |
| 5 | 2 | 97.0 | 0.37 | missing | ev | missing |
These profiles were measured at steady state, so the dosing interval is passed as tau and the parameters that are calculated over the dosing interval become available. You can select the NCA parameters that you wish to see in the output with the second argument of run_nca.
pop_md = read_nca_pumas(
    multiple_dose_data;
    id = :ID,
    time = :TIME,
    concentration = :CONC,
    dose = :AMT,
    route = :ROUTE,
    tau = :II, # the dosing interval of the steady state profile
    time_unit = timeu,
    concentration_unit = concu,
    dose_unit = amtu,
)
pop_md = transform_nca(
    pop_md;
    llq = 0.001concu,
    blq_rules = Dict(:first => :keep, :middle => :drop, :last => :keep),
)
1712×15 DataFrame
1687 rows omitted
| Row | id | profile | time | nominal_time | dose_time | nominal_dose_time | concentration_before_blq | concentration | dose | route | duration | tau | exclusion | exclusion_mask | blq |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | Quantity… | String | Missing | Quantity… | Missing | Bool | Bool | |
| 1 | 2 | 1 | 0.0 hr | 0.0 hr | 96.0 hr | 96.0 hr | 0.01 mg L^-1 | 0.01 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 2 | 2 | 1 | 0.25 hr | 0.25 hr | 96.0 hr | 96.0 hr | 0.43 mg L^-1 | 0.43 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 3 | 2 | 1 | 0.5 hr | 0.5 hr | 96.0 hr | 96.0 hr | 0.46 mg L^-1 | 0.46 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 4 | 2 | 1 | 0.75 hr | 0.75 hr | 96.0 hr | 96.0 hr | 0.4 mg L^-1 | 0.4 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 5 | 2 | 1 | 1.0 hr | 1.0 hr | 96.0 hr | 96.0 hr | 0.37 mg L^-1 | 0.37 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 6 | 2 | 1 | 1.5 hr | 1.5 hr | 96.0 hr | 96.0 hr | 0.33 mg L^-1 | 0.33 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 7 | 2 | 1 | 2.0 hr | 2.0 hr | 96.0 hr | 96.0 hr | 0.31 mg L^-1 | 0.31 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 8 | 2 | 1 | 2.5 hr | 2.5 hr | 96.0 hr | 96.0 hr | 0.27 mg L^-1 | 0.27 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 9 | 2 | 1 | 3.0 hr | 3.0 hr | 96.0 hr | 96.0 hr | 0.23 mg L^-1 | 0.23 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 10 | 2 | 1 | 4.0 hr | 4.0 hr | 96.0 hr | 96.0 hr | 0.23 mg L^-1 | 0.23 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 11 | 2 | 1 | 6.0 hr | 6.0 hr | 96.0 hr | 96.0 hr | 0.16 mg L^-1 | 0.16 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 12 | 2 | 1 | 8.0 hr | 8.0 hr | 96.0 hr | 96.0 hr | 0.13 mg L^-1 | 0.13 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 13 | 2 | 1 | 12.0 hr | 12.0 hr | 96.0 hr | 96.0 hr | 0.06 mg L^-1 | 0.06 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ | ⋮ |
| 1701 | 200 | 107 | 1.0 hr | 1.0 hr | 96.0 hr | 96.0 hr | 0.37 mg L^-1 | 0.37 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1702 | 200 | 107 | 1.5 hr | 1.5 hr | 96.0 hr | 96.0 hr | 0.37 mg L^-1 | 0.37 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1703 | 200 | 107 | 2.0 hr | 2.0 hr | 96.0 hr | 96.0 hr | 0.34 mg L^-1 | 0.34 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1704 | 200 | 107 | 2.5 hr | 2.5 hr | 96.0 hr | 96.0 hr | 0.29 mg L^-1 | 0.29 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1705 | 200 | 107 | 3.0 hr | 3.0 hr | 96.0 hr | 96.0 hr | 0.27 mg L^-1 | 0.27 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1706 | 200 | 107 | 4.0 hr | 4.0 hr | 96.0 hr | 96.0 hr | 0.2 mg L^-1 | 0.2 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1707 | 200 | 107 | 6.0 hr | 6.0 hr | 96.0 hr | 96.0 hr | 0.14 mg L^-1 | 0.14 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1708 | 200 | 107 | 8.0 hr | 8.0 hr | 96.0 hr | 96.0 hr | 0.09 mg L^-1 | 0.09 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1709 | 200 | 107 | 12.0 hr | 12.0 hr | 96.0 hr | 96.0 hr | 0.05 mg L^-1 | 0.05 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1710 | 200 | 107 | 16.0 hr | 16.0 hr | 96.0 hr | 96.0 hr | 0.02 mg L^-1 | 0.02 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1711 | 200 | 107 | 20.0 hr | 20.0 hr | 96.0 hr | 96.0 hr | 0.01 mg L^-1 | 0.01 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | false |
| 1712 | 200 | 107 | 24.0 hr | 24.0 hr | 96.0 hr | 96.0 hr | 0.0 mg L^-1 | 0.0 mg L^-1 | 50.0 mg | ev | missing | 24.0 hr | missing | false | true |
md_params = [
    :half_life,
    :tmax,
    :cmax,
    :auclast,
    :auctau_obs,
    :vz_f_pred,
    :cl_f_pred,
    :aumcinf_obs,
    :cavg,
]
report_md = run_nca(pop_md, md_params)
Note
At steady state, clearance and volume of distribution are derived from the AUC over the dosing interval, so cl_f_pred and vz_f_pred are requested here instead of cl_f_obs and vz_f_obs. The average concentration over the interval is cavg.
Just like for the first-dose profiles you can compute individual parameters and merge them to the final report.
Compute the summary statistics of the selected variables that you require:
param_summary_md = summarize(report_md; parameters = md_params)9×10 DataFrame
| Row | parameters | numsamples | nonmissing | minimum | maximum | mean | std | geomean | geostd | geomeanCV |
|---|---|---|---|---|---|---|---|---|---|---|
| String | Int64 | Int64 | Float64 | Float64 | Float64 | Float64 | Float64 | Float64 | Float64 | |
| 1 | half_life | 107 | 107 | 1.9074 | 5.93739 | 3.51682 | 0.741075 | 3.43644 | 1.24597 | 22.2599 |
| 2 | tmax | 107 | 107 | 0.25 | 1.5 | 0.570093 | 0.232385 | 0.523904 | 1.52739 | 44.3287 |
| 3 | cmax | 107 | 107 | 0.32 | 0.84 | 0.521215 | 0.100599 | 0.51204 | 1.20711 | 18.9908 |
| 4 | auclast | 107 | 107 | 1.47125 | 4.11375 | 2.58982 | 0.498424 | 2.54104 | 1.21959 | 20.049 |
| 5 | auctau_obs | 107 | 107 | 1.49125 | 4.11375 | 2.60254 | 0.492372 | 2.55521 | 1.21524 | 19.6807 |
| 6 | vz_f_pred | 107 | 107 | 58.0001 | 153.212 | 98.9164 | 19.3711 | 97.0123 | 1.22153 | 20.2124 |
| 7 | cl_f_pred | 107 | 107 | 12.1544 | 33.5289 | 19.9489 | 4.06361 | 19.5679 | 1.21524 | 19.6807 |
| 8 | aumcinf_obs | 107 | 107 | 4.99686 | 29.689 | 13.809 | 4.96719 | 12.9386 | 1.44561 | 38.1404 |
| 9 | cavg | 107 | 107 | 0.0621354 | 0.171406 | 0.108439 | 0.0205155 | 0.106467 | 1.21524 | 19.6807 |
1.0.6 Documentation
Please refer to the NCA Documentation for any further help.
1.0.7 Save NCA Report
Earlier versions of NCA had a report function which took the run_nca and summarize output and generated a PDF report from it, with a fixed layout and the study metadata that was passed to run_nca. It has been removed in favor of the Quarto workflow: what goes into the report, and in which order, is now up to the document, tables and figures can come from anywhere in the Pumas ecosystem, and the same source renders to HTML, PDF or Word.
The results and summaries above are plain DataFrames and figures, so a report is written as a Quarto document, like this one, that runs the analysis and renders its tables and figures. The study metadata goes into the document header and the tables and figures are the values that the cells return.
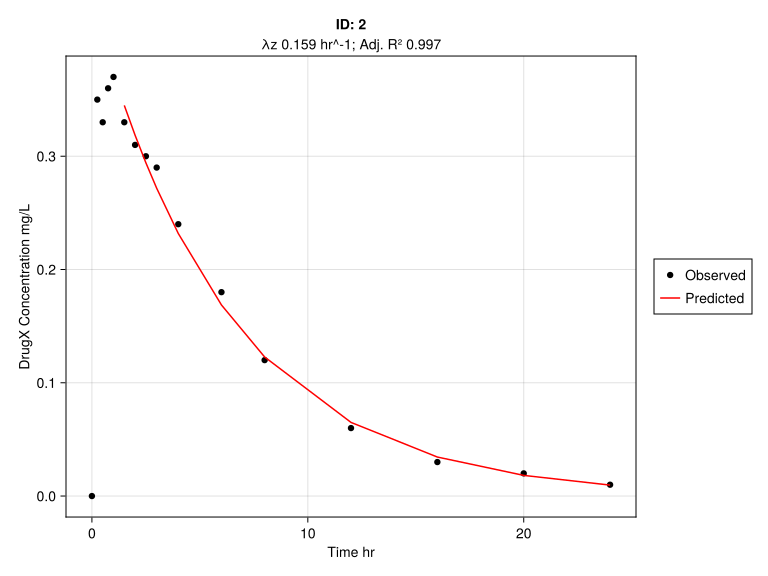
A report usually shows a figure per subject, which is a number that is only known at runtime. QuartoTools provides objects for that: Expand inserts a vector of values into the document one after another, and a Div whose id starts with fig- becomes a numbered figure whose caption is its trailing MarkdownCell, so it can be cross-referenced as @fig-fit-2.
using QuartoTools: Div, Expand, MarkdownCell

Expand([
    Div(
        [
            subject_fits(
                pop;
                ids = [id],
                axis = (; xlabel = "Time hr", ylabel = "DrugX Concentration mg/L"),
            ),
            MarkdownCell("Individual fit for subject $id"),
        ],
        id = "fig-fit-$id",
    ) for id in ids[1:4]
])
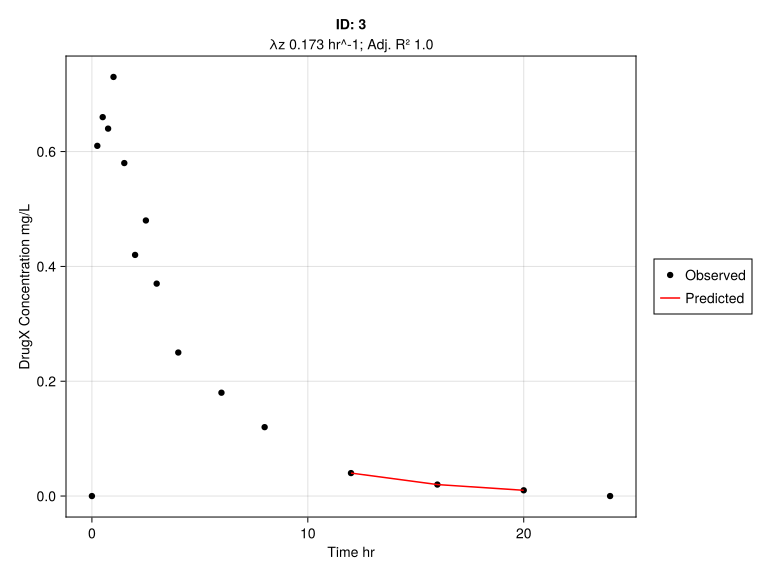
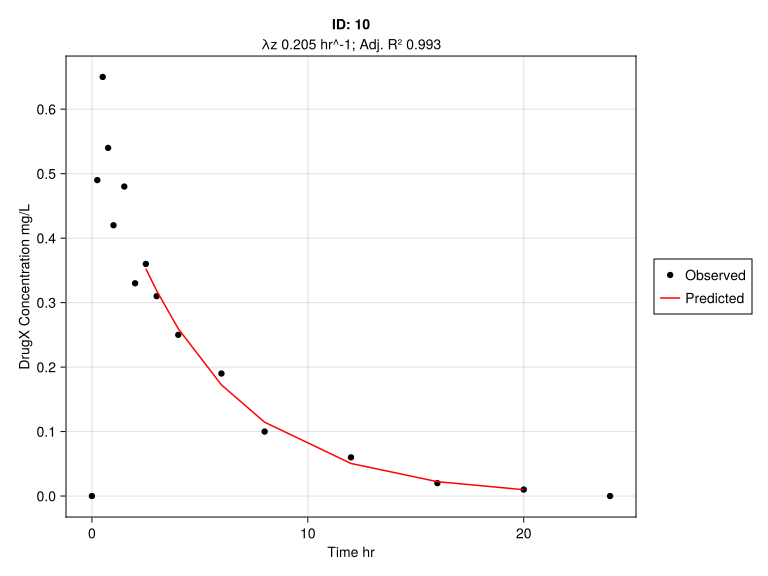
The reporting tutorials cover these building blocks in detail.