using NCA
using PumasUtilities
Plot customization for Noncompartmental analysis - Multiple Ascending Dose
1 Libraries
We will load the NCA and PumasUtilities packages in order to have access to Pumas’ core and utilities functions for Noncompartmental analysis:
We will also use Makie.jl as the main plotting library and also AlgebraOfGraphics.jl.
CairoMakie.jl will act as our plotting backend and will also make possible the various customization options that we will go over. On the other hand, AlgebraOfGraphics.jl will provide a syntax inspired by the grammar of graphics and similar to R’s ggplot2 to create complex plots.
using CairoMakie
using AlgebraOfGraphics
Lastly, we will use the CSV.jl package to read external data, DataFramesMeta.jl for data wrangling, Unitful.jl for units and mean from Statistics.jl.
using CSV
using DataFrames
using DataFramesMeta
using Unitful
using Statistics: mean
2 Introduction
We will continue with our series on plot customization for noncompartmental analysis, where we aim to show you how to customize some of the plots available in the Pumas NCA workflow and create unique plots and layouts using Pumas and Makie.jl.
2.1 🔙 Quick reminder
Tip
Make sure to check our tutorial on Plot customization for Noncompartmental analysis - Single Ascending Dose for a more detailed discussion on the motivation of this series of tutorials
We are trying to apply a consistent color palette across the plots generated in our NCA workflow. Our color palette is comprised of five colors, which we divide into two main colors and three complementary colors:
2.1.0.1 Main colors
2.1.0.1.1 Complementary colors
These will be used for highlighting and more complex plots
Here’s a summary of our palette containing the names and hex codes for each color:
- Navy Blue:
#0B1E3F - Emerald Green:
#50C878 - Coral:
#FF7F50 - Mustard yellow:
#FFDB58 - Deep purple:
#6A5ACD
Note
Makie uses Colors.jl to define colors. This means that you can pass a string representing any [CSS color] (https://developer.mozilla.org/en-US/docs/Web/CSS/color) to Pumas and Makie’s plotting functions.
For instance, you could define the color red with "rgb(255,0,0)", "#FF0000", or "red". You can also use one of the named colors from Colors.jl by passing them as a Symbol (e.g :navyblue)
We will store the colors in a Vector so that we can access them later more easily. Let’s begin by defining the main and complementary colors. Notice that we are creating strings with the hex codes from above:
main_colors = ["#0B1E3F", "#50C878"];
complementary = ["#FF7F50", "#FFDB58", "#6A5ACD"];
We can join both Vectors of colors using vcat, which will concatenate main_colors and complementary_colors to create a single color palette Vector.
palette = vcat(complementary, main_colors);We would also like to use a shade of gray for the background color instead of the default white color
background = "#FAF9F6";3 Load Data
We will be using simulated data for an orally administered drug through multiple doses ranging from 100 to 1,600 mg.
Note
This tutorial is based on Alison Margolskee’s PK - Multiple Ascending Dose workflow. You can get the dataset used in this tutorial here.
Read the data using CSV.jl and convert it to a DataFrame
df = CSV.read("Multiple_Ascending_Dose_Dataset2.csv", DataFrame; missingstring = ["NA"])
first(df, 5)
5×18 DataFrame
| Row | ID | TIME | NOMTIME | TIMEUNIT | AMT | LIDV | CMT | NAME | EVENTU | CENS | EVID | WEIGHTB | SEX | TRTACT | DOSE | PROFDAY | PROFTIME | CYCLE |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Float64 | Float64 | String7 | Float64 | Float64? | Int64 | String31 | String15 | Int64 | Int64 | Float64 | String7 | String7 | Int64 | Int64 | Float64 | Int64 | |
| 1 | 1 | -23.957 | -24.0 | Hours | 0.0 | 3.0 | 5 | PD - Ordinal | severity | 0 | 0 | 77.9 | Male | Placebo | 0 | 0 | 0.0 | 0 |
| 2 | 1 | -0.005 | -0.1 | Hours | 0.0 | 3.29 | 3 | PD - Continuous | IU/L | 0 | 0 | 77.9 | Male | Placebo | 0 | 0 | 23.9 | 0 |
| 3 | 1 | -0.005 | -0.1 | Hours | 0.0 | 3.0 | 4 | PD - Count | count | 0 | 0 | 77.9 | Male | Placebo | 0 | 0 | 23.9 | 0 |
| 4 | 1 | -0.005 | -0.1 | Hours | 0.0 | 0.0 | 6 | PD - Binary | response | 0 | 0 | 77.9 | Male | Placebo | 0 | 0 | 23.9 | 0 |
| 5 | 1 | 0.0 | 0.0 | Hours | 1.0e-12 | missing | 1 | Dosing | mg | 0 | 1 | 77.9 | Male | Placebo | 0 | 1 | 0.0 | 1 |
3.1 Data wrangling
Tip
We have a series of tutorials on Data Wrangling in Julia, where you can learn more about reading and manipulating data.
We will start by eliminating the rows that contain a negative time (NOMTIME < 0), placebo observations (dose = 0), and only keep dosing and PK concentration events. We can do this using the @rsubset macro from DataFramesMeta.jl
@rsubset! df begin
    :NOMTIME >= 0
    :DOSE > 0
    :NAME ∈ ["Dosing", "PK Concentration"]
end;
We will also switch the time units to days (currently in hours) and create a column for the route of administration as extravascular ("ev"). The dataset marks rows without a dose with a 0 in the AMT column and the reader expects missing there, so we convert those as well.
@rtransform! df begin
    :NOMTIME = :NOMTIME / 24
    :ROUTE = "ev"
    :AMT = :AMT == 0 ? missing : :AMT
end;
Each subject received six daily doses. In NCA a profile always belongs to a single dose, so we number the doses of each subject and use that number as a grouping variable further down. The time of an observation is then the time after its own dose.
transform!(groupby(df, :ID), :AMT => (amt -> cumsum(.!ismissing.(amt))) => :dosenum);Finally, we have to define the units for the time (days), concentration (ng/mL), and dose amount (mg)
timeu = u"d";
concu = u"ng/mL";
amtu = u"mg";
Note
Notice that we have defined units using the u string literal (as in u"..."). This syntax corresponds to Unitful.jl, which is the Julia package from which Pumas obtains its unit support.
Now we are ready to read the data. Each dose sits on its own row with missing in the dose column everywhere else, which is the layout read_nca_pumas expects. Notice that we are setting the keyword argument group to [:DOSE, :dosenum] because we want to account for the different dosing levels in our analysis and to get one profile per dose.
nca_data = read_nca_pumas(
    df;
    id = :ID,
    time = :NOMTIME,
    concentration = :LIDV,
    dose = :AMT,
    route = :ROUTE,
    group = [:DOSE, :dosenum],
    time_unit = timeu,
    concentration_unit = concu,
    dose_unit = amtu,
);
4 Exploring concentration time profiles for each dose level
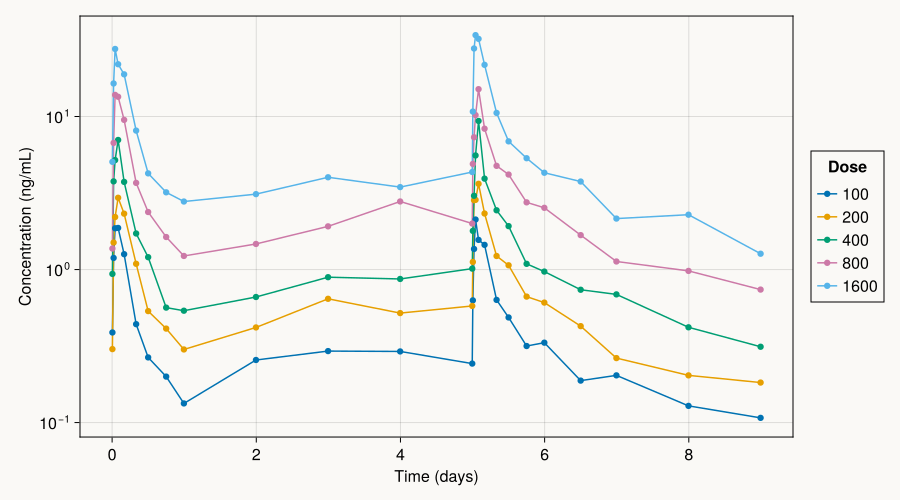
To explore the effect of dosing on drug concentration we will generate the average concentration time profile for each dose level over the whole course of the study. Since the NCA profiles each start at their own dose, we build this plot from the raw data with AlgebraOfGraphics.jl.
mean_profiles = @by @rsubset(df, !ismissing(:LIDV)) [:DOSE, :NOMTIME] begin
    :Cmean = mean(:LIDV)
end

draw(
    data(mean_profiles) *
    mapping(:NOMTIME, :Cmean; color = :DOSE => nonnumeric => "Dose") *
    (visual(Lines) + visual(Scatter));
    figure = (; backgroundcolor = background, size = (900, 500), fontsize = 16),
    axis = (;
        backgroundcolor = background,
        xlabel = "Time (days)",
        ylabel = "Concentration (ng/mL)",
        yscale = log10,
    ),
    legend = (; backgroundcolor = background),
)
Note
Don’t forget to check our tutorials on Plot customization for Noncompartmental analysis - Single Ascending Dose and Customization of AlgebraOfGraphics.jl Plots for a more detailed discussion on the extensive support for customization achievable with the axis and figure keyword arguments
Tip
You probably noticed that we assigned Set1_5 to the color keyword argument. Currently, summary_observations_vs_time only accepts a single color or a predefined colormap from ColorSchemes.jl. We are currently working to add support for a custom colormap and expect this feature to be available soon.
We recommend using a colormap if you are setting separate to false since this will allow you to get a different color for each line.
This plot allows us to clearly see that this is indeed a multiple dose scenario. We can see a sharp increase in concentration at every dosing day. This leads us to our next visualization: the concentration time profile after each dosing event. We will visualize the concentration profile of the first and of the last dose.
fig_days = Figure(; size = (1000, 600), backgroundcolor = background);Now we can add the plot for the first dose. We will use summary_observations_vs_time again, this time on the profiles of the first dose only:
summary_observations_vs_time(
    fig_days[1, 1],
    @rsubset(nca_data, :dosenum == 1);
    separate = false,
    group = [:DOSE],
    axis = (;
        backgroundcolor = background,
        xlabel = "Time after dose (days)",
        ylabel = "Concentration (ng/mL)",
        yscale = log10,
        title = "First dose",
    ),
    color = Makie.to_colormap(:Set1_5),
    errorbars = false,
);
Note
Because the data was read with dosenum as a grouping variable, every dose is a profile of its own and its time axis is the time after that dose. Selecting a dosing event is therefore a filter on the data instead of a limit on the axis.
If you do want to set axis limits manually, the limits argument accepts a tuple in the form (xlow, xhigh, ylow, yhigh), where nothing lets Makie.jl pick the limit. You can learn more in our tutorial on Customization of AlgebraOfGraphics.jl Plots and Makie.jl’s documentation on the attributes available for Axis
Tip
You can’t use the figure keyword argument if you are passing an Axis as the first positional argument to summary_observations_vs_time (fig_days[1, 1] in this case) or to any other of the Pumas’ plotting functions.
Let’s now add the plot for the last dose. We’ll just change the filter and the title argument for this:
fgrid = summary_observations_vs_time(
    fig_days[1, 2],
    @rsubset(nca_data, :dosenum == 6);
    separate = false,
    group = [:DOSE],
    axis = (;
        backgroundcolor = background,
        xlabel = "Time after dose (days)",
        ylabel = "Concentration (ng/mL)",
        yscale = log10,
        title = "Last dose",
    ),
    color = Makie.to_colormap(:Set1_5),
    errorbars = false,
);
Lastly, let’s add a legend:
legend!(fig_days[end+1, :], fgrid; orientation = :horizontal, backgroundcolor = background);
Tip
You can customize the looks of your legend by passing any of the supported attributes for Legend to the legend! function or to the legend keyword when using the plotting functions that create standalone figures.
Now we can check the results by inspecting the variable holding our Figure (fig_days in this case):
fig_days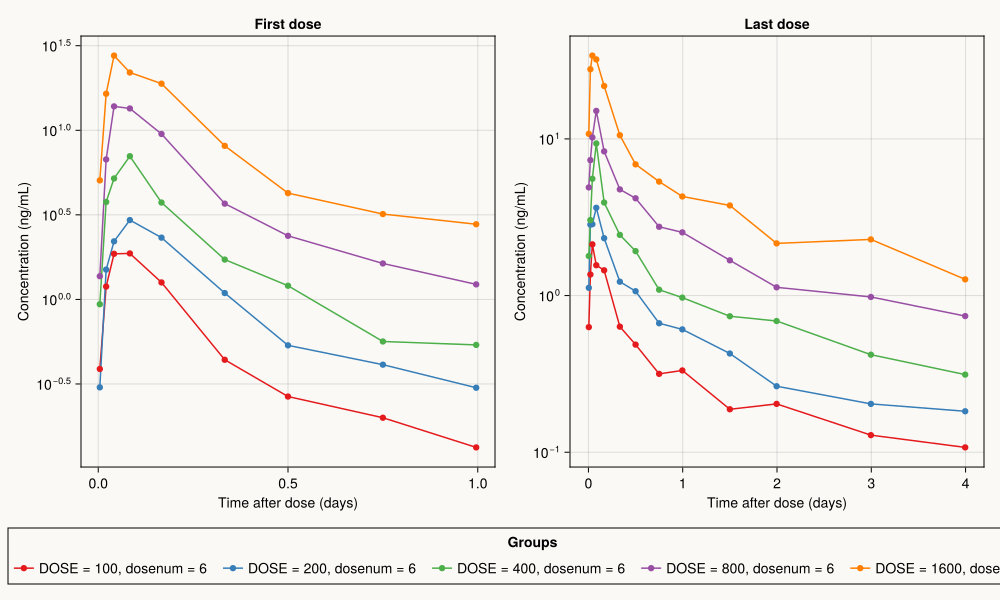
This plot allows us to see more clearly the concentration response to each dosing event. We can also use it to check if there is any accumulation of the first administered dose and the steady state response.
4.1 Subject variability
One way in which we might visualize subject variability is by plotting the average concentration profile overlaid on a spaghetti plot for all subjects in the population.
But before we do anything, we must eliminate the rows where the concentration (LIDV) has a value of missing, as this will cause errors when plotting:
df_clean = @rsubset(df, !ismissing(:LIDV));Now we can calculate the mean concentration profile for each dose level, we will need to import the function mean from Julia’s standard library package Statistics.jl
using Statistics: mean

df_sp = @by df_clean [:DOSE, :NOMTIME] begin
    :Cmean = mean(:LIDV)
end;
And that’s it for the wrangling. Let’s create our plot:
Note
We are going to be using AlgebraOfGraphics.jl for plotting. If you are unfamiliar with its syntax and use, feel free to refer to our series of tutorials on data visualization in Julia, starting with Introduction to AlgebraOfGraphics.jl.
We start by creating our plots, which we’ll pass to draw later. But let us do just one more thing before we start: we will define a renamer for the dose column. This will allow us to get a more readable legend.
dose_renamer = renamer(map(i -> i => "$(i) mg", unique(df.DOSE)));
Tip
You can pass a Vector of Pairs of the form (value in dataset => value to be displayed) to the renamer function provided by AoG.jl.
Make sure to check our tutorial on Customization of AlgebraOfGraphics.jl Plots to learn more about renamer and other utility functions provided by AoG.jl
plt_all =
    data(df_clean) *
    mapping(:NOMTIME, :LIDV; layout = :DOSE => dose_renamer, group = :ID => nonnumeric) *
    visual(ScatterLines; color = (:grey, 0.2));
plt_mean =
data(df_sp) *
mapping(:NOMTIME, :Cmean; layout = :DOSE => dose_renamer) *
visual(ScatterLines);draw(
plt_mean + plt_all;
axis = (; ylabel = "Concentration (ng/mL)", xlabel = "Time (days)", yscale = log10),
)
Another useful way to examine subject variability in the concentration response is to see the concentration profile for each subject. We can do this using observations_vs_time:
observations = observations_vs_time(
    nca_data;
    paginate = true,
    markercolor = main_colors[1],
    color = main_colors[2],
    axis = (;
        backgroundcolor = background,
        xlabel = "Time (days)",
        ylabel = "Concentration (ng/mL)",
    ),
    figure = (; backgroundcolor = background),
);
observations[1]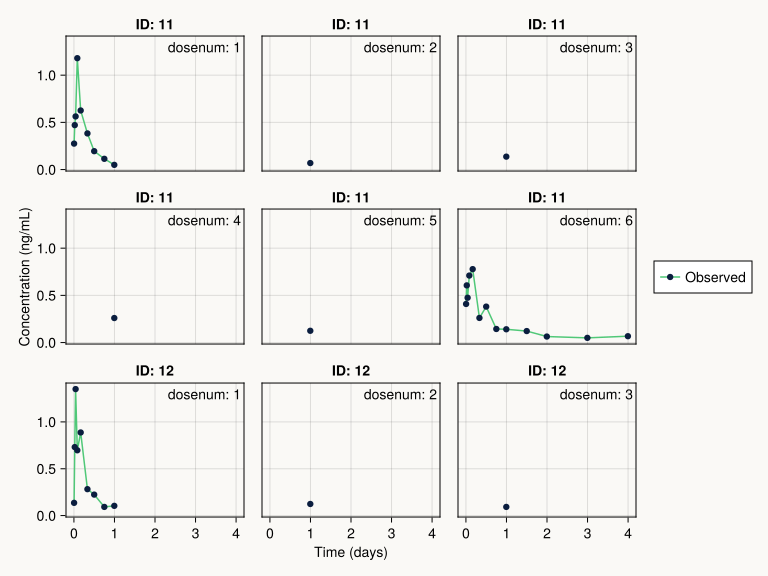
Tip
We recommend setting the keyword argument paginate to true for datasets containing many subjects (more than 9). By doing this, observations_vs_time will return a vector of plots instead of trying to cram all of them into the limited space of a single figure.
Also, make to check our tutorial on Plot customization for Noncompartmental analysis - Single Ascending Dose for a detailed explanation of the keyword arguments that you can use for observations_vs_time
5 Dose normalized concentration
In addition to the concentration time profile, it could also be interesting to analyze the dose-normalized concentration profile. Normalizing the concentration will allow us to assess the dose linearity of exposure and we will use the normalized concentration for the subsequent analysis.
We begin by creating a new column, NLIDV, which will be the concentration (LIDV) divided by the corresponding dose (DOSE):
@rtransform! df begin
    :NLIDV = :LIDV / :DOSE
end;
Now we read the data again, but this time the concentrations are the normalized ones:
nca_data_norm = read_nca_pumas(
    df;
    id = :ID,
    time = :NOMTIME,
    concentration = :NLIDV,
    dose = :AMT,
    route = :ROUTE,
    group = [:DOSE, :dosenum],
);
In order to get the normalized concentration profile for each dose level, we use summary_observations_vs_time on the profiles of the first dose:
summary_observations_vs_time(
    @rsubset(nca_data_norm, :dosenum == 1);
    separate = false,
    group = [:DOSE],
    figure = (; backgroundcolor = background),
    axis = (;
        backgroundcolor = background,
        xlabel = "Time (days)",
        ylabel = "Normalized Concentration (ng/mL)/mg",
        yscale = log10,
    ),
    legend = (; backgroundcolor = background),
    color = Makie.to_colormap(:Set1_5),
)
It is interesting to note that the normalized concentration is similar for every dose level. This suggests a linear effect of dose on the concentration profile.
Let’s perform a similar analysis as before and plot the normalized concentration profile for the first and the last dose:
fig_days_norm = Figure(; backgroundcolor = background)

summary_observations_vs_time(
    fig_days_norm[1, 1],
    @rsubset(nca_data_norm, :dosenum == 1);
    separate = false,
    group = [:DOSE],
    axis = (;
        backgroundcolor = background,
        xlabel = "Time after dose (days)",
        ylabel = "Concentration (ng/mL)",
        yscale = log10,
        title = "First dose",
    ),
    color = Makie.to_colormap(:Set1_5),
    errorbars = false,
)

fgrid = summary_observations_vs_time(
    fig_days_norm[1, 2],
    @rsubset(nca_data_norm, :dosenum == 6);
    separate = false,
    group = [:DOSE],
    axis = (;
        backgroundcolor = background,
        xlabel = "Time after dose (days)",
        ylabel = "Concentration (ng/mL)",
        yscale = log10,
        title = "Last dose",
    ),
    color = Makie.to_colormap(:Set1_5),
    errorbars = false,
)

legend!(
    fig_days_norm[end+1, :],
    fgrid;
    orientation = :horizontal,
    backgroundcolor = background,
)

fig_days_norm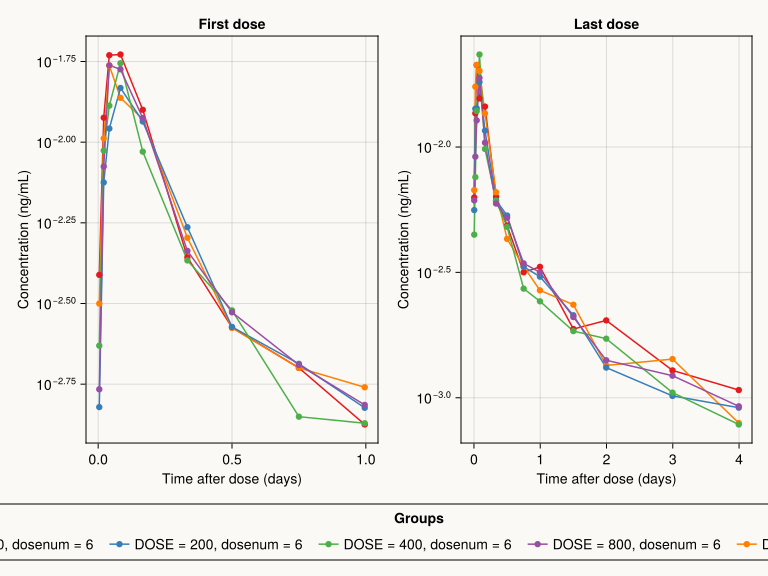
Note
Notice that this is essentially the same code as before. We just had to change our NCA data (nca_data to nca_data_norm) and our Figure (fig_days to fig_days_norm).
Also see that we included all the code in a single cell using the begin..end syntax. This was done to save some space on the notebook since we already went over how to create a custom figure layout
5.1 AUC
The dose normalized AUC is also an important means to assess whether the dose is producing a linear effect on the concentration profile. We will be calculating the AUC values for all dose levels and for the first and tenth day.
The partial AUC over a given time window after the dose is the auc_partial endpoint, which takes the window as its interval option and needs an output name. Since we are interested in the AUC over one day, we pass (0, 1). Let’s calculate the AUC values for the first subject as an example:
AUC_values = run_nca(nca_data_norm, [:auc_partial => (; interval = (0, 1)) => :auc0_1])
@rsubset AUC_values :id == first(AUC_values.id)
6×11 DataFrame
| Row | DOSE | dosenum | id | profile | dose | route | duration | tau | assumed_tau | auc0_1 | auc0_1_err |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Int64 | Int64 | Float64 | String | Missing | Missing | Missing | Float64? | String? | |
| 1 | 100 | 1 | 11 | 1 | 100.0 | ev | missing | missing | missing | 0.00320364 | missing |
| 2 | 100 | 2 | 11 | 2 | 100.0 | ev | missing | missing | missing | missing | Extrapolation beyond tfinal requires lambdaz_fit (interpextrapconc → auc) |
| 3 | 100 | 3 | 11 | 3 | 100.0 | ev | missing | missing | missing | missing | Extrapolation beyond tfinal requires lambdaz_fit (interpextrapconc → auc) |
| 4 | 100 | 4 | 11 | 4 | 100.0 | ev | missing | missing | missing | missing | Extrapolation beyond tfinal requires lambdaz_fit (interpextrapconc → auc) |
| 5 | 100 | 5 | 11 | 5 | 100.0 | ev | missing | missing | missing | missing | Extrapolation beyond tfinal requires lambdaz_fit (interpextrapconc → auc) |
| 6 | 100 | 6 | 11 | 6 | 100.0 | ev | missing | missing | missing | 0.00348585 | missing |
Note
Notice that we get one row per dose, six in our case. The doses in the middle (dosenum 2 to 5) were only sampled sparsely, so their AUC cannot be calculated and we get missing there, with the reason in the auc0_1_err column.
In our case, we are interested in the first and the last dose, since those are the two dosing events that were sampled densely.
Let’s get rid of the missing values with dropmissing!. Note that we name the column to drop rows by: the metadata columns of an NCA result are missing for this data, so dropping rows with any missing value would leave us with nothing.
dropmissing!(AUC_values, :auc0_1)
first(AUC_values, 5)
5×11 DataFrame
| Row | DOSE | dosenum | id | profile | dose | route | duration | tau | assumed_tau | auc0_1 | auc0_1_err |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Int64 | Int64 | Float64 | String | Missing | Missing | Missing | Float64 | String? | |
| 1 | 100 | 1 | 11 | 1 | 100.0 | ev | missing | missing | missing | 0.00320364 | missing |
| 2 | 100 | 6 | 11 | 6 | 100.0 | ev | missing | missing | missing | 0.00348585 | missing |
| 3 | 100 | 1 | 12 | 7 | 100.0 | ev | missing | missing | missing | 0.00341517 | missing |
| 4 | 100 | 6 | 12 | 12 | 100.0 | ev | missing | missing | missing | 0.00572918 | missing |
| 5 | 100 | 1 | 13 | 13 | 100.0 | ev | missing | missing | missing | 0.00308797 | missing |
Now we have two AUC values for each subject: the first dose and the last one, which are already labeled by the dosenum column.
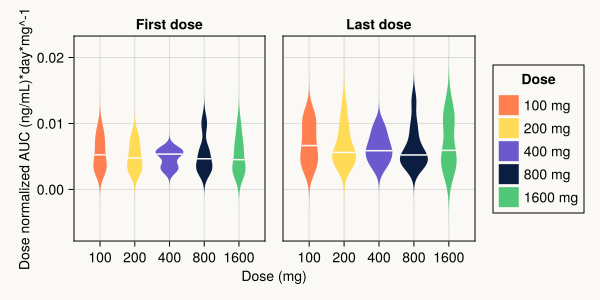
We are ready to create our violin plot and visualize the dose normalized AUC:
But let us do just one more thing before we start: we will define a renamer for the dose number column. We use the same procedure as we did for the dose renamer:
day_renamer = renamer([1 => "First dose", 6 => "Last dose"]);

plt_AUC =
    data(AUC_values) *
    mapping(
        :DOSE => nonnumeric,
        :auc0_1;
        col = :dosenum => day_renamer,
        color = :DOSE => dose_renamer => "Dose",
    ) *
    visual(Violin; show_median = true, mediancolor = background);

draw(
    plt_AUC,
    scales(Color = (; palette));
    axis = (;
        xlabel = "Dose (mg)",
        ylabel = "Dose normalized AUC (ng/mL)*day*mg^-1",
        backgroundcolor = background,
    ),
    figure = (; backgroundcolor = background, size = (600, 300)),
    legend = (; backgroundcolor = background),
)
Tip
Notice that we have included the keyword arguments show_median and mediancolor in this plot (inside of the visual call of plt_ratio), which tells AoG.jl to show the median inside of the violin plots and to give it a custom color (the background color in this case).
We encourage you to check our tutorial on Plotting Different Geometries with AlgebraOfGraphics.jl to learn more about the keyword arguments available for Violin the other geometries that Makie.jl and AoG.jl offer.
We have used a lot of customization options from AoG.jl to generate the last plot. Make sure to check our tutorial on Customization of AlgebraOfGraphics.jl Plots for a detailed explanation of how to use the nonnumeric and renamer helper functions, and also to learn more about the available keyword arguments for draw
This plot allows us to see that there isn’t a very large difference between the AUC from the first and the last dose. However, there is a better way to examine this relationship, which is by using the ratio between the tenth and the first day’s AUC.
Note
We are using the @by macro from DataFramesMeta.jl to group the data by id and then calculate the ratio.
Don’t forget to check our Data Wrangling in Julia tutorial Manipulating Tables with DataFramesMeta.jl for a more in-depth explanation on the use of DataFramesMeta.jl’s macros
AUC_ratios = @by AUC_values :id begin
    :ratio = :auc0_1[end] / :auc0_1[begin]
    :DOSE = :DOSE
end;
Let’s use a violin plot again to visualize these results:
plt_ratio =
    data(AUC_ratios) *
    mapping(:DOSE => nonnumeric, :ratio; color = :DOSE => dose_renamer => "Dose") *
    visual(Violin; show_median = true, mediancolor = background);

draw(
    plt_ratio,
    scales(Color = (; palette));
    axis = (;
        xlabel = "Dose (mg)",
        ylabel = "Fold accumulation in AUC",
        backgroundcolor = background,
    ),
    figure = (; backgroundcolor = background, size = (600, 300)),
    legend = (; backgroundcolor = background),
)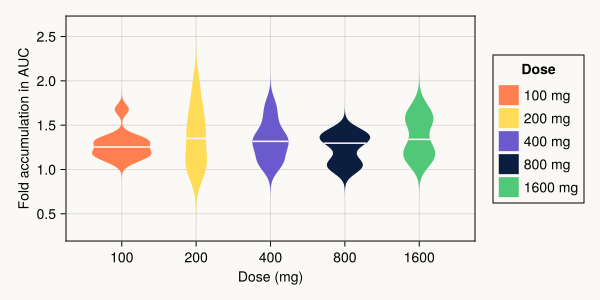
We can see here that the median of the ratio is slightly greater than 1 for all dose levels (about 1.25). This could be interpreted as an indication of accumulation.
5.2 Cₘₐₓ
Let’s now perform a similar analysis to the one we just presented for the AUC. This time, however, we will go over some of the details more quickly, so make sure to review the AUC section if anything feels unfamiliar.
Similarly to the partial AUC, the maximum concentration over a time window after the dose is the cmax_interval endpoint. Let’s use it to determine Cₘₐₓ for our data:
Tip
There are many more NCA endpoints available. Make sure to check our documentation on NCA Functions for more information.
cmax_values_all =
    run_nca(nca_data_norm, [:cmax_interval => (; interval = (0, 1)) => :cmax0_1])
first(cmax_values_all, 5)
5×10 DataFrame
| Row | DOSE | dosenum | id | profile | dose | route | duration | tau | assumed_tau | cmax0_1 |
|---|---|---|---|---|---|---|---|---|---|---|
| Int64 | Int64 | Int64 | Int64 | Float64 | String | Missing | Missing | Missing | Float64 | |
| 1 | 100 | 1 | 11 | 1 | 100.0 | ev | missing | missing | missing | 0.0118 |
| 2 | 100 | 2 | 11 | 2 | 100.0 | ev | missing | missing | missing | 0.000691 |
| 3 | 100 | 3 | 11 | 3 | 100.0 | ev | missing | missing | missing | 0.00137 |
| 4 | 100 | 4 | 11 | 4 | 100.0 | ev | missing | missing | missing | 0.0026 |
| 5 | 100 | 5 | 11 | 5 | 100.0 | ev | missing | missing | missing | 0.00125 |
Again, we’ll only keep the first and the last dose. In contrast to the AUC, Cₘₐₓ can be calculated for every dose, so instead of dropmissing! we select the two rows we want with the @by macro from DataFramesMeta.jl:
cmax_values = @by cmax_values_all :id begin
    :cmax0_1 = [:cmax0_1[begin], :cmax0_1[end]]
    :DOSE = [:DOSE[begin], :DOSE[end]]
    :dosenum = [:dosenum[begin], :dosenum[end]]
end;
Now we are ready for the violin plots. Let’s begin with visualizing Cₘₐₓ for each dose level and the first and last dose:
plt_cmax =
    data(cmax_values) *
    mapping(
        :DOSE => nonnumeric,
        :cmax0_1;
        col = :dosenum => day_renamer,
        color = :DOSE => dose_renamer => "Dose",
    ) *
    visual(Violin, show_median = true, mediancolor = background);

draw(
    plt_cmax,
    scales(Color = (; palette));
    axis = (;
        xlabel = "Dose (mg)",
        ylabel = "Dose normalized Cₘₐₓ (ng/mL)*mg^-1",
        backgroundcolor = background,
    ),
    figure = (; backgroundcolor = background, size = (600, 300)),
    legend = (; backgroundcolor = background),
)
We see that the medians are similar for both doses and across all dose levels, but there is high variability for some dose levels (e.g 400 and 1600 mg on the last dose)
Let’s now examine the ratio between Cₘₐₓ of the last and the first dose to help us assess if there is accumulation. Again, we begin by calculating the ratios using the @by macro:
cmax_ratios = @by cmax_values :id begin
    :ratio = :cmax0_1[end] / :cmax0_1[begin]
    :DOSE = :DOSE
end;
And that’s it! We can now generate our violin plot:
plt_cmax_ratio =
    data(cmax_ratios) *
    mapping(:DOSE => nonnumeric, :ratio; color = :DOSE => dose_renamer => "Dose") *
    visual(Violin; show_median = true, mediancolor = background);

draw(
    plt_cmax_ratio,
    scales(Color = (; palette));
    axis = (;
        xlabel = "Dose (mg)",
        ylabel = "Fold accumulation in Cₘₐₓ",
        backgroundcolor = background,
    ),
    figure = (; backgroundcolor = background, size = (600, 300)),
    legend = (; backgroundcolor = background),
)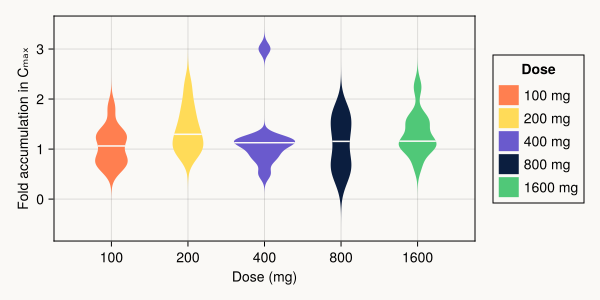
This allows us to see that the median of the ratios is close to 1, which could be an indication that there is no accumulation, but we should also notice that there is high variability, especially for the 400 mg dose level.
6 Exploring the effect of covariates
As you may have noticed, the dataset that we are using includes information about the subject’s sex and weight. We will explore the effect of these two covariates on the concentration profiles, AUC and Cₘₐₓ
6.1 Sex
We will generate the mean concentration profile for each sex. In order to do this, we will have to read the data again. However, this time we’ll specify SEX as the group variable, next to the dose number which we always need to get one profile per dose:
nca_data_sex = read_nca_pumas(
    df;
    id = :ID,
    time = :NOMTIME,
    concentration = :NLIDV,
    dose = :AMT,
    route = :ROUTE,
    group = [:SEX, :dosenum],
);
Note
We could add any number of columns to the group keyword argument. For instance, we could have done group=[:SEX, :DOSE] to let Pumas know that we want to group subjects both by sex and by dose level. However, this will result in 10 groups (cartesian product for a set of 2 categories of sex and 5 dose levels), and we want to limit this analysis to only the sex covariate.
Now let’s generate the concentration profile on a logarithmic scale following the same procedure as described above:
summary_observations_vs_time(
    @rsubset(nca_data_sex, :dosenum == 1);
    separate = false,
    group = [:SEX],
    figure = (; backgroundcolor = background),
    axis = (;
        backgroundcolor = background,
        xlabel = "Time (days)",
        ylabel = "Normalized Concentration (ng/mL)/mg",
        yscale = log10,
    ),
    color = Makie.to_colormap(:Set1_5),
    legend = (; backgroundcolor = background),
)
This allows us to see that females exhibit a higher concentration profile on average. Let’s also compute the values for AUC and Cₘₐₓ in order to examine this difference:
nca_results_sex = run_nca(@rsubset(nca_data_sex, :dosenum == 1));
Tip
This time we just used run_nca on the profiles of the first dose, because the endpoints that extrapolate to infinity, such as aucinf_obs, only make sense for a single dose.
run_nca returns a DataFrame, so we can keep the columns which we are interested in directly. That is id, SEX, cmax, and aucinf_obs:
nca_results_sex_df = @select nca_results_sex :id :SEX :cmax :aucinf_obs;Endpoints that could not be calculated are missing, and parameters_vs_group and the violin plots below cannot handle those, so we drop those rows by naming the columns we care about:
dropmissing!(nca_results_sex_df, [:cmax, :aucinf_obs]);Once again, we’ll visualize the results using violin plots. However, this time we would like to see the AUC and Cₘₐₓ results next to each other.
We will follow the same method as the one we used to create the concentration time profiles for each day: create an empty figure and place the plots on each axis.
fAUC_Cmax_sex = Figure(; backgroundcolor = background, size = (600, 300));Let’s now create the plot for the AUC and add it using draw!
plt_auc_sex =
    data(nca_results_sex_df) * mapping(:SEX, :aucinf_obs, color = :SEX) * visual(Violin);

draw!(
    fAUC_Cmax_sex[1, 1],
    plt_auc_sex,
    scales(Color = (; palette = main_colors));
    axis = (;
        xlabel = "Sex",
        ylabel = "Dose normalized AUC (ng/mL)*day*mg^-1",
        title = "AUC",
        backgroundcolor = background,
    ),
);
Now we can do the same, but for Cₘₐₓ:
plt_cmax_sex =
    data(nca_results_sex_df) * mapping(:SEX, :cmax, color = :SEX) * visual(Violin);

draw!(
    fAUC_Cmax_sex[1, 2],
    plt_cmax_sex,
    scales(Color = (; palette = main_colors));
    axis = (;
        xlabel = "Sex",
        ylabel = "Dose normalized Cₘₐₓ (ng/mL)*mg^-1",
        title = "Cₘₐₓ",
        backgroundcolor = background,
    ),
);
As always, we can check our final results by inspecting the figure (fAUC_Cmax_sex):
fAUC_Cmax_sex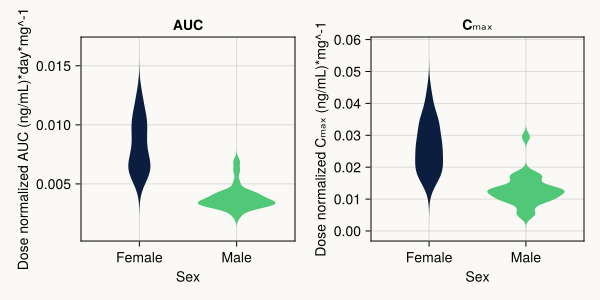
6.2 Weight
We’ll perform the same analysis as we did for the sex covariate. In order to do that, we will divide our population into those under 70 kg and those over:
@rtransform! df begin
    :WEIGHT = :WEIGHTB > 70 ? "Over 70 kg" : "Under 70 kg"
end;
Now we can read the data again. This time we set the group keyword argument to :WEIGHT, our newly created variable:
nca_data_weight = read_nca_pumas(
    df;
    id = :ID,
    time = :NOMTIME,
    concentration = :NLIDV,
    dose = :AMT,
    route = :ROUTE,
    group = [:WEIGHT, :dosenum],
);
Let’s visualize the concentration time profile for each weight group:
summary_observations_vs_time(
    @rsubset(nca_data_weight, :dosenum == 1);
    separate = false,
    group = [:WEIGHT],
    figure = (; backgroundcolor = background),
    axis = (;
        backgroundcolor = background,
        xlabel = "Time (days)",
        ylabel = "Normalized Concentration (ng/mL)/mg",
        yscale = log10,
    ),
    color = Makie.to_colormap(:Set1_5),
    legend = (; backgroundcolor = background),
)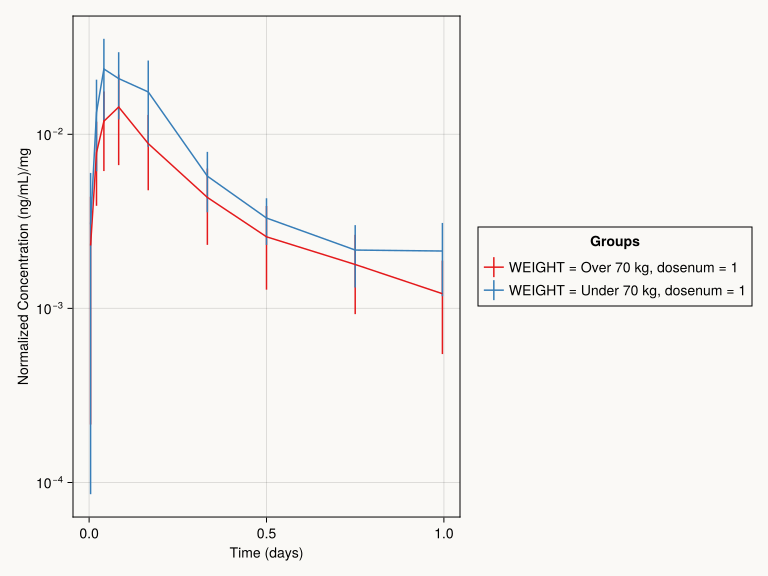
We can see here that individuals with a lower body weight tend to exhibit higher concentration profiles. We could generate the violin plots for the AUC and Cₘₐₓ by following the same procedure as before, but we’ll leave it here since we already went over that.
7 Exploring both covariates simultaneously
For our last visualization, let’s combine both covariates in a single analysis. To do this, we will plot AUC and Cₘₐₓ against body weight, and we will also examine if there are differences related to sex.
Let’s start by reading the data specifying the two groups we are interested in: SEX and WEIGHTB.
nca_data_sex_weight = read_nca_pumas(
    df;
    id = :ID,
    time = :NOMTIME,
    concentration = :NLIDV,
    dose = :AMT,
    route = :ROUTE,
    group = [:SEX, :WEIGHTB, :dosenum],
);
Again, we calculate the AUC and Cₘₐₓ with run_nca. We’ll follow the same procedure as in the AUC section: select the appropriate columns, remove missing values and plot the results next to each other.
nca_results_sex_weight = run_nca(@rsubset(nca_data_sex_weight, :dosenum == 1));@select! nca_results_sex_weight :id :SEX :WEIGHT = :WEIGHTB :cmax :aucinf_obs;
dropmissing!(nca_results_sex_weight, [:cmax, :aucinf_obs]);Now we are ready to generate the plots. Let’s start by creating the Figure:
fig_two_cov = Figure(; backgroundcolor = background, size = (600, 300));Now we create the AUC plot and add it to the Figure:
auc_plot =
    data(nca_results_sex_weight) *
    mapping(:WEIGHT, :aucinf_obs; color = :SEX => "Sex") *
    (visual(Scatter) + AlgebraOfGraphics.linear());

auc = draw!(
    fig_two_cov[1, 1],
    auc_plot,
    scales(Color = (; palette = main_colors));
    axis = (;
        backgroundcolor = background,
        xlabel = "Weight (kg)",
        ylabel = "Dose normalized AUC (ng/mL)*day*mg^-1",
        title = "AUC",
    ),
);
The plot for Cₘₐₓ can be created with a very similar procedure:
cmax_plot =
    data(nca_results_sex_weight) *
    mapping(:WEIGHT, :cmax; color = :SEX => "Sex") *
    (visual(Scatter) + AlgebraOfGraphics.linear());

cmax = draw!(
    fig_two_cov[1, 2],
    cmax_plot,
    scales(Color = (; palette = main_colors));
    axis = (;
        backgroundcolor = background,
        xlabel = "Weight (kg)",
        ylabel = "Dose normalized Cₘₐₓ (ng/mL)*mg^-1",
        title = "Cₘₐₓ",
    ),
);
Let’s add a legend for a finishing touch. This will also allow us to differentiate the data for each sex.
legend!(
    fig_two_cov[end+1, 1:2],
    cmax;
    orientation = :horizontal,
    tellheight = true,
    backgroundcolor = background,
);
Following what he have done before, we inspect the Figure (fig_two_cov) to check our results:
fig_two_cov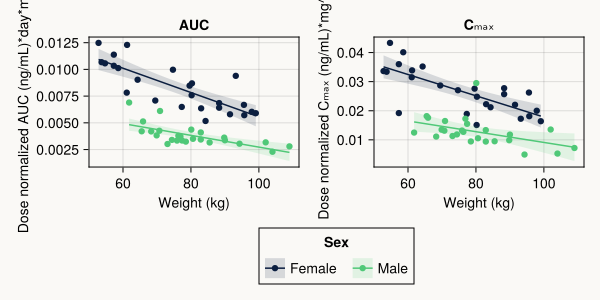
This plot lets us see that, on average, AUC and Cₘₐₓ decrease as the person’s weight increases, and that these metrics generally have a higher value for female subjects than for male subjects of the same weight. However, we can also see that there is some variability, especially for the AUC values.
8 Real world data
In this second section of the tutorial, we will also be performing an NCA, but this time we will be using real-world data from a multiple dose project carried out by Novartis.
You’ll find that the process is very similar to what we have done before, we’ll just need to be more careful during our data wrangling section.
Note
This tutorial section of the tutorial is based on Andy Stein’s PK - Multiple Ascending Dose - Using Novartis dzz file workflow. You can get the dataset used in this tutorial here.
8.1 Load Data
Again, we use CSV.jl to read the data and convert it to a DataFrame. This time, however, we included the empty string ("") in the missingstring keyword argument:
df_novartis = CSV.read("dzz_PKConc.csv", DataFrame; missingstring = ["NA", ""])
first(df_novartis, 5)
5×7 DataFrame
| Row | SUBJID | ARM | VISIT | PCDTC | TMTPT | RESN | RESU |
|---|---|---|---|---|---|---|---|
| Int64 | String | String15 | DateTime? | Int64? | Float64? | String7 | |
| 1 | 1000001 | Phase I ABC123 240mg Q2W | CYCLE 4 DAY 1 | missing | 0 | 80.8 | ug/mL |
| 2 | 1000001 | Phase I ABC123 240mg Q2W | CYCLE 1 DAY 1 | 2016-03-10T10:40:00 | 0 | 0.0 | ug/mL |
| 3 | 1000001 | Phase I ABC123 240mg Q2W | CYCLE 1 DAY 1 | 2016-03-10T12:45:00 | 1 | 103.0 | ug/mL |
| 4 | 1000001 | Phase I ABC123 240mg Q2W | CYCLE 1 DAY 2 | 2016-03-11T12:00:00 | 24 | 84.1 | ug/mL |
| 5 | 1000001 | Phase I ABC123 240mg Q2W | CYCLE 1 DAY 8 | 2016-03-18T11:15:00 | 168 | 39.8 | ug/mL |
8.1.1 Data wrangling
Since this time we are not using simulated data, we will need to do some additional work to get the dataset ready for our analysis and to use read_nca.
In order to save some space, we will be using the @chain macro to perform all of our data wrangling operations in one go. Here’s a broad overview of what we will be doing:
- Extract dose and regimen information from
ARMcolumn. - Extract cycle information from
VISITcolumn. - Remove
missingvalues from date column (PCDTC). - Compute the time column from the dates (convert milliseconds to days).
- Identify rows where the time is repeated.
- Eliminate rows where there are repeated times.
- Add the route of administration, which NCA.jl requires and the dataset does not contain.
df_novartis_clean = @chain df_novartis begin

    @rtransform @astable begin
        arm_information = split(:ARM, " ")
        :regimen = arm_information[end] # extract regimen

        dose = chop(arm_information[end-1], tail = 2) # extract dose
        :Dose = parse(Int, dose)
    end

    @rtransform @astable begin
        visit_information = split(:VISIT, " ")
        :cycle = visit_information[2]
    end

    @rsubset begin
        !ismissing(:PCDTC) # remove missing dates
    end

    @by :SUBJID @astable begin
        TIME = :PCDTC .- first(:PCDTC) # calculate time
        :time = [i.value / (1000 * 60 * 60 * 24) for i in TIME] # convert milliseconds to days

        :Dose = :Dose
        :conc = :RESN
        :regimen = :regimen
        :cycle = :cycle
    end

    @by [:SUBJID, :time] begin
        :unique = allunique(:time) # identify repeated times

        :Dose = first(:Dose)
        :conc = first(:conc)
        :regimen = first(:regimen)
        :cycle = first(:cycle)
    end

    @rsubset begin
        :unique == true # eliminate repeated times
    end

    # the dataset carries no route information, we analyze it as extravascular
    @rtransform :route = "ev"

end
first(df_novartis_clean, 5)
5×8 DataFrame
| Row | SUBJID | time | unique | Dose | conc | regimen | cycle | route |
|---|---|---|---|---|---|---|---|---|
| Int64 | Float64 | Bool | Int64 | Float64? | SubStrin… | SubStrin… | String | |
| 1 | 1000001 | 0.0 | true | 240 | 0.0 | Q2W | 1 | ev |
| 2 | 1000001 | 0.0868056 | true | 240 | 103.0 | Q2W | 1 | ev |
| 3 | 1000001 | 1.05556 | true | 240 | 84.1 | Q2W | 1 | ev |
| 4 | 1000001 | 8.02431 | true | 240 | 39.8 | Q2W | 1 | ev |
| 5 | 1000001 | 11.066 | true | 240 | 38.1 | Q2W | 1 | ev |
8.2 Concentration time profiles
8.2.1 Dose and regimen
We will examine the concentration time profiles for each regimen (Q2W and Q4W). To do this, we must start by creating each population, so we’ll have to divide it according to the regimen column:
q2w_data = @rsubset df_novartis_clean :regimen == "Q2W";
q4w_data = @rsubset df_novartis_clean :regimen == "Q4W";
Now we use read_nca to read the data required for the plotting functions. This dataset carries the same dose on every row of a profile, which is the layout read_nca expects:
q2w_population = read_nca(
    q2w_data;
    id = :SUBJID,
    concentration = :conc,
    dose = :Dose,
    route = :route,
    group = [:Dose],
);
q4w_population = read_nca(
    q4w_data;
    id = :SUBJID,
    concentration = :conc,
    dose = :Dose,
    route = :route,
    group = [:Dose],
);
Note
The dose level is written as :Dose because dose is reserved for the dose column of the NCA data and may not be used as a group name.
As before, we use summary_observations_vs_time to visualize the mean concentration for each dose level:
fig_dose_regimen = Figure(; backgroundcolor = background);summary_observations_vs_time(
fig_dose_regimen[1, 1],
q2w_population;
separate = false,
axis = (;
backgroundcolor = background,
xlabel = "Time (days)",
ylabel = "Concentration (ng/mL)",
title = "Q2W",
yscale = log10,
),
color = Makie.to_colormap(:Set1_5),
errorbars = false,
);fgrid = summary_observations_vs_time(
fig_dose_regimen[1, 2],
q4w_population;
separate = false,
axis = (;
backgroundcolor = background,
xlabel = "Time (days)",
ylabel = "Concentration (ng/mL)",
title = "Q4W",
yscale = log10,
),
color = Makie.to_colormap(:Set1_5),
errorbars = false,
);legend!(
fig_dose_regimen[end+1, :],
fgrid;
orientation = :horizontal,
backgroundcolor = background,
);fig_dose_regimen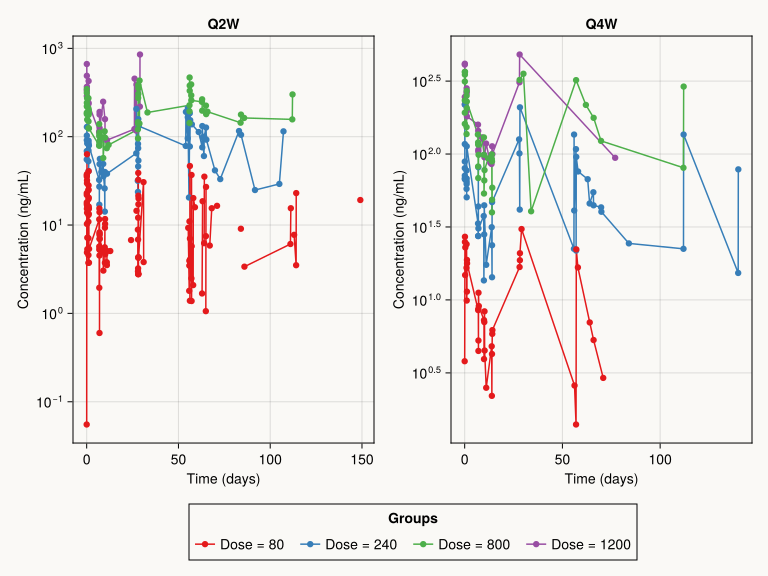
We can see that this time the concentration profiles aren’t as good looking as before, as we are using real measurements instead of simulated data.
Note
This time we went over the process of creating each plot and adding it to the figure really fast. If you feel unsure about anything, please refer to the earlier section on exploring concentration time profiles for each dose level for a more detailed explanation.
8.2.2 Dose, regimen and cycle
Here, we will include the cycle in the analysis. We’ll take advantage of the cycle column we created before to create an NCAPopulation for both regimens and cycles 1 and 3
We start by the Q2W regimen:
q2w_1 = @rsubset q2w_data :cycle == "1";
q2w_1_population = read_nca(
    q2w_1;
    id = :SUBJID,
    concentration = :conc,
    dose = :Dose,
    route = :route,
    group = [:Dose],
);
q2w_3 = @rsubset q2w_data :cycle == "3";
q2w_3_population = read_nca(
    q2w_3;
    id = :SUBJID,
    concentration = :conc,
    dose = :Dose,
    route = :route,
    group = [:Dose],
);
Now we do the same for the Q4W regimen:
q4w_1 = @rsubset q4w_data :cycle == "1";
q4w_1_population = read_nca(
    q4w_1;
    id = :SUBJID,
    concentration = :conc,
    dose = :Dose,
    route = :route,
    group = [:Dose],
);
q4w_3 = @rsubset q4w_data :cycle == "3";
q4w_3_population = read_nca(
    q4w_3;
    id = :SUBJID,
    concentration = :conc,
    dose = :Dose,
    route = :route,
    group = [:Dose],
);
We can use the same procedure as before to create our plot colored by dose and faceted by both regimen and cycle:
fig_dose_regimen_cycle = Figure(; backgroundcolor = background);# the legend is taken from this plot because only cycle 1 has all four dose levels
fgrid = summary_observations_vs_time(
fig_dose_regimen_cycle[1, 1],
q2w_1_population;
separate = false,
axis = (;
backgroundcolor = background,
xlabel = "Time (days)",
ylabel = "Concentration (ng/mL)",
title = "Q2W - Cycle 1",
yscale = log10,
),
color = Makie.to_colormap(:Set1_5),
errorbars = false,
);summary_observations_vs_time(
fig_dose_regimen_cycle[1, 2],
q4w_1_population;
separate = false,
axis = (;
backgroundcolor = background,
xlabel = "Time (days)",
ylabel = "Concentration (ng/mL)",
title = "Q4W - Cycle 1",
yscale = log10,
),
color = Makie.to_colormap(:Set1_5),
errorbars = false,
);summary_observations_vs_time(
fig_dose_regimen_cycle[2, 1],
q2w_3_population;
separate = false,
axis = (;
backgroundcolor = background,
xlabel = "Time (days)",
ylabel = "Concentration (ng/mL)",
title = "Q2W - Cycle 3",
yscale = log10,
),
color = Makie.to_colormap(:Set1_5),
errorbars = false,
);summary_observations_vs_time(
fig_dose_regimen_cycle[2, 2],
q4w_3_population;
separate = false,
axis = (;
backgroundcolor = background,
xlabel = "Time (days)",
ylabel = "Concentration (ng/mL)",
title = "Q4W - Cycle 3",
yscale = log10,
),
color = Makie.to_colormap(:Set1_5),
errorbars = false,
);legend!(
fig_dose_regimen_cycle[:, end+1],
fgrid;
orientation = :vertical,
backgroundcolor = background,
);Here’s the final result:
fig_dose_regimen_cycle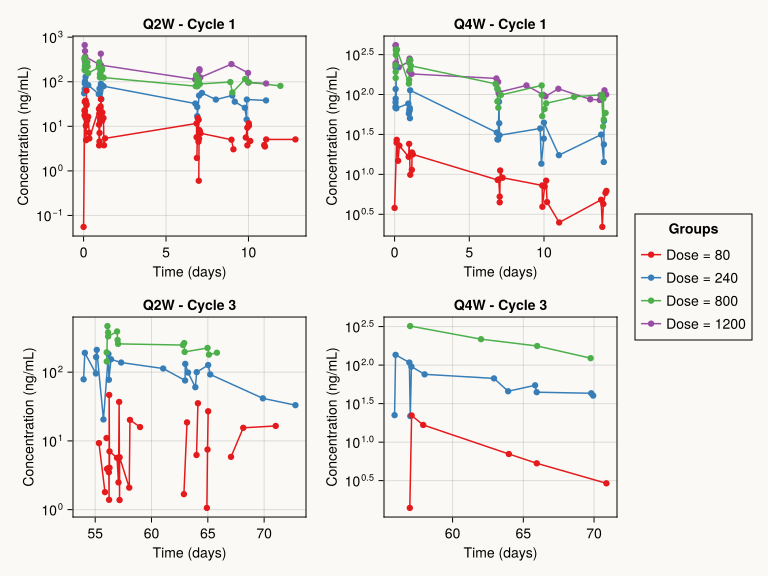
8.3 Subject variability
Similarly to what we did before, we will generate the concentration time profile for each subject in the population in order to investigate subject variability.
However, this time we would like to be able to tell the dose level and regimen for each subject, so we write them into the subject label and use that as the id:
df_novartis_labeled =
    @rtransform df_novartis_clean :subject = "$(:SUBJID) ($(:Dose) mg $(:regimen))"

population_indicator = read_nca(
    df_novartis_labeled;
    id = :subject,
    concentration = :conc,
    dose = :Dose,
    route = :route,
);
observations_vs_time draws one axis per subject, which is what we want here. summary_observations_vs_time, which we used above, summarizes across the subjects of a group instead:
grouped_observations = observations_vs_time(
    population_indicator;
    paginate = true,
    limit = 9,
    markercolor = main_colors[1],
    color = main_colors[2],
    axis = (;
        backgroundcolor = background,
        xlabel = "Time (days)",
        ylabel = "Concentration (ng/mL)",
        yscale = log10,
    ),
    figure = (; backgroundcolor = background, size = (1800, 1200), fontsize = 20),
);

grouped_observations[1]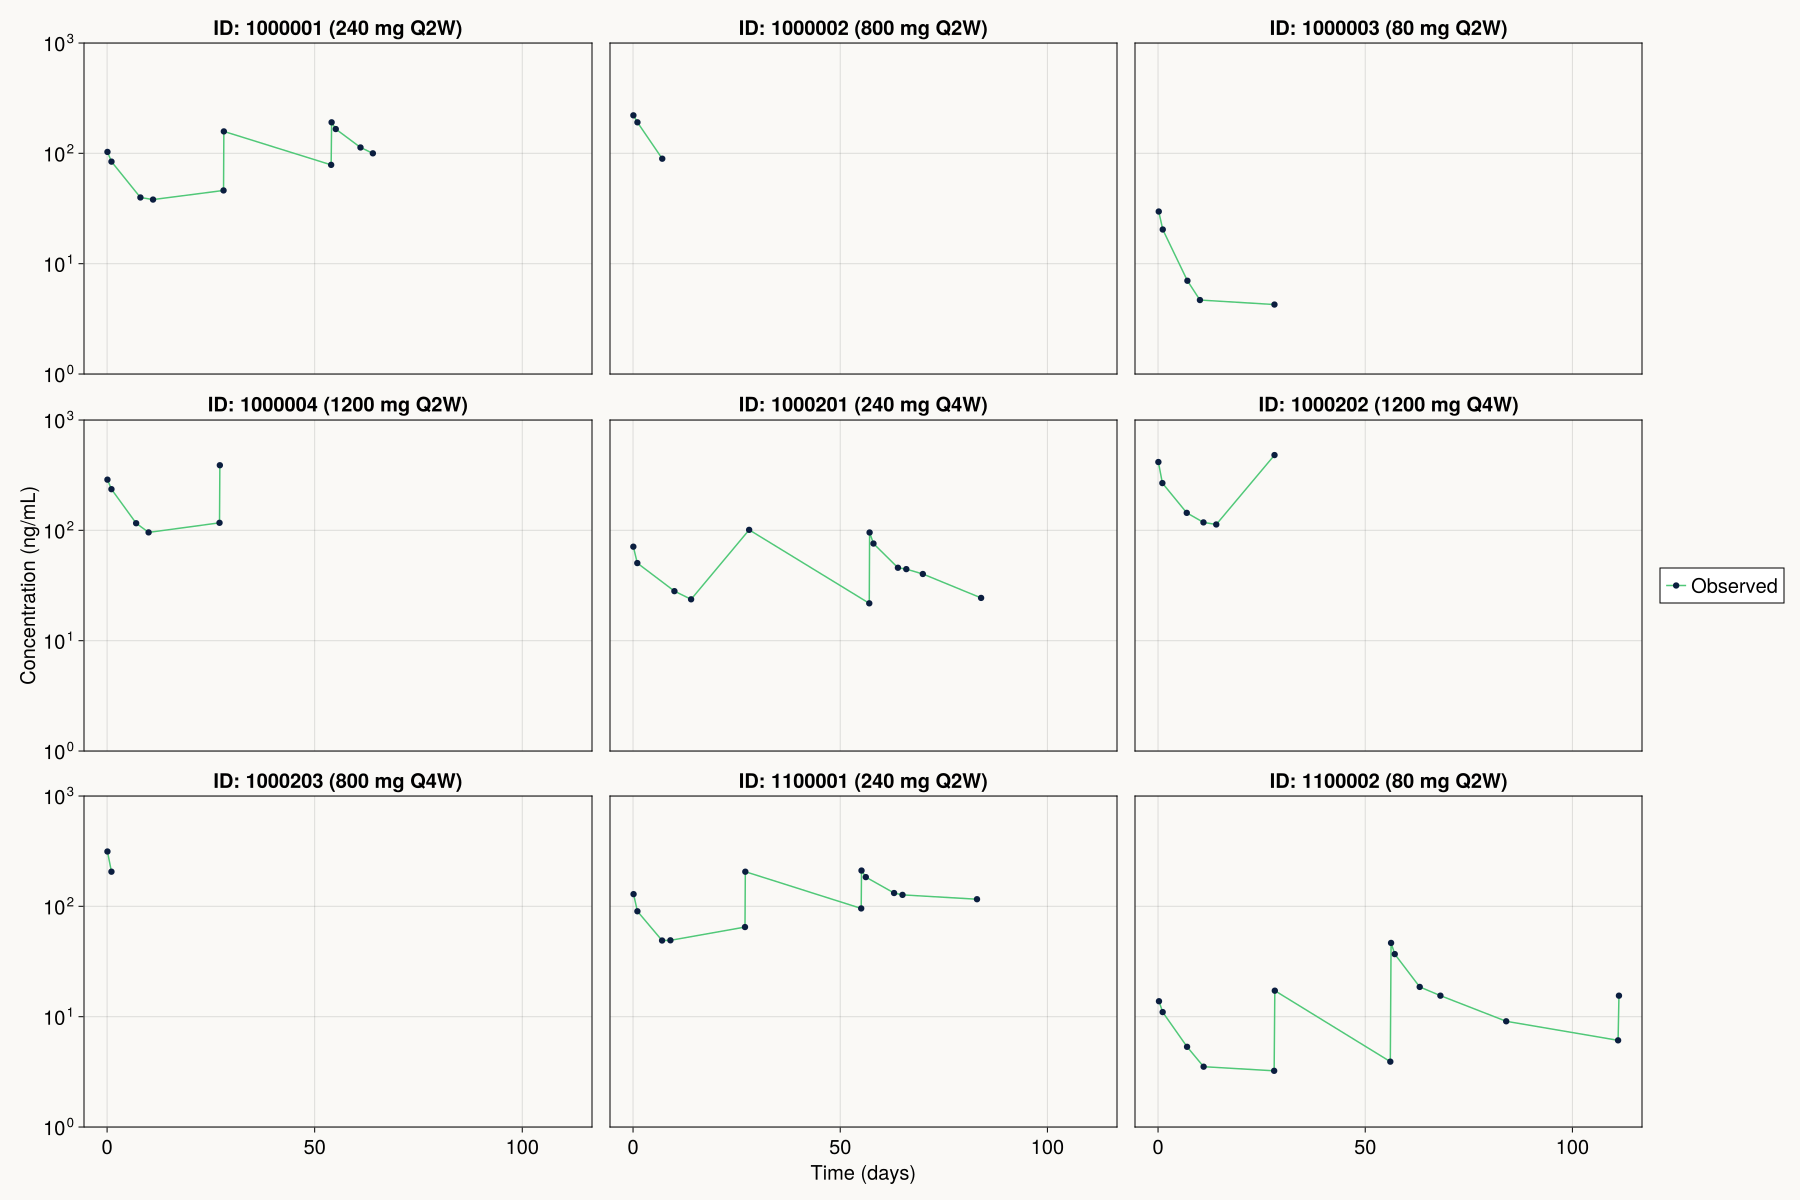
9 Dose normalized concentration
As before, we need to begin our analysis by determining the dose normalized concentration. Once again, we will consider the differences between regimens, so we must compute the dose normalized concentration for each case
@rtransform! q2w_data begin
    :nconc = :conc / :Dose
end;

@rtransform! q4w_data begin
    :nconc = :conc / :Dose
end;
Now we create the new NCAPopulations, but this time we specify the observations to be the normalized concentration:
nq2w = read_nca(
    q2w_data;
    id = :SUBJID,
    concentration = :nconc,
    dose = :Dose,
    route = :route,
    group = [:Dose],
);
nq4w = read_nca(
    q4w_data;
    id = :SUBJID,
    concentration = :nconc,
    dose = :Dose,
    route = :route,
    group = [:Dose],
);
We’ll start by observing the dose normalized concentration profiles for each regimen. You’ll notice that the code will be virtually the same as the one we used above, we just change the NCAPopulation passed to summary_observations_vs_time:
fig_dose_regimen_norm = Figure(; backgroundcolor = background);summary_observations_vs_time(
fig_dose_regimen_norm[1, 1],
nq2w;
separate = false,
axis = (;
backgroundcolor = background,
xlabel = "Time (days)",
ylabel = "Normalized Concentration (ng/mL)/mg",
title = "Q2W",
yscale = log10,
),
color = Makie.to_colormap(:Set1_5),
errorbars = false,
);fgrid = summary_observations_vs_time(
fig_dose_regimen_norm[1, 2],
nq4w;
separate = false,
axis = (;
backgroundcolor = background,
xlabel = "Time (days)",
ylabel = "Concentration (ng/mL)/mg",
title = "Q4W",
yscale = log10,
),
color = Makie.to_colormap(:Set1_5),
errorbars = false,
);legend!(
fig_dose_regimen_norm[end+1, :],
fgrid;
orientation = :horizontal,
backgroundcolor = background,
);fig_dose_regimen_norm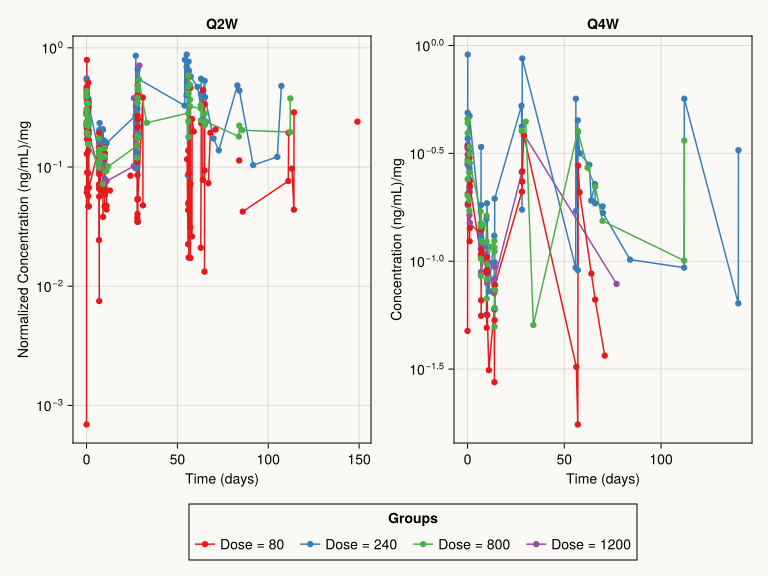
9.1 AUC and Cₘₐₓ
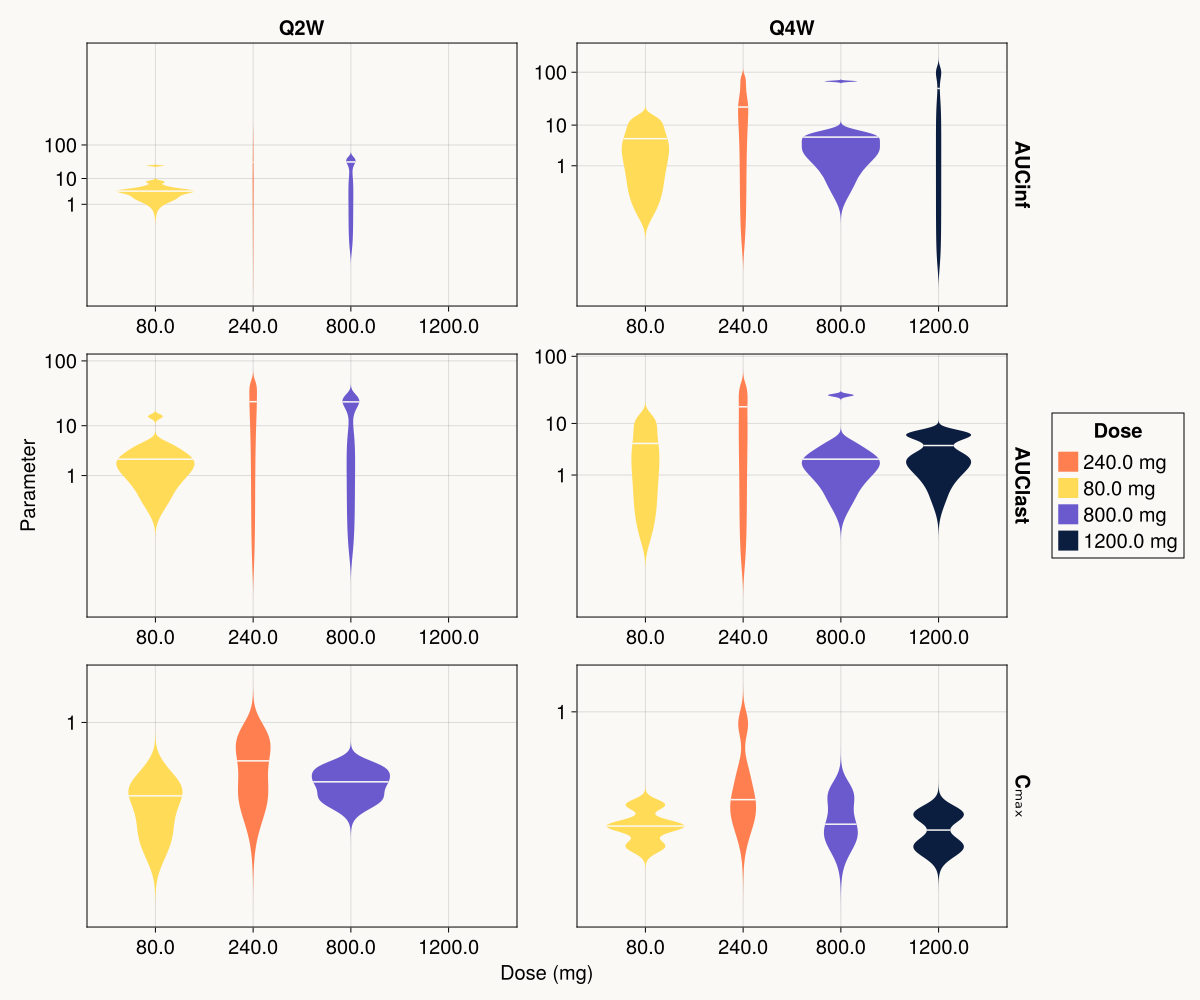
Our last plot will be a visualization for the AUC and Cₘₐₓ. We will create violin plots for different types of AUC and for the Cₘₐₓ.
In this case, it will be more convenient to have a population with both mixed in (consider all subjects at once) since we will be generating the plot manually using AoG.jl. Let’s start by creating the normalized concentration column:
@rtransform! df_novartis_clean begin
    :nconc = :conc / :Dose
end;
Now we can create the population with read_nca. Note that we specified both :Dose and :regimen as our grouping variables:
population = read_nca(
    df_novartis_clean;
    id = :SUBJID,
    concentration = :nconc,
    dose = :Dose,
    route = :route,
    group = [:Dose, :regimen],
);
Having created the population, we can calculate our parameters using run_nca:
report = run_nca(population, [:aucinf_obs, :auclast, :cmax]);
Tip
You can pass a vector of endpoints as the second argument of run_nca to specify which of Pumas’ very extensive list of NCA endpoints you would like to include in your results.
Of course, you could omit this argument and run_nca will provide all relevant endpoints, which is what we have been doing so far.
dropmissing!(report, [:aucinf_obs, :auclast, :cmax]);
Note
Notice that run_nca produces a DataFrame in a long format. However, it would be more convenient to have it in a wide format since we want to produce a plot faceted by the type of parameter calculated (aucinf_obs, auclast, and cmax).
We could definitely use DataFramesMeta.jl’s stack function to create a wide version of the data as follows:
report_wide = stack(report)But AoG.jl has the ability to deal with long and wide formats without the need for data wrangling, so we are going to take advantage of that here. Make sure to check our tutorials on Reshaping DataFrames and Wide Data with AlgebraOfGraphics.jl to learn more about this.
dose_renamer_novartis = renamer(map(i -> i => "$(i) mg", unique(report.dose)));plt_metrics =
data(report) *
mapping(
:dose => nonnumeric => "Dose (mg)",
[:aucinf_obs, :auclast, :cmax] .=> "Parameter",
) *
mapping(;
color = :dose => dose_renamer_novartis => "Dose",
col = :regimen,
row = dims(1) => renamer(["AUCinf", "AUClast", "Cₘₐₓ"]),
) *
visual(Violin; show_median = true, mediancolor = background);draw(
plt_metrics,
scales(Color = (; palette));
figure = (; backgroundcolor = background, size = (1200, 1000), fontsize = 20),
axis = (;
backgroundcolor = background,
yscale = Makie.pseudolog10,
yticks = map(i -> 10.0^i, 0:2),
),
legend = (; backgroundcolor = background),
facet = (; linkxaxes = :none, linkyaxes = :none),
)
Tip
You can use linkxaxes and linkyaxes inside of the facet keyword argument to tell AoG.jl that the axis limits should be different for each plot.
This can be useful when plotting variables with very different ranges, such as AUC and Cₘₐₓ in this case.
10 Conclusions
We are continuing with our tutorials on Plot Customization. This time we analyzed more complex situations than the one we previously discussed in Plot customization for Noncompartmental analysis - Single Ascending Dose, which gave us the opportunity to consider new visualization options such as comparing two different periods of time in the concentration time profile. Lastly, we were also able to explore some of the endpoints that the NCA package offers, such as auc_partial for the AUC over a time window and cmax_interval for the maximum concentration in it.
As always, we encourage you to check our documentation on plotting. You’ll find that this is the most complete source of information for Pumas’ plotting capabilities. Don’t forget to check the documentation for Makie.jl and our tutorials on data visualization in Julia to get more information on the available customization options for things like figures and axes.